
5 min
 Safety of artificial intelligence systems has become more important as great advancements are done in the field of machine intelligence. The Safety Research team at DeepMind has put together a framework to build safe AI systems. Comparing AI systems to a rocket, DeepMind researchers said that everyone who “rides the rocket” will also enjoy the fruits of great AI. Also like rockets safety is one of the most important ingredients of building good AI. The team says that guaranteeing safety is paramount and requires carefully designing a system from the ground up.
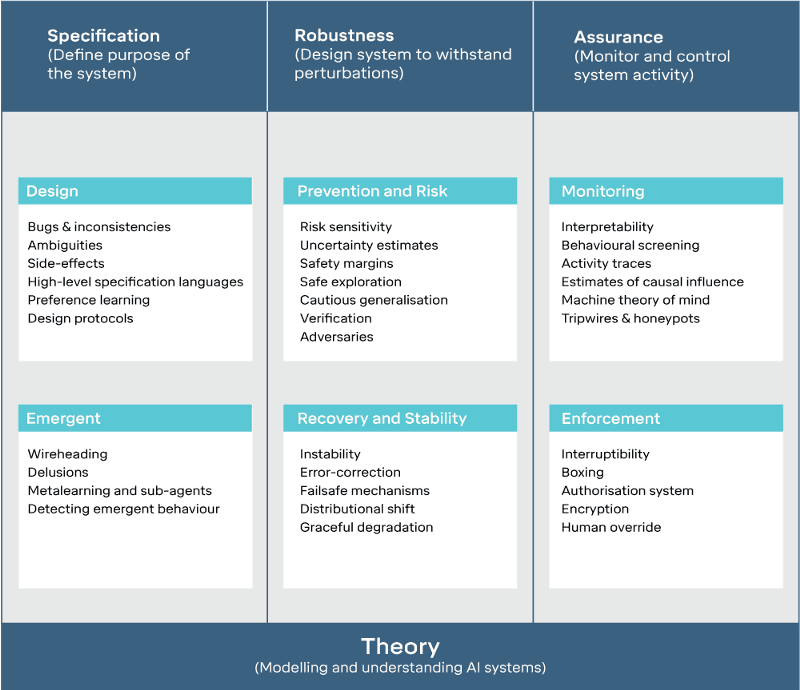
The safety research team has therefore focussed on building systems that are very reliable and work as advertised. They also work on discovering and avoiding possible near-term and long-term risks in AI. DeepMind is one of the very few organisations that works on Technical AI safety and the field is rapidly evolving. The work is mostly theoretical and high level but contains technical ideas that could be used in the design of practical systems. They published a research article that talks about the three most important aspects of AI safety:
- Specification
- Robustness
- Assurance
Specification: Define The Purpose
The team at DeepMind talks at length about the relation of the Greek mythological character King Midas and the importance of specification. “This story illustrates the problem of the specification: how do we state what we want? The challenge of the specification is to ensure that an AI system is incentivised to act in accordance with the designer’s true wishes, rather than optimising for a poorly-specified goal or the wrong goal altogether.” The research talks about three types of specifications:- Ideal specification (the “wishes”), this is the system that is ideal and adheres to the wishes of its human master
- Design specification (the “blueprint”), this is the specification which is used at the time of actually building the system in a particular use case
- Revealed specification (the “behaviour”), this is the specification that tells us what are the results and the resultant behaviour of the system that was built using the design specification
Robustness: Withstand Perturbations
The system designers and AI researchers have to plan for uncertainties, events and eventualities and take preventive actions against them. This means the AI systems should be robust against many uncertain events and even adversarial attacks that can cause damage or try to manipulate AI systems. Research on robustness limits AI and focus on narrow tasks. Whatever the conditions, the AI is therefore required to stay within its action boundaries. The researchers outline some direction like “prevention” to avoid risks and “recovery” to self-stabilisation and graceful degradation. Researchers have also identified some problems like distributional shift, adversarial inputs, and unsafe exploration. Unsafe exploration tries to maximise agent’s performance and attain goals without taking the total safety into consideration.
Assurance: Monitor And Control
The last step in the three steps in assurance since it is important to monitor and adjust AI systems. There are two angles that researchers explore: monitoring and enforcing. As the paper underlines: Monitoring concerns itself with methods for inspecting systems in order to analyse and predict their behaviour, using statistics and programmed automation. And enforcement concerns itself with designing mechanisms for controlling and restricting the behaviour of systems. Problems like interpretability and interruptibility also fall under monitoring and enforcement respectively. Here, interpretability means building programs that are well-designed measurement tools and protocols allow the assessment of the quality of the decisions made by an AI system. In conclusion, the researchers say, “We look forward to continuing to make exciting progress in these areas, in close collaboration with the broader AI research community, and we encourage individuals across disciplines to consider entering or contributing to the field of AI safety research.”- AI Can Be Cyborg or Centaur. But Can Enterprises Monetise It?
- AMD’s Server CPU Business Faces a New AI Boom
- How an Engineer Is Using AI to Bridge the Accessible Education Gap
- AI Agents are Making Human Customer Service a Specialist Job
- Why Nandan Nilekani-Backed F2A Believes India's Investment Opportunity Lies in Edge AI
- India Needs to Build the AI 'Brain' for Robotics, Not Just Import Hardware