Key takeaways
- Google AI's Switch Transformers model, a Mixture of Experts model, is now available on HuggingFace.
- The model features 1.6 trillion parameters and offers highly efficient scalable properties in natural language processing.
- Switch Transformers excel in natural language tasks, significantly increasing speed compared to previous models like T5.
- The architecture allows for individual token processing by different MLPs, enhancing performance in training regimes.
- Pre-trained model weights require fine-tuning for specific projects, with a demo available for text summarisation.
Google AI’s Switch Transformers model, a Mixture of Experts (MoE) model, that was released a few months ago is now available on HuggingFace. The model scales up to 1.6 trillion parameters and is now openly accessible.
Click here to check out the model on HuggingFace.
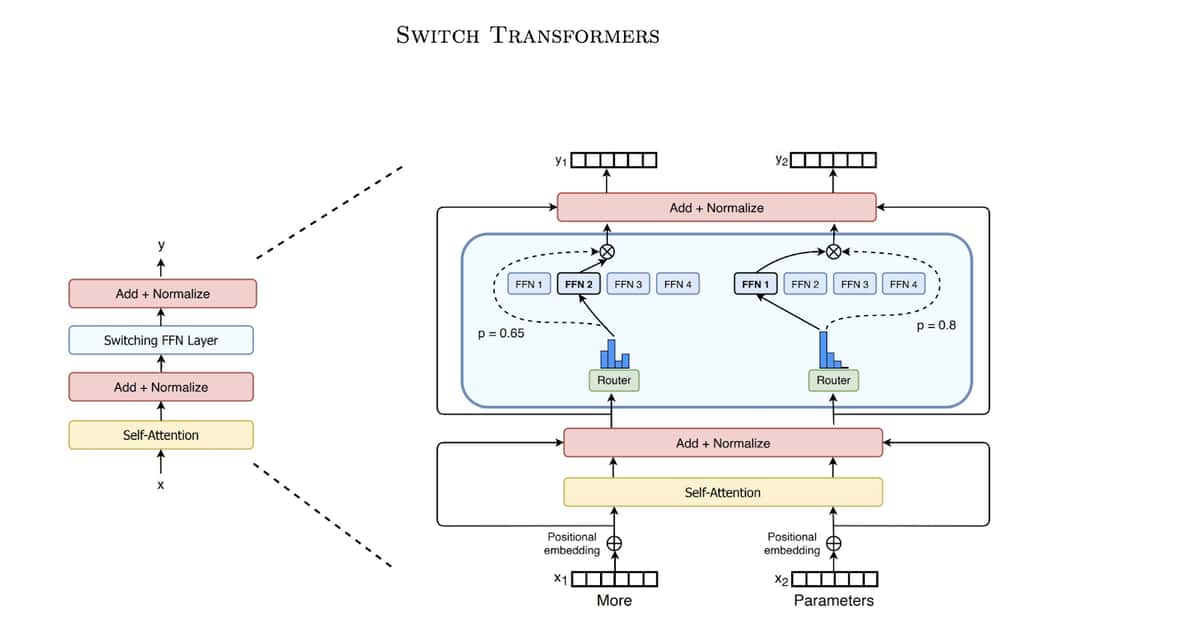
MoE models are considered to be the next step of Natural Language Processing (NLP) architectures that have highly efficient scalable properties. The architecture is considered similar to the classic T5 model, with a Feed Forward layer getting replaced by a Sparse Feed Forward Layer. Individual tokens are processed by different MLPs guided by the router module.
Younes Belkada from HuggingFace said, “The architecture can build on research for the next generation of NLP models including GPT-4.”
Read: GPT-4 is almost here, and it looks better than anything else
The weights of the model are pre-trained and require fine-tuning before using them for projects. HuggingFace has also released a demo on how to fine-tune an MoE model on text summarisation that you can check out here.
What are Switch Transformers? Switch Transformers are effective natural language learners that are highly scalable. Simplifying MoE makes the models excel in natural language tasks in all the training regimes, allowing the model to be trained on billions to trillions of parameters, and substantially increasing the speed when compared to T5 baselines.
You can also check out the documentation about SwitchTransformers on HuggingFace website.
Click here to read the paper by Google AI on Switch Transformers: Scaling to Trillion Parameter Models with Simple and Efficient Sparsity.