
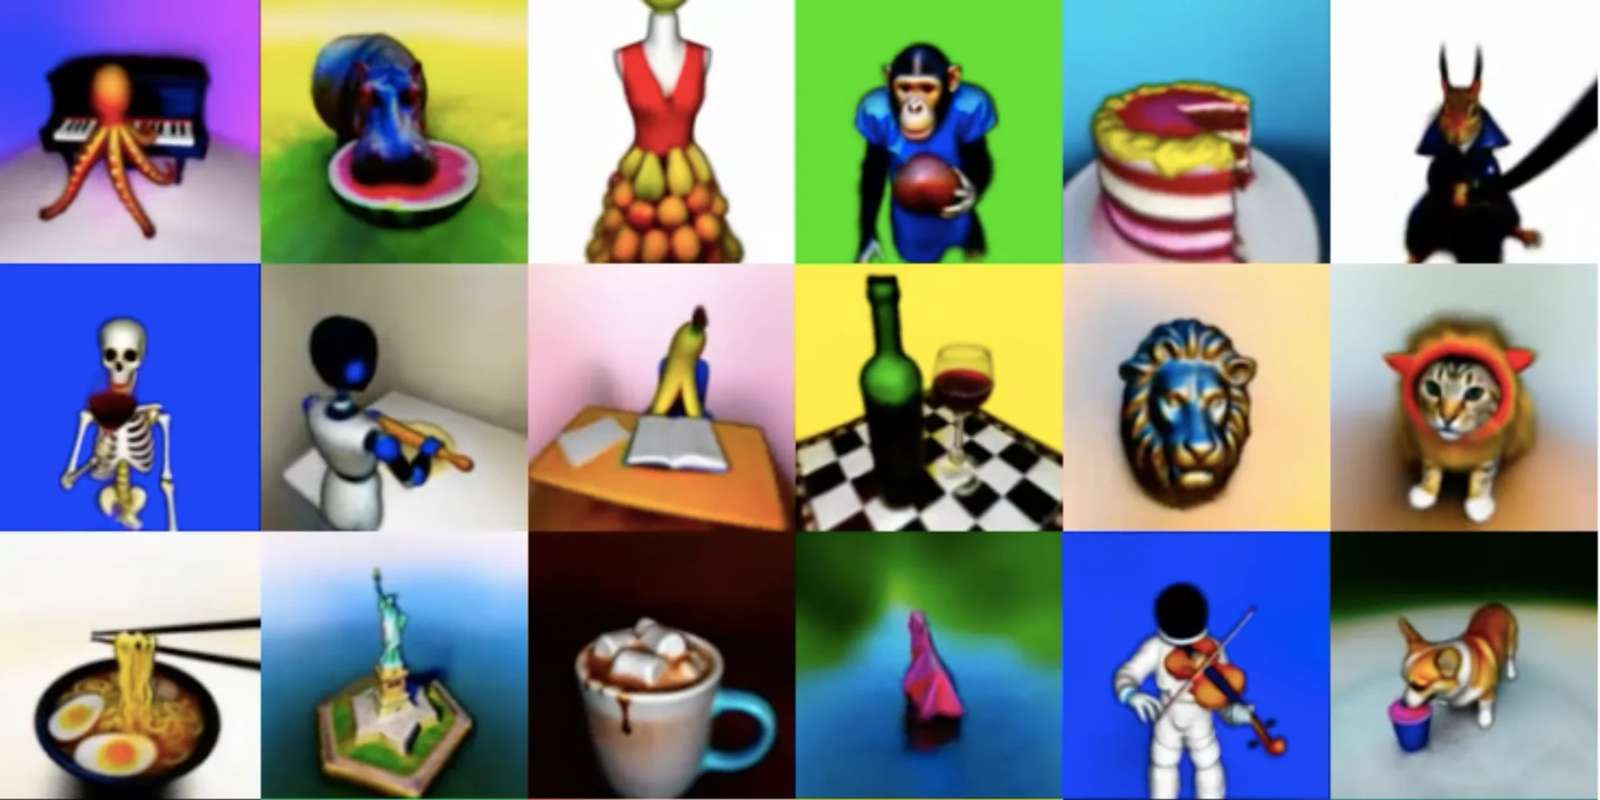
A group of researchers from Google have adapted a new approach to 3D synthesis. Users can now generate 3D models with text prompts as input. The new method, called ‘DreamFusion’, uses 2D Diffusion and is set to bring notable advancements to text-to-image synthesis.
Typically, advancements in AI generative systems are driven by diffusion models that are trained on billions of image-text pairs. Researchers claim that such an adaptation of 3D model synthesis would require large-scale datasets of labelled 3D assets and efficient architectures for de-noising 3D data—neither of which currently exist. Instead, the team circumvented such limitations to use a pre-trained 2D text-to-image diffusion model that performs text-to-3D synthesis.
The researchers optimised a randomly-initialised 3D model called ‘NeRF’ (a Neural Radiance Field) via gradient descent so that the renderings in 2D from random angles achieve lesser loss.
An excerpt from the blog says, “The resulting 3D model of the given text can be viewed from any angle, relit by arbitrary illumination, or composited into any 3D environment. Our approach requires no 3D training data and no modifications to the image diffusion model, demonstrating the effectiveness of pretrained image diffusion models as priors.”

How does it work?
A text-to-image generative model called ‘Imagen’ is used to optimise a 3D scene. The research also proposes Score Distillation Sampling (SDS)—a way to generate samples from a diffusion model by optimising a loss function—allowing users to optimise samples in an arbitrary parameter (3D) space.
A 3D scene parameterization, similar to Neural Radiance Fields or NeRFs, is used to define the differentiable mapping. While SDS produces reasonable scene appearance, DreamFusion instils additional regularisers and optimisation strategies to improve geometry. The resultant trained NeRFs are coherent—with surface geometry and high-quality normals.
- IIIT Hyderabad and NPCI Sign MoU to Strengthen Cybersecurity in Digital Payments
- KPIT Bets on AI for Margin Growth as Q2 Revenue Growth Stays Weak
- Akamai Launches AI Inference and Agent Sandbox Services
- OpenAI Sued Over ChatGPT’s Alleged Role in Woman’s Death After Seizure Medication Taper
- Live2.ai Raises ₹130 Cr in Pre-Series B Round Led by IvyCap Ventures
- LTM Launches Dedicated Unit to Build and Operate GCCs in India