
Alibaba’s Qwen team introduced the Qwen3-VL series on September 23, calling it the most advanced vision-language line in its portfolio. The release includes the open-sourcing of its flagship model, Qwen3-VL-235B-A22B, in both Instruct and Thinking versions. The focus is on moving visual AI from simple recognition towards deeper reasoning and execution.
The models are designed to combine text and visual understanding at scale, with native support for 2,56,000 tokens of context, expandable to one million. This allows processing of entire textbooks or hours of video while maintaining near-perfect recall.
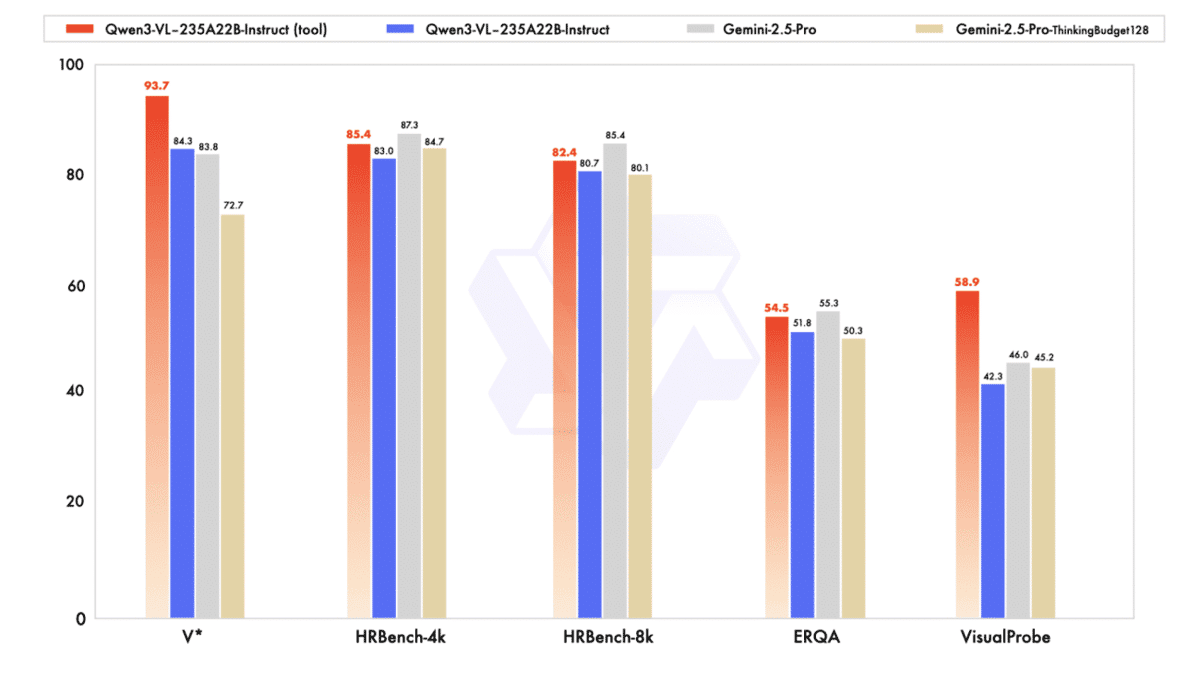
Benchmarks cited by the company show that the Instruct model matches or surpasses Gemini 2.5 Pro in visual perception. Meanwhile, the Thinking model outperforms it on complex math tasks such as MathVision.
Performance upgrades are attributed to three architectural changes. An interleaved MRoPE positional scheme distributes temporal and spatial information more evenly.
DeepStack technology injects visual features into multiple LLM layers, improving detail capture and text-image alignment. A new text-timestamp alignment method enhances video temporal reasoning, enabling more accurate event localisation.
The system’s capabilities extend beyond perception. Qwen3-VL can act as a visual agent by navigating GUIs, converting sketches into code or executing fine-grained 2D and 3D object grounding. Its OCR now spans 32 languages, with higher accuracy under challenging conditions and better handling of long, complex documents.
The company said the open release aims to serve as a foundation for community exploration, framing Qwen3-VL as both a research tool and a step towards embodied AI systems. The project positions the series as a competitive alternative to closed-source leaders while expanding open access to multimodal reasoning technology.
Recently, Alibaba unveiled Qwen3-Next, a new LLM architecture combining hybrid attention and sparse MoE for ultra-long context efficiency. With faster throughput and reasoning strengths, Qwen3-Next powers two post-trained models, edging towards Qwen3.5 advancements.
- In a Stunning Fall, Jensen Huang Resigns as NVIDIA Chief After 33 Years
- Space Tech Startup Astrome Bags ₹64 Cr RDI Fund for AI Satellite Network
- Siemens Wants to Continue NVIDIA Partnership Even If Jensen Huang is Ousted
- LTM Integrates AI Tool to Fix Quantum Computing Errors on IBM
- Chariot Launches Multilingual TTS Model with Support for 11 Indian Languages
- Lenovo Unveils New AI, HPC Servers With AMD’s 6th Gen EPYC Processors