
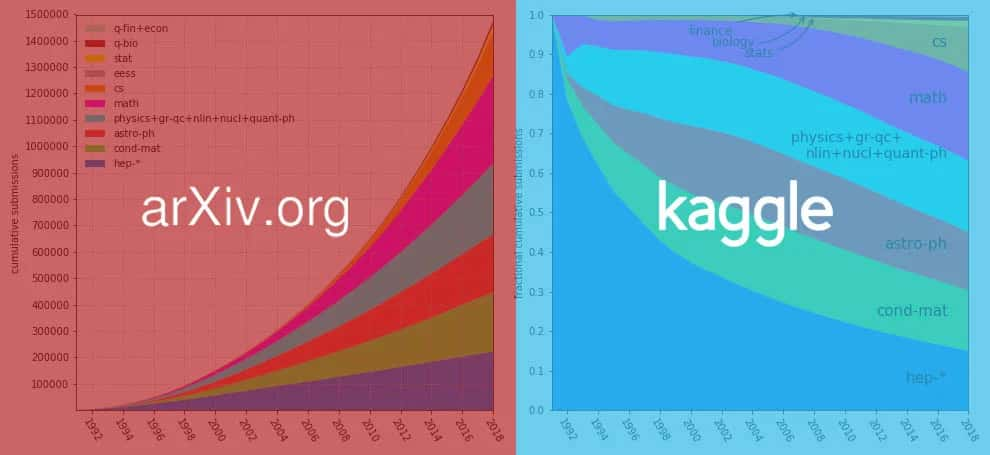
arXiv, the largest repository of research papers recently announced that they are presenting a free and open pipeline of its dataset which is more than 1.7 million articles on Kaggle. It aims to boost developments in areas such as machine learning. It will include relevant features such as article titles, authors, categories, abstracts, full-text PDFs and more.
arXiv has served the public and research communities for nearly 30 years in subjects ranging from physics, computer science, math, statistics, quantitative biology, economics and everything in between.
“Having the entire arXiv corpus on Kaggle grows the potential of arXiv articles immensely. By offering the dataset on Kaggle we go beyond what humans can learn by reading all these articles and we make the data and information behind arXiv available to the public in a machine-readable format,” said Eleonora Presani, Executive Director, arXiv.
Kaggle has been a favourite destination for data scientists and machine learning engineers for quite some time now. Researchers can utilise Kaggle’s extensive data exploration tools and easily share their relevant scripts and output with others. With arXiv’s repository of articles, Kaggle users can push the limits of innovation.
The large datasets will offer researchers with new connections, innovative tools and perspectives to enable better discovery and innovation, believes Steinn Sigurdsson, Scientific Director, arXiv.
Especially at the time of the current pandemic, when the world is aiming for developments to cure COVID, free resources can help the researchers come up with solutions and innovations. For instance, Google’s COVID-19 Research Explorer is a tool that helps researchers pore through the CORD-19 dataset – a repository of 190,000+ science articles on COVID-19 on arXiv.
arXiv hopes that the release of the machine-readable dataset will inspire the creation of similar tools in the future.
The dataset available on Kaggle will be updated weekly and is available here.
- Europe's Biggest Tech Startup Cuts AI Coding Costs by 90% Using Chinese Model
- E2E Networks Launches Blaze To Offer Pay-Per-Token AI Inference Services
- Apple Posts Record Revenue in India for Q4 FY26
- Dispatch Network Raises ₹5 Cr Pre-Seed Led by Antler India to Build AI-Powered Delivery Network
- Coforge Launches BridgeCX With Pega, Mastercard for Customer Personalisation
- HCLTech Launches AI Agents to Support Mainframe Operations