
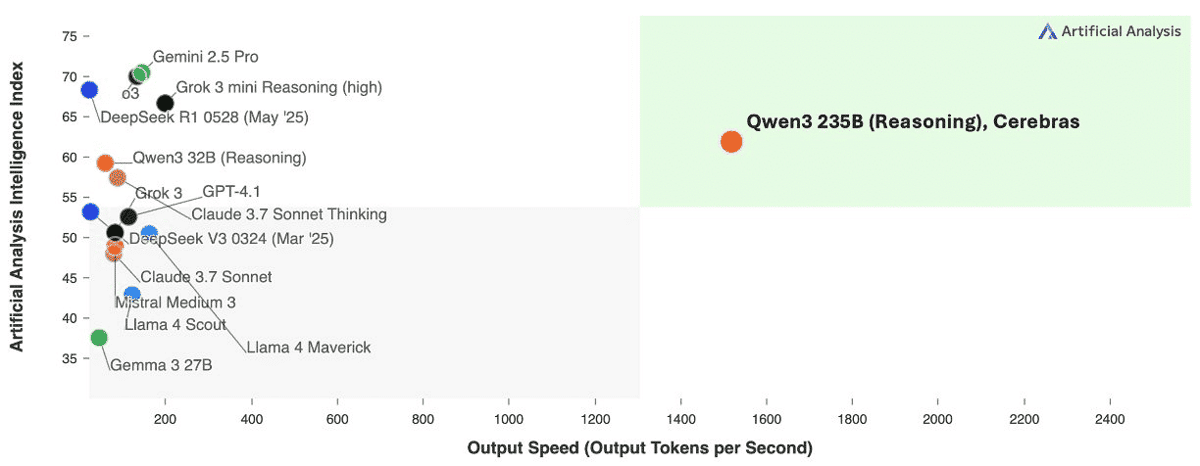
Cerebras, the AI infrastructure firm, announced on July 8 that it will deploy Alibaba’s flagship Qwen3 reasoning model, featuring 235 billion parameters, on Cerebras hardware. The model is claimed to run at 1,500 tokens per second.
“That means reasoning time goes from 60 seconds on GPUs to just 0.6 seconds,” said the company in the announcement. Cerebras added that it is enabling the model with 131k context for enterprise customers, which allows production-grade code generation.
The model will be available for all to try later this week at Cerebras.
The company develops wafer-scale AI chips optimised for inference — a process which involves deriving insights from pre-trained AI models. Its cloud services host a range of AI models powered by its hardware, allowing users and developers to generate over 1,000 tokens per second.
In AI models, ‘reasoning’ involves using extra computation to analyse a user query step-by-step, aiming for an accurate and relevant answer. This process can be time-consuming, sometimes taking several minutes to complete.
Custom hardware systems often surpass the inference performance of traditional NVIDIA GPUs, which are frequently used for training and deploying AI models.
Along with Cerebras, companies like Groq and SambaNova have built hardware that offers superior performance for inference.
In May, Cerebras announced that its hardware has outperformed NVIDIA’s DGX B200, which consists of 8 Blackwell GPUs, in terms of output speed while deploying Meta’s Llama 4 Maverick model.
Cerebras achieved an output token speed of over 2,500 tokens per second, whereas NVIDIA demonstrated an output token speed of only 1,000 tokens per second.
However, NVIDIA outperformed systems from Groq, AMD, Google, and other vendors. “Only Cerebras stands – and we smoked Blackwell,” said Cerebras in a post on X. “We’ve tested dozens of vendors, and Cerebras is the only inference solution that outperforms Blackwell for Meta’s flagship model,” said the company.
- AI Productivity to Add $28 Billion to $84 Billion to India's GDP: Cognizant Study
- OpenAI's Codex Helps in Aerodynamic Engineering for Mazda
- Bengaluru Accounts for 34% of India's FDE Talent: Report
- 84% See AI Productivity Gains, but Only 10% Allow Agent Autonomy: TCS Study
- Snowflake Introduces Business Ontology, Cortex AI Gateway to Bring AI Agents Into Enterprise Workflows
- Three Members Behind Claude Code Leave Anthropic Within 10 Days