
A new benchmark tool, FACTS Grounding, was recently announced as a collaboration between Google DeepMind and Google Research. It evaluates the factual accuracy of LLMs.
Introducing FACTS Grounding. A new benchmark we’re launching with @GoogleDeepMind to evaluate LLM’s factual accuracy on over 1700 tasks. 🧠📐 pic.twitter.com/MvyRbbuMwK
— Kaggle (@kaggle) December 17, 2024
The FACTS Grounding benchmark and an associated leaderboard aim to measure how well AI models generate responses grounded in the provided source material. This initiative addresses challenges such as misinformation and hallucination in AI-generated content.
“To track progress, we’re also launching the FACTS leaderboard on Kaggle,” the developers announced in their blog.
This aims to increase trust in LLMs and limit their applications in the real world since LLMs are prone to hallucinate false information, particularly when given complex inputs.
Results are 95% More Confident
The FACTS Grounding evaluation process revealed detailed insights into the factual accuracy of leading language models.
The tested models included Gemini 1.5 Pro and Flash (Gemini Team), Gemini 2.0 Flash Experimental, GPT-4o (OpenAI), OpenAI o1-preview and o1-mini, and Claude 3.5 Haiku and Sonnet (Anthropic).
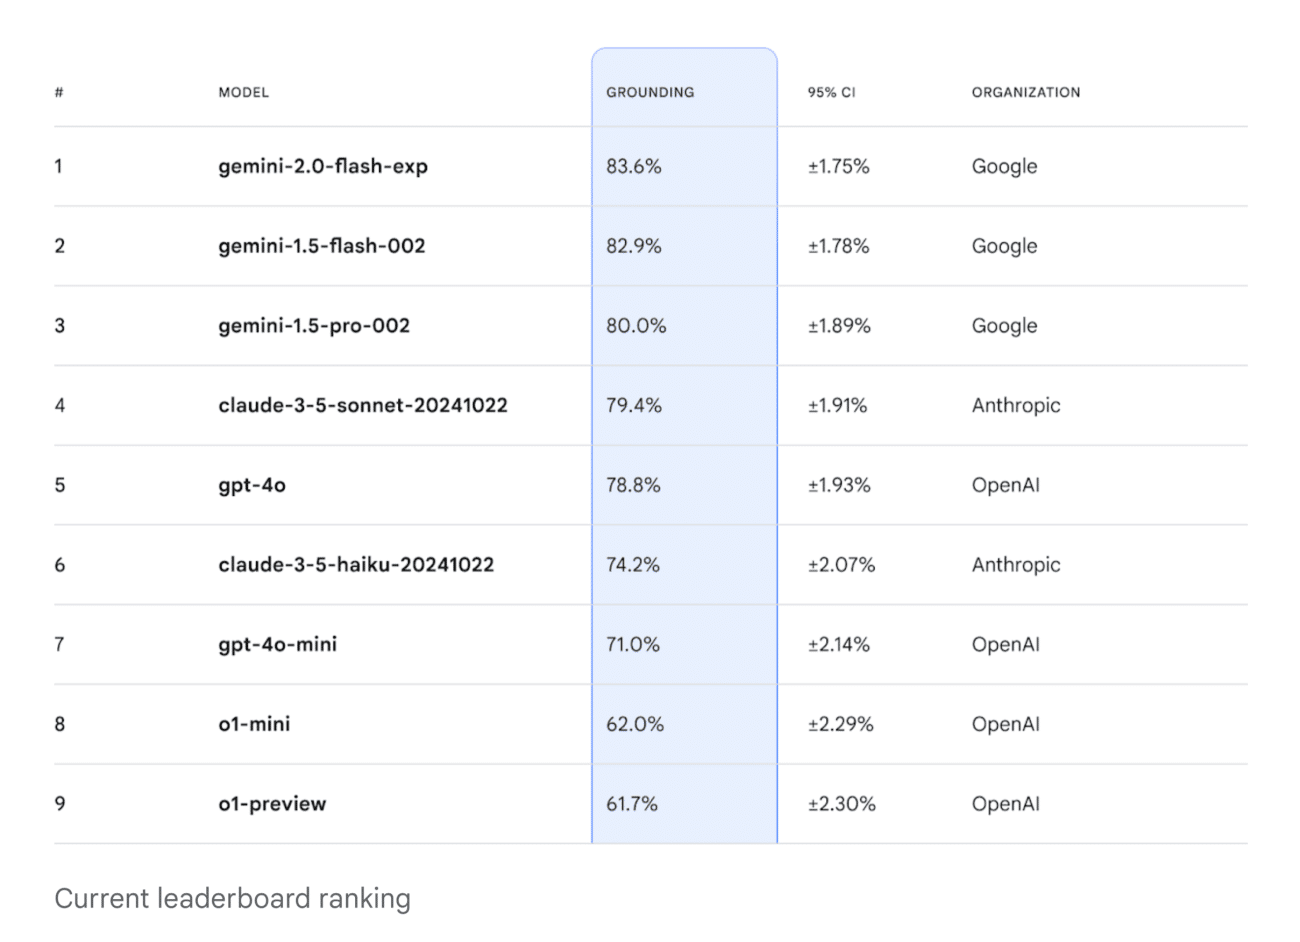
In the aggregation process, models were found to rate their own outputs higher than those of competing models by an average of over 3.23%, a trend observed in prior studies. To counteract this bias, multiple judge models were employed to increase the computational cost while ensuring fairness in evaluation.
Disqualifying ineligible responses reduced final factuality scores by 1%–5%. This adjustment also slightly shifted model rankings, with Gemini 1.5 Flash dropping from first to second place. Regardless, it presented with a 95% confidence interval.
Google has instructed Gemini AI testers to "wing it" on prompts they don't understand, suggesting they rate what they comprehend and note any confusion.
— Daniel Gabai (@DanielGabai_) December 20, 2024
The company assures this approach won't compromise Gemini's accuracy, pointing to their newly introduced FACTS Grounding… pic.twitter.com/VcmSIZqR8t
The ranking of models was determined through a ‘Fused Rank’ metric, which aggregates individual rankings from different splits and judges models using the Condorcet algorithm.
How was the Testing Done?
The benchmark comprised 1,719 examples that test models on diverse tasks, including summarisation, question answering, and rewriting.
The dataset and methodology prioritise real-world applicability, with tasks ranging across finance, law, and technology. To assess model performance, automated evaluations involve multiple judge models.
Responses are disqualified if they fail to adequately address user queries or lack grounding in the provided material.
Is Google Leading the Charge?
Google also launched multiple other major developments this year, which made Google DeepMind a leader in the AGI race, outpacing OpenAI and its rivals.
The company unveiled a series of groundbreaking innovations, including its latest quantum chip, Willow, and the advanced Gemini Flash 2, Pro, and agents. It also introduced Project Astra and Project Mariner, showcasing its commitment to cutting-edge research.
Further advancements include the text-to-video model Veo 2 and the text-to-image model Imagen 3, which demonstrate its strides in generative AI. Additionally, the Gemini 2.0 Flash Thinking framework marks a significant leap forward in model reasoning and robotics.
This latest FACTS Grounding benchmark is seen as a significant step in promoting trust and accuracy in AI-generated content.

Your reaction
Discussion
What's your take on this story?
No comments yet — be the first to share your view.