
Google has launched T5Gemma, a new collection of encoder-decoder large language models (LLMs) that promise improved quality and inference efficiency compared to their decoder-only counterparts. It is based on the Gemma 2 framework.
Unlike the current trend that favours decoder-only LLMs, T5Gemma revisits the classic encoder-decoder architecture used in models like T5. The company introduced an adaptation technique that converts pretrained decoder-only models into encoder-decoder ones.
“We study a novel problem: adapting pretrained decoder-only LLMs to encoder-decoder, with the goal of leveraging the strengths of both approaches to achieve a more favourable quality efficiency trade-off,” the research paper mentioned.
The researchers further highlight that this adaptation not only enables inheriting the capability of decoder-only LLMs but also reduces the computational demand compared to pretraining from scratch.
“Can we build top-tier encoder-decoder models based on pretrained decoder-only models? We answer this question by exploring model adaptation,” the company explained in the blog post.
T5Gemma includes both newly trained T5-sized models, ranging from small to XL, and adapted Gemma 2 models with 2B and 9B parameters. It also offers unbalanced combinations such as a 9B encoder with a 2B decoder, aimed at optimising performance for tasks where input understanding is more important than output complexity.
According to benchmark results shared by Google, T5Gemma dominates the quality-inference efficiency Pareto frontier. On SuperGLUE and GSM8K, the models outperform comparable decoder-only models in both accuracy and latency. For example, T5Gemma 9B-9B delivered higher GSM8K accuracy than Gemma 2 9B while maintaining similar latency.
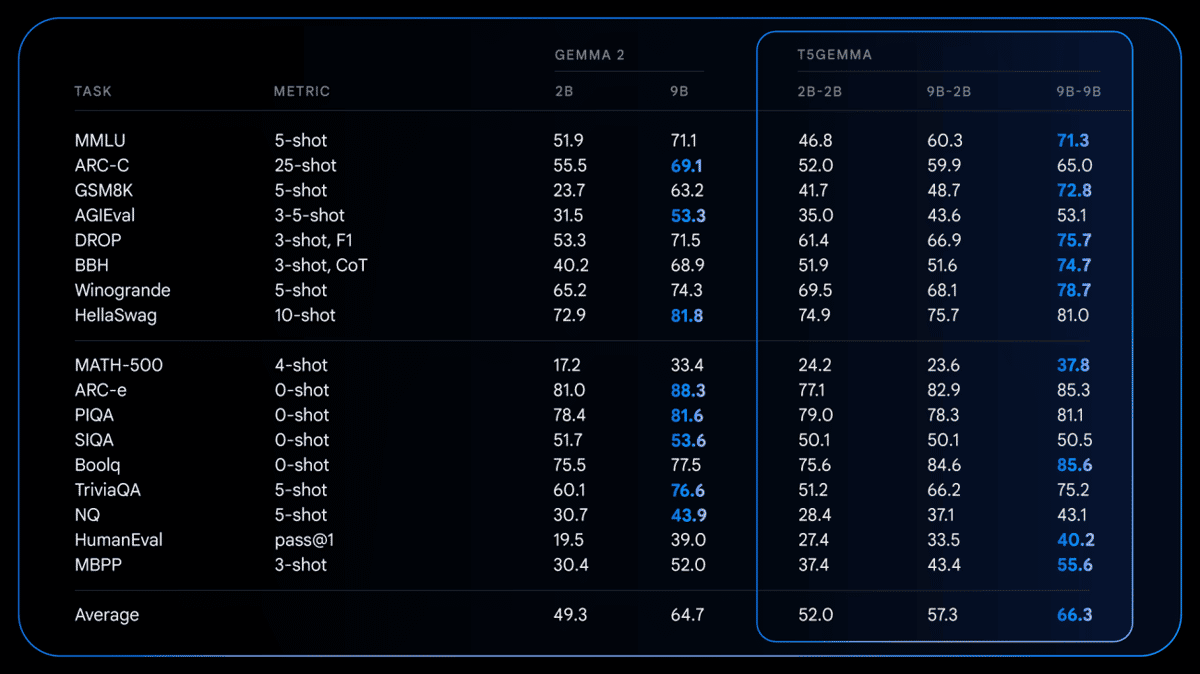
The gains extend beyond pretraining. After instruction tuning, T5Gemma models showed dramatic improvements. The 2B-2B model's MMLU score jumped 12 points, while GSM8K accuracy rose from 58.0% to 70.7%, highlighting the architecture’s responsiveness to fine-tuning.
Google has released a wide range of T5Gemma checkpoints, including pretrained and instruction-tuned variants, with multiple training objectives such as PrefixLM and UL2.
The models are now available on Hugging Face, Kaggle, and Vertex AI for further experimentation and deployment.
- Bihar Partners with IT Cos to Train Government School Teachers In AI
- Meta Wants $95 Billion Through Stock Sales to Fund AI Infrastructure
- Pronto Founder Enters Physical AI Space With Provision Labs
- HCLTech Taps NVIDIA Simulation Tools to Automate Software-Defined Vehicle Testing
- Tata Communications Plans $450 Mn Investment to Build 10,000 Km AI Network
- Telangana Unveils AI-Powered Digital Twin of IT Minister at DevFest 2026