
Google launched the stable version of Gemini 2.5 Flash-Lite on July 22. It is the fastest and most cost-effective model (in terms of API price) in the Gemini AI family. Google also stated that reasoning abilities are built into the model and can be optionally enabled.
According to Artificial Analysis, the model outputs 471 tokens per second (tok./sec.), making it one of the fastest AI models today.
It outperforms Gemini 2.5 Flash Reasoning (309 tok./sec.), Grok 3 Mini Reasoning-High (202 tok./sec.), Meta’s Llama 4 Maverick (168 tok./sec.) and many other models, including OpenAI’s GPT-4.1 Mini and o4-mini models.
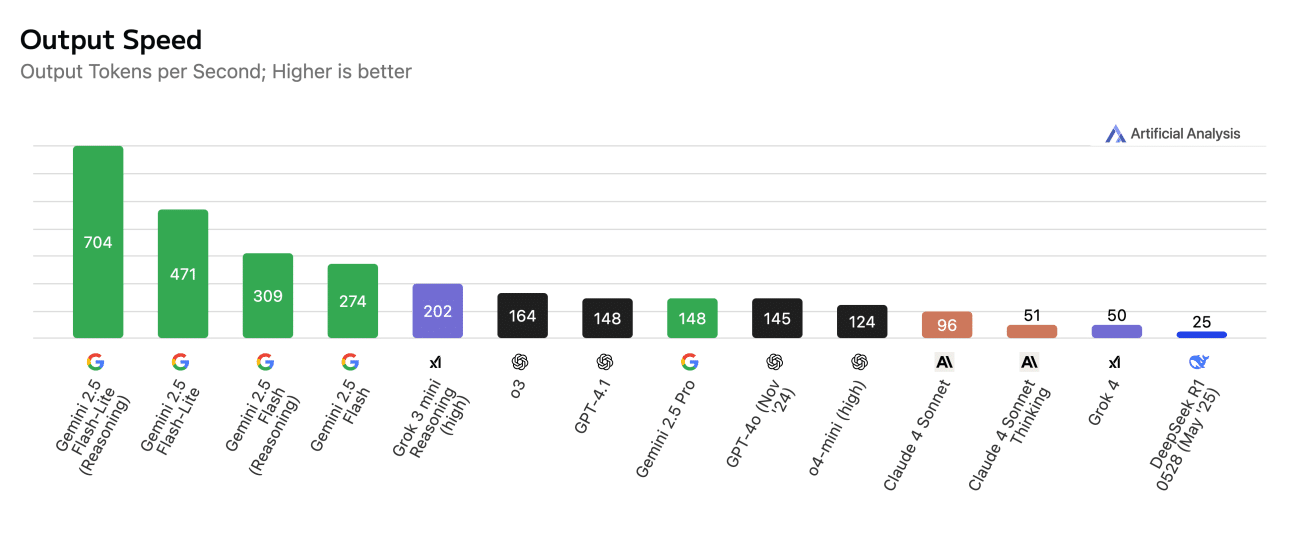
Image Source: Artificial Analysis
In terms of pricing, the Gemini 2.5 Flash-Lite costs $0.10 and $0.40 per million input and output tokens, respectively. This is significantly lesser than the Gemini 2.5 Flash ($0.15 input, $0.50 output), Gemini 2.5 Pro ($2.50 input, $10 output), and even models from OpenAI such as o4-mini (high) ($1.10 input, $4.40 output) and DeepSeek R1 ($0.55 input, $2.19 output).
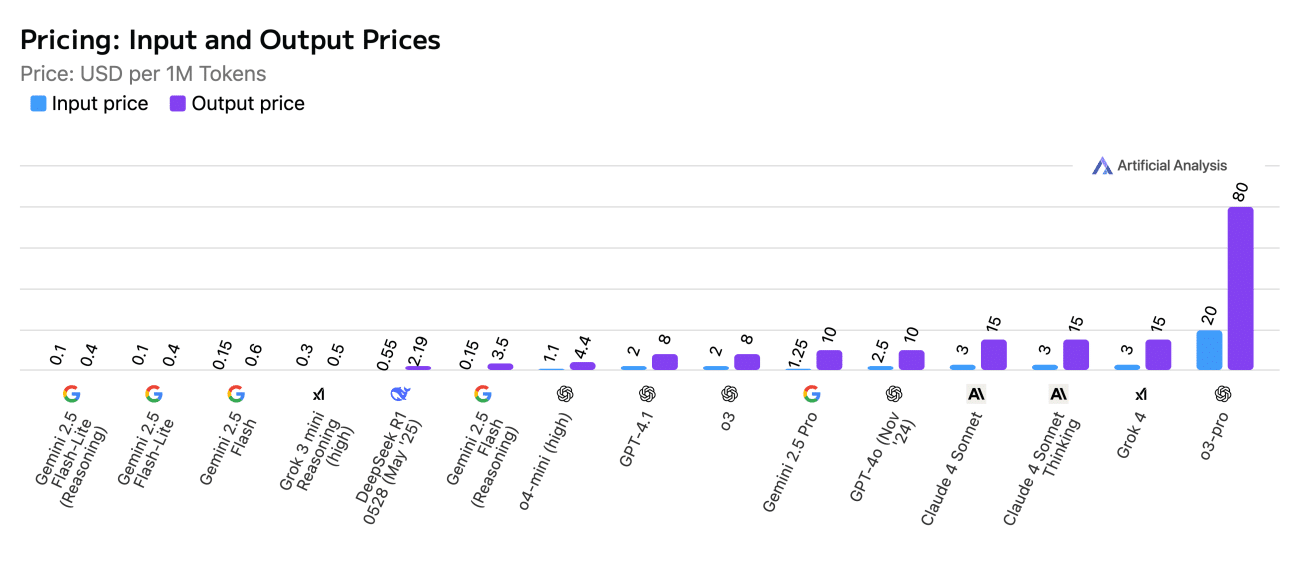
Image Source: Artificial Analysis
In terms of performance, Gemini 2.5 Flash-Lite scores 46 points on the Artificial Analysis Intelligence Index, which aggregates results from seven evaluations across math, logic, reasoning, and coding.
This places it ahead of OpenAI’s GPT-4o, which scores 41. However, higher scores are recorded by other models in the same family: Gemini 2.5 Flash scores 65, and Gemini 2.5 Pro scores 70. The top-performing models on the index are OpenAI’s o3-pro, with 71 points, and xAI’s Grok 4, with 73 points.
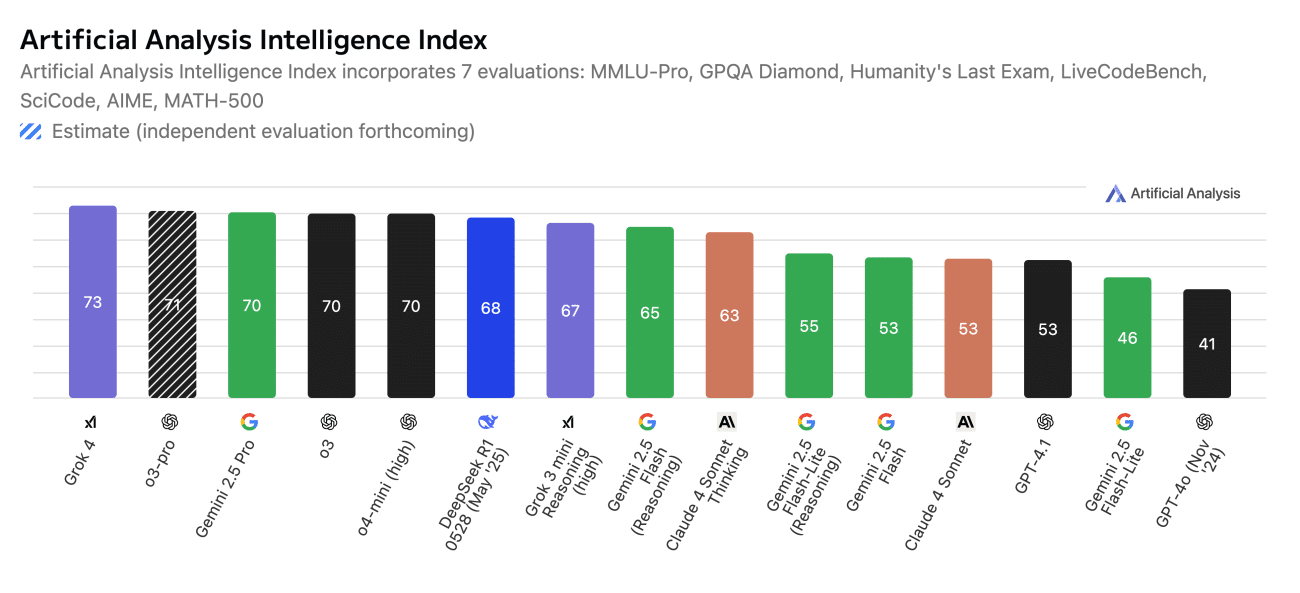
Image Source: Artificial Analysis
“Gemini 2.5 Flash-Lite strikes a balance between performance and cost, without compromising on quality, particularly for latency-sensitive tasks like translation and classification,” said Google.
The stable version of Gemini 2.5 Flash-Lite is now available in Google AI Studio and Vertex AI. The company stated that the model provides a 1 million-token context window, along with thinking budgets, and supports native tools such as Grounding with Google Search, Code Execution, and URL Context.
Google also shared a few customer success stories of building with Gemini 2.5 Flash-Lite. For instance, Satlyt, which is building a satellite data processing platform, achieved a 45% reduction in latency for critical onboard diagnostics and a 30% decrease in power consumption compared to their baseline models.

Your reaction
Discussion
What's your take on this story?
No comments yet — be the first to share your view.