

Key takeaways
- Hugging Face's SmolLM2 outperforms rivals like Qwen2.5-1.5B and Llama3.2-1B in small language models.
- Utilize SmolLM2's extensive training on 11 trillion tokens for enhanced performance in various applications.
- Leverage the model's open-source Apache 2.0 license for accessible development and experimentation.
- Explore newly created datasets FineMath, Stack-Edu, and SmolTalk for improved specialized training.
- Evaluate models using Lighteval to benchmark performance across diverse use cases effectively.
Small language models (SLMs) are gaining popularity due to their minimal carbon footprint and low computing requirements. The latest to join the bandwagon is SmolLM2 by Hugging Face.
Pushing Small Language Models Further
SmolLM2 is available under an Apache 2.0 license, making it an open-source alternative. As per the research paper, it is trained on an extensive dataset of ~11 trillion tokens, combining web text with specialised data like math and code.
The model utilised a multi-stage training process to rebalance from different data sources to maximise performance.
The researchers also expanded on using specialised data, “Additionally, after finding that existing datasets were too small and/or low-quality, we created the new datasets FineMath, Stack-Edu, and SmolTalk (for mathematics, code, and instruction-following respectively).”
They also compared the SLM with other existing state-of-the-art models like Qwen2.5-1.5B and Llama3.2-1B. The evaluation was done using Lighteval, and it outperformed Qwen and Llama.
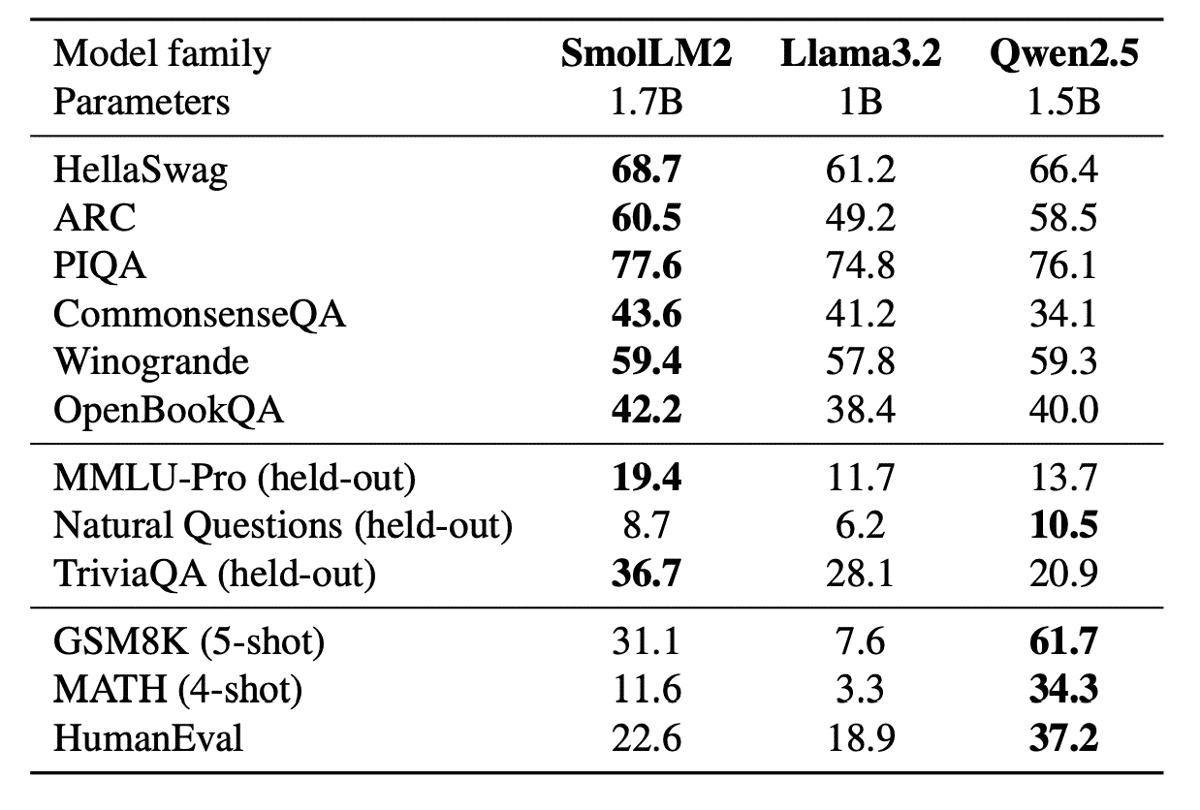
The table above shows that the model was tested with various types of parameters to test all kinds of use cases.
Summing up the results, the paper states that the AI model beats Qwen2.5-1.5B by around six percentage points on MMLUPro, proving its capabilities as a useful generative AI model. Additionally, with the math and coding benchmarks, SmolLM2 exhibits competitive performance.
It is worth noting that it could not perform better than Qwen2.5-1.5B on a couple of tests, including MATH, but it outperforms Llama3.2-1B on the same.
To explain more about the performance, the researchers also shared about a couple of tests not monitored for benchmarks, “SmolLM2 also delivers strong performance on held-out benchmarks not monitored during training, such as MMLU-Pro (Wang et al., 2024c), TriviaQA (Joshi et al., 2017), and Natural Questions (NQ, Kwiatkowski et al., 2019).”
Considering the model is open source, Hugging Face has released the datasets and the code used for training to facilitate future research and development on SLMs.
It should be exciting to see what the next small language model can do without organisations worrying about resource constraints.

