Key takeaways
- Introduce Humanity's Last Exam (HLE), a new benchmark for testing AI systems on expert-level knowledge.
- Highlight that top AI models scored below 10%, indicating challenges with complex and interdisciplinary problems.
- Reveal that the DeepSeek R1 model outperformed more powerful counterparts, questioning assumptions about model strength.
- Address benchmark saturation, emphasizing the need for smarter AI benchmarks to tackle novel challenges.
- Involve diverse academic contributors to enhance the benchmark's relevance and rigor in evaluating AI reasoning.
The AI field welcomes a new benchmark: Humanity’s Last Exam (HLE), introduced by the Center for AI Safety (CAIS) and Scale AI for testing AI systems on expert-level knowledge. The dataset includes 3,000 questions crowdsourced from 1,000 contributors across 500 institutions in 50 countries, including professors and PhD holders. It covers mathematics, humanities, and natural sciences using the multi-format approach that includes text, diagrams, and images.
The benchmark tested models like GPT-4o, Claude 3.5, and DeepSeek, with none scoring above 10%, revealing their struggle with complex and interdisciplinary problems. The benchmark showed that DeepSeek R1 – a cheaper and less powerful open-source model – outperformed the full o1 model known for its reasoning abilities.
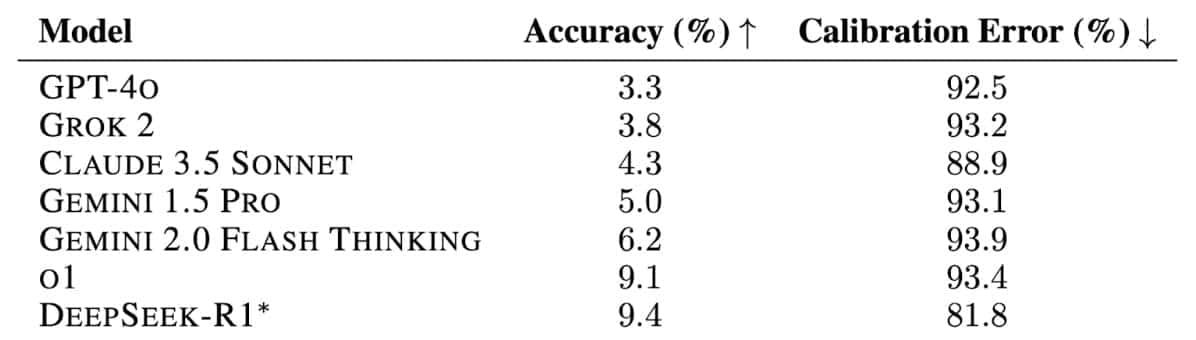
HLE was created to address “benchmark saturation,” where AI models excel on standard tests but fail on novel challenges.
“I wrote 5 questions in the new benchmark that even the top AI models score less than 10% on: Humanity's Last Exam,” said Jeremy Nguyen on X.
The project involved contributors from diverse academic and research backgrounds. Summer Yue, Scale AI’s Director of Research, said the benchmark was designed to push AI models to their reasoning limits.
Benchmarks in the AGI era
“Starting to see new well-built hard benchmarks in AI since almost everything else has already been exceeded. We now have this (with humanities questions), ARC-AGI 2, and Frontier Math. We also need some benchmarks for new knowledge creation rather than testing known problems,” wrote Wharton’s Ethan Mollick on X.
Last week, there were concerns about OpenAI's involvement with FrontierMath. For context, In December, OpenAI announced its o3 models, reporting 25% accuracy on the EpochAI Frontier Math benchmark, a significant improvement from the previous 2% achieved by other models.
Epoch AI recently clarified that OpenAI commissioned them to create 300 math questions for the FrontierMath benchmark. OpenAI owns these questions and has access to their statements and solutions, except for a 50-question private holdout set.
The statement also noted that Epoch AI can evaluate and publish results on any model using the FrontierMath problem set but cannot share the questions or answers without OpenAI’s written permission.
“We can evaluate other models and have done so already. We will publish more results in the next few weeks, perhaps including DeepSeek’s,” clarified Epoch’s Tamay Besiroglu to AIM, addressing FrontierMath’s approach to evaluating models from other companies.
Regarding the holdout set, Epoch AI explained they are finalising a 50-question set for which OpenAI will only receive the problem statements, not the solutions.
AI evaluations largely remain underfunded, and tougher benchmarks are essential as we progress towards AGI. "Going forward, we will ensure all contributors have access to information about industry funding and data access agreements before participating and proactively publicly disclose benchmark sponsorship and data access agreements," read Epoch's statement.
Spotted an error? Tell our editors. Read our editorial standards and corrections.