
In May, IBM open sourced its Granite 13B LLM, ideal for enterprise use cases.
Now, Armand Ruiz, the VP of product - AI platform at IBM, has revealed the entirety of its comprehensive 6.48 TB dataset used to train Granite 13B.
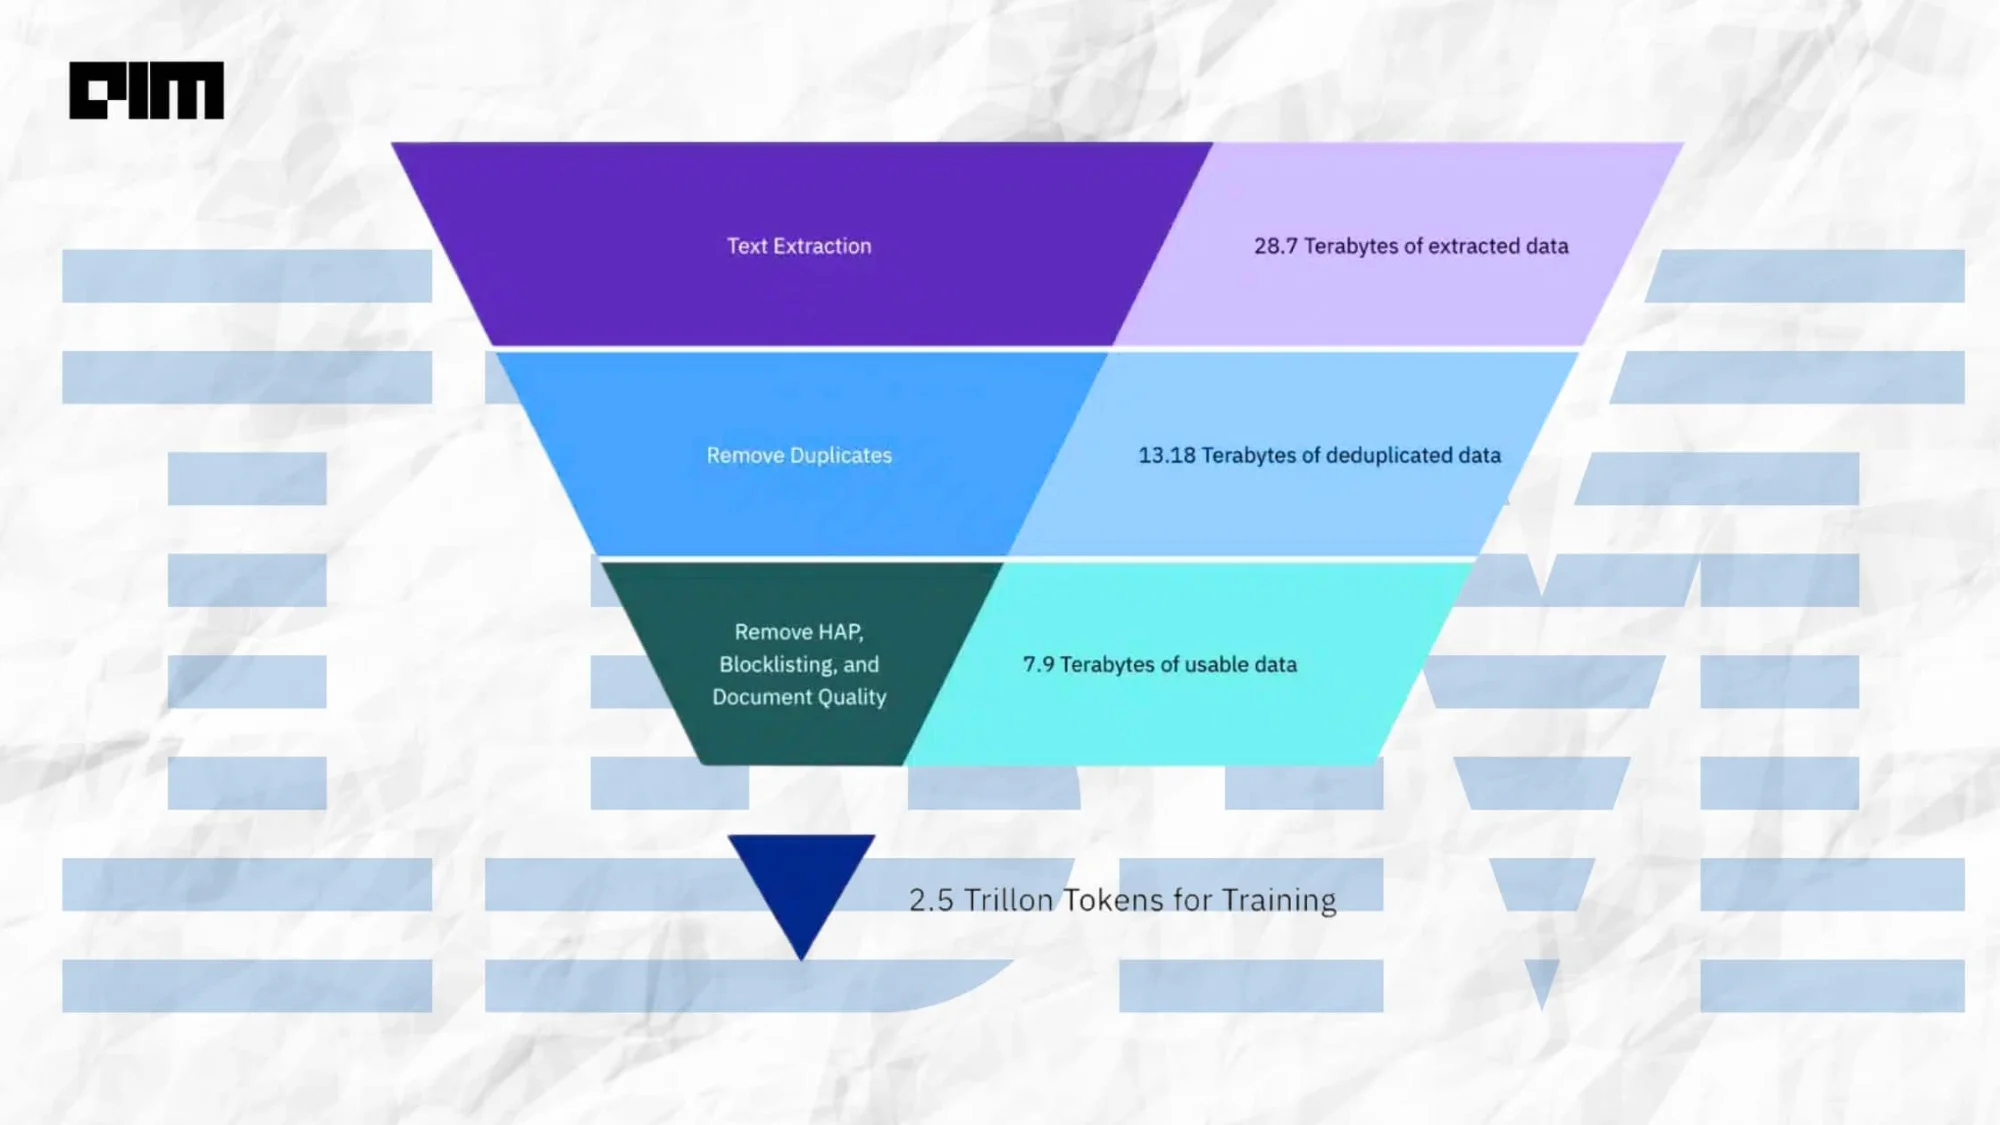
This dataset, after undergoing rigorous pre-processing, was reduced to 2.07 TB, reflecting a 68% reduction. Ruiz emphasised that this step was essential to ensure a high-quality, unbiased, ethical, and legal dataset tailored for enterprise use cases.
The dataset was meticulously curated from a variety of sources, including:
- arXiv: Over 2.4 million scientific paper pre-prints.
- Common Crawl: Open repository of web crawl data.
- DeepMind Mathematics: Mathematical Q&A pairs.
- Free Law: Public-domain legal opinions from US courts.
- GitHub Clean: Code data from CodeParrot.
- Hacker News: Computer science and entrepreneurship news from 2007-2018.
- OpenWeb Text: Open-source version of OpenAI’s Web Text corpus.
- Project Gutenberg (PG-19): Free e-books with a focus on older works.
- Pubmed Central: Biomedical and life sciences papers.
- SEC Filings: 10-K/Q filings from the US SEC (1934-2022).
- Stack Exchange: User-contributed content on the Stack Exchange network.
- USPTO: US patents granted from 1975 to May 2023.
- Webhose: Unstructured web content converted into machine-readable data.
- Wikimedia: Eight English Wikimedia projects.
The pre-processing pipeline included several key steps including Text extraction, deduplication, language identification, sentence splitting, hate, abuse, and profanity annotation, document quality annotation, URL block-listing annotation, Filtering, Tokenization.
These steps, involving annotation and filtering based on defined thresholds, ensured that the final dataset was of the highest quality for model training.
IBM has released four variations of the Granite code model, ranging in size from 3 to 34 billion parameters. The models have been tested on a range of benchmarks and have outperformed other comparable models like Code Llama and Llama 3 in many tasks.

Your reaction
Discussion
What's your take on this story?
No comments yet — be the first to share your view.