Key takeaways
- Meta has open-sourced 'Casual Conversations v2', an inclusive dataset for assessing AI fairness.
- The dataset includes 26,467 videos from 5,567 participants with diverse attributes.
- Utilize ten annotated categories to measure algorithmic fairness and robustness in AI systems.
- Access the dataset in mp4 format, averaging one minute per video for practical applications.
- Focus on consent-driven data collection amid growing privacy and ethics concerns in AI.
Amid rising concerns about privacy and ethics behind datasets used in AI models, Meta has open-sourced a consent-driven dataset of recorded monologues called 'Casual Conversations v2', calling it an inclusive dataset. This second version of the dataset has been created to assist researchers in evaluating the accuracy of their computer vision, speech, and audio models across a wide range of use cases.
This new dataset features a more comprehensive list of ten annotated categories, self-provided by the participants for better measurement of algorithmic fairness and robustness in AI systems. These categories include diverse ages, genders, language/dialects, geographies, disabilities, physical adornments, physical attributes, voice timbres, skin tones, activities, and recording setups.
Click here to access the dataset.
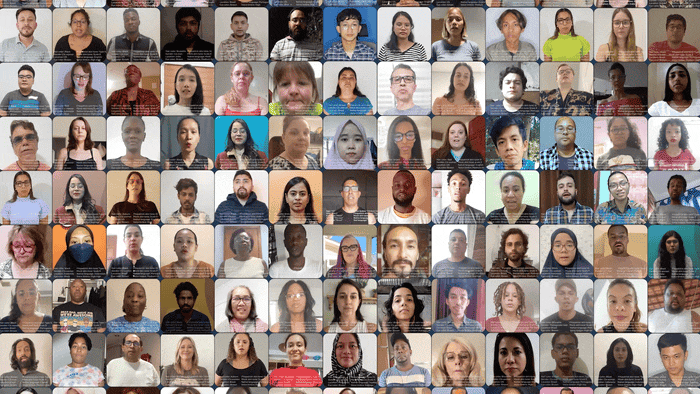
The dataset is composed of 26,467 videos of around 5,567 participants and intended for assessing the performance of pre-trained models in computer vision and audio applications, according to the company’s data license agreement. The data is available in mp4 format with an average video length of one minute.
Interestingly, the participants were labelled on their apparent skin tone using Fitzpatrick Scale and Monk Scale along with annotations of Voice timbre, Activity, and Recording setups. The words are derived from a sample paragraph from Fyodor Dostoevsky’s 'The Idiot' or non-scripted answering one of five predetermined questions.
Meta said that the creation of Casual Conversations v2 was part of a continuous effort to promote inclusive AI and products across different industries. While addressing issues of AI fairness and robustness requires collaboration and multiple solutions, the team is committed to partnering with field experts to explore these areas further and inspire more research.
Spotted an error? Tell our editors. Read our editorial standards and corrections.