
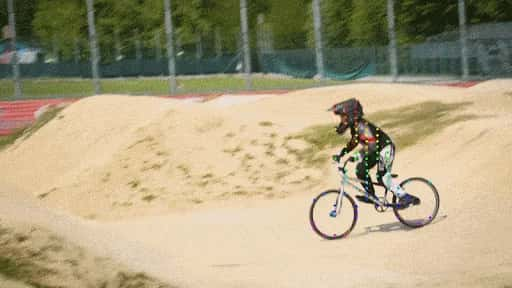
Meta, on October 16, announced the launch of CoTracker3, a point tracker model to track videos, an upgrade to its CoTracker series of models featuring advanced AI technology. CoTracker3 is designed to handle situations where tracked points move out of view or temporarily occluded to overcome challenges in tracking objects across complex scenarios.
Click here to check out the GitHub repository.
By introducing a semi-supervised learning method called ‘pseudo labelling’ on real videos, it allows the model to self-label parts of the data while Meta focuses on increasing the quality and quantity of training information without requiring fully annotated datasets.

According to the researchers, CoTracker3 can surpass trackers trained on ×1,000 more videos through its simple semi-supervised training protocol. By tracking points jointly, CoTracker3 handles occlusions better than any other model, mainly when operated offline.
Meta said this model can be used as a building block for tasks requiring motion estimation, such as 3D tracking, controlled video generation, or dynamic 3D reconstruction.
The researchers also said that CoTracker3 outperformed the state-of-the-art on TAP-Vid and other benchmarks as its architecture combines several ideas from recent trackers and eliminates unnecessary components.
Available on both online and offline platforms, the model can be explored live by developers and researchers on Hugging Face. This model's utility spans multiple domains, such as augmented reality, robotics, and sports analytics, where accurately tracking object motion is essential.
Meta has also made the model and associated resources available under an A-NC licence to facilitate further research.
Earlier this year, Meta also introduced Video Joint Embedding Predictive Architecture (V-JEPA) V-JEPA that predicts the missing parts of videos without needing to recreate every detail. It learns from unlabeled videos, so it doesn’t require data that humans have categorised to start learning. This improves machines’ understanding of the world by analysing video interactions between objects.
- Kalshi to Develop Trading Platform for Compute Futures: Report
- Microsoft Outage: Fix Fails to Restore Outlook, Teams, Copilot Across 74 Countries
- In a Stunning Fall, Jensen Huang Resigns as NVIDIA Chief After 33 Years
- Space Tech Startup Astrome Bags ₹64 Cr RDI Fund for AI Satellite Network
- Siemens Wants to Continue NVIDIA Partnership Even If Jensen Huang is Ousted
- LTM Integrates AI Tool to Fix Quantum Computing Errors on IBM