Key takeaways
- Meta has launched DinoV2, a self-supervised vision transformer model that outperforms previous models without requiring fine-tuning.
- The model is open source and pre-trained on 142 million unlabeled images, showcasing its ability to learn without supervision.
- DinoV2 offers high-performance features that can be utilised for various computer vision tasks, enhancing flexibility for developers.
- By eliminating the need for labelled data, DinoV2 significantly reduces time and resource consumption for developers tackling complex tasks.
After two years of introducing DINO, a self-supervised vision transformer model, Meta AI announced the launch of DinoV2. The model delivers strong performance and does not require fine-tuning unlike other similar models such as CLIP.
Check out the GitHub repository here: DINOv2
Meta achieved this by pretraining on large quantities of raw text using pretext objectives, such as language modelling or word vectors that require no supervision. The model is open source and is pre-trained on 142 million images in self-supervised fashion without any labels.
“DINOv2 provides high-performance features that can be directly used as inputs for simple linear classifiers. This flexibility means DINOv2 can be used to create multipurpose backbones for many different computer vision tasks.,” it said in a blog post.
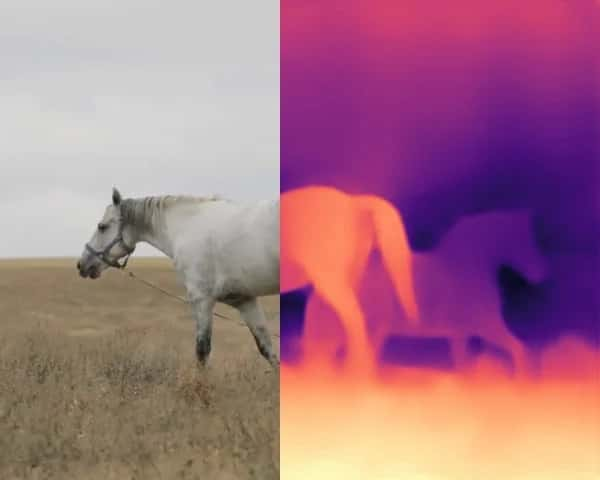
DinoV2 will save developers massive amounts of time and resources because it helps in tackling tasks such as depth estimation, image classification, semantic segmentation, and image retrieval without the need for costly labelled data.
According to Meta, the model utilises self-supervised learning and yields outcomes that are on par with or exceed the conventional methodology utilised in the respective field.
Spotted an error? Tell our editors. Read our editorial standards and corrections.