
On Tuesday, NVIDIA announced its new Llama Nemotron Nano VL, a new multimodal vision-language model (VLM) that now leads the OCRBench v2 benchmark, highlighting its accuracy in document analysis across enterprise use cases.
Designed for intelligent document processing, the model reads and extracts data from complex layouts such as invoices, tables, graphs, and dashboards. It combines visual and textual reasoning capabilities, enabling it to parse diverse file types using just a single GPU.
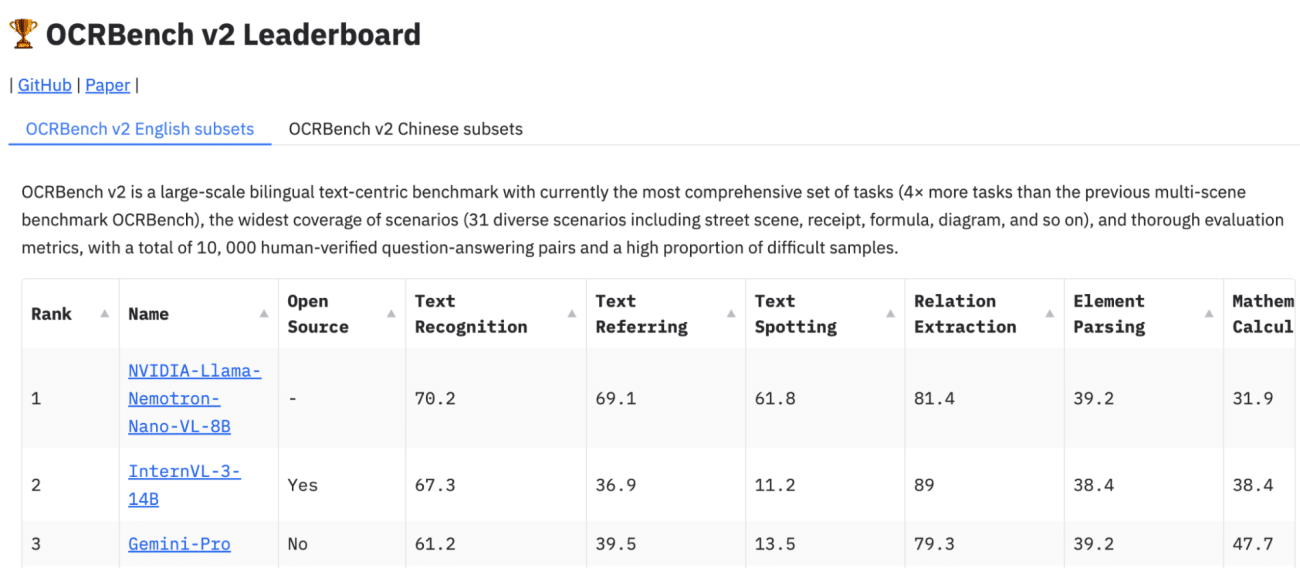
OCRBench v2, which tests AI models on real-world financial, legal, and healthcare documents, confirmed Nemotron Nano VL’s superior performance in text recognition, chart parsing, and element spotting. The benchmark includes 10,000 human-verified Q&A pairs and 31 scenario types. The NVIDIA model can be seen topping the leaderboard chart.
Built on NVIDIA’s C-RADIO v2 vision encoder and trained using Megatron and Energon infrastructure, the model benefits from NeMo Retriever Parse data and multimodal datasets developed by NVIDIA research teams. It is available as an API via NVIDIA NIM and for download on Hugging Face.
With support for use cases like contract review, compliance analysis, and scientific report parsing, Llama Nemotron Nano VL is aimed at businesses seeking scalable, cost-efficient AI for document workflows. “This production-ready model is designed for scalable AI agents that read and extract insights from multimodal documents with unmatched speed, bringing vision language models (VLMs) to the forefront of enterprise data processing,” the company stated in the blog post.
The launch expands NVIDIA’s Nemotron family and underscores its push into vision-language models tailored for enterprise data intelligence.
Recently, Mistral AI unveiled its new enterprise-grade Document AI platform, designed to handle complex OCR tasks with 99%+ accuracy across 11 languages. Capable of parsing everything from handwritten notes to low-resolution scans, the system converts documents into structured JSON, offering speeds of up to 2,000 pages per minute on a single GPU.
The platform is equipped to handle intricate layouts like tables, forms, and contracts, and supports both on-premise and private cloud deployments for data-sensitive sectors. It remains to be seen how NVIDIA’s new VLM compares to it.

Your reaction
Discussion
What's your take on this story?
No comments yet — be the first to share your view.