Key takeaways
- Deep learning's impact is significantly influenced by the availability of high-quality datasets.
- Practising with diverse datasets enhances skills in various areas of deep learning, such as image and speech processing.
- ImageNet serves as a foundational dataset for computer vision, organised according to the WordNet hierarchy.
- The MNIST dataset is widely recognised for its role in digit classification and is essential for beginners.
- Access to open datasets fosters innovation and experimentation within the deep learning community.
Deep learning being the game changer at the present day scenario, the datasets play a dominant role in shaping the future of the technology. Learning starts with getting the right data and the best way to mastering in this field is to get your hands dirty by practicing with the high-quality datasets.
Here we list 15 open high-quality datasets for practicing in deep learning space that includes image processing, speech processing, etc.
2| MNIST
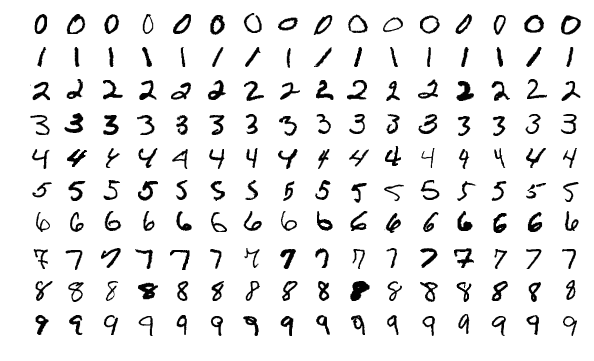
This is one of the important databases for deep learning. Microsoft and Google lab researchers have reportedly contributed to this dataset of handwritten digits. It is basically constructed from NIST that contains binary images of handwritten digits.
Category: Image Processing
Dataset Info: The dataset contains 60,000 examples of the training set and 10,000 examples of the test set. There are four files in this dataset. Here is the link to a paper that implemented this dataset.
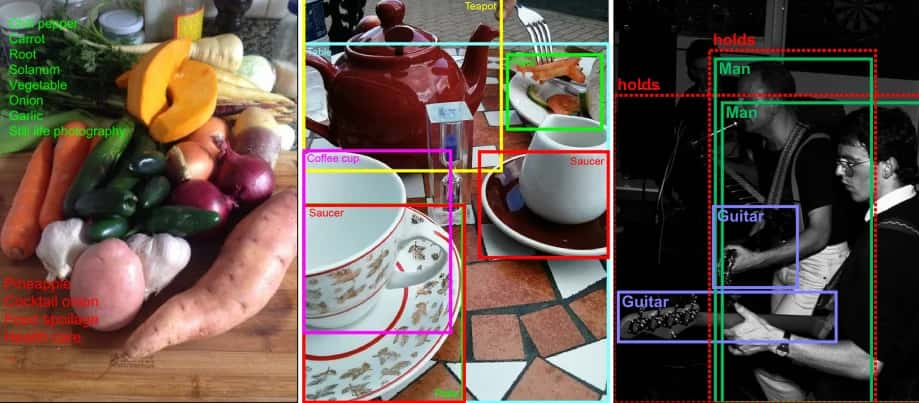
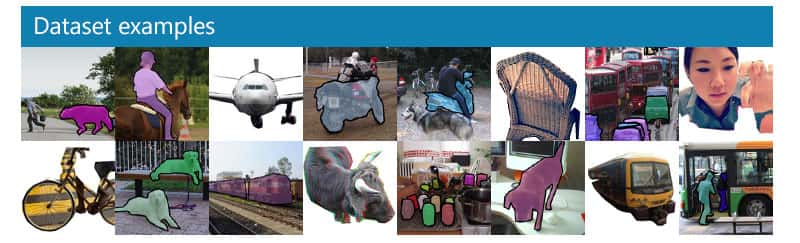 A large-scale object detection, segmentation and captioning dataset that contains features such as recognition in context, super-pixel stuff segmentation, object segmentation, etc.
Category: Image Processing
Dataset Info: This dataset contains 1.5 million object instances with 80 object categories, 91 stuff categories and has been annotated with 5 captions per images.
11| CIFAR-10
This dataset is a labeled subset of 80 million tiny images dataset that was collected by Alex Krizhevsky, Vinod Nair and Geoffrey Hinton.
Category: Image Classification
Dataset Info: This dataset consists of 60,000 32X32 color images in 10 classes with 6000 images per class. The training images and test data consist of 50,000 and 10,000 images respectively.
1| ImageNet
This dataset is inspired by the growing sentiment in the image and vision research field and can be said as the de facto dataset for the classification algorithms in computer vision. This is a dataset of images that are organized according to the WordNet hierarchy. Category: Image Processing Dataset Info: The total number of images includes 14,197,122. The concept in WordNet is described by “synonym set” or “synset” and there are more than 100,000 synsets present in WordNet for which ImageNet provides an average of 1000 images to each synset. Here is a link to a paper that implemented this dataset.2| MNIST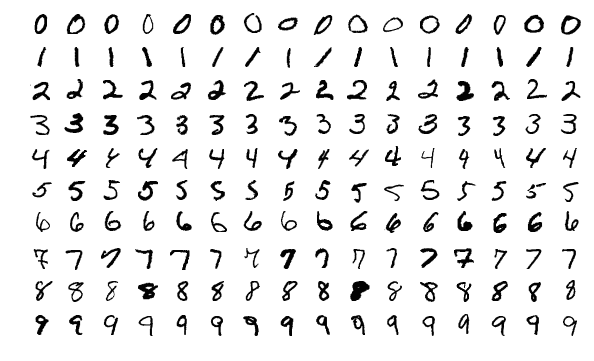
This is one of the important databases for deep learning. Microsoft and Google lab researchers have reportedly contributed to this dataset of handwritten digits. It is basically constructed from NIST that contains binary images of handwritten digits.
Category: Image Processing
Dataset Info: The dataset contains 60,000 examples of the training set and 10,000 examples of the test set. There are four files in this dataset. Here is the link to a paper that implemented this dataset.
3| LSUN
LSUN or Large-Scale Scene Understanding is a dataset that is used to detect and speed up the progress for scene understanding that includes scene classification, saliency prediction, room layout estimation, etc. Category: Image Processing Dataset Info: This dataset by Princeton University consists of around one million labeled images for each scene and object categories where the test set contains 10,000 images.4| MS COCO- Common Objects In Context
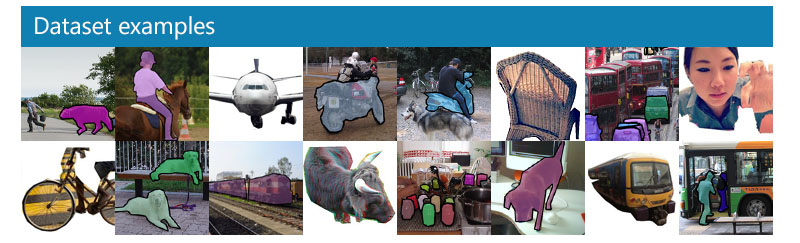 A large-scale object detection, segmentation and captioning dataset that contains features such as recognition in context, super-pixel stuff segmentation, object segmentation, etc.
Category: Image Processing
Dataset Info: This dataset contains 1.5 million object instances with 80 object categories, 91 stuff categories and has been annotated with 5 captions per images.