
5 min
[caption id="attachment_15886" align="aligncenter" width="2000"] Hadoop vs HPCC Systems[/caption]
Hadoop is more commonly associated with the term “Big Data.” The underlying technology makes massive amounts of data accessible and is based on the open source Apache Hadoop project.
However, there is a competitor to Hadoop, called High Performance Computing Cluster (HPCC). The technique is more mature and enterprise-ready. LexisNexis developed HPCC Systems as an open source initiative. The initiative has helped Lexis Nexis to power its $1.5 billion data-as-a-service (DaaS) business.
HPCC Systems are open-sourced under the Apache 2.0 license, like their Hadoop counterparts. Moreover, both make use of commodity hardware and local storage interconnected through IP networks. This allows parallel data processing and/or querying across the architectures. However, this is where the similarities end.
 High Performance Computing Cluster[/caption]
HPCC Systems has been in production use for over 12 years now. But, the open source version has only been available since the last couple of years. These systems offer more mature enterprise-ready package. HPCC Systems essentially use a higher-level programming language called enterprise control language (ECL), that is based on C++. This is opposed to Hadoop’s Java-based approach. Moreover, Java relies on a Java virtual machine (JVM) to execute.
Key advantages of HPCC Systems:
 Apache Hive[/caption]
ECL is very much similar to high-level query languages such as SQL. Users can tell the computer what they want rather than instructing it how it’s done, implying ECL is declarative in nature, somewhat like SQL. To put it to perspective, a Microsoft Excel expert should generally have no major trouble picking up ECL.
HPCC Systems has worked with analytics provider Pentaho and its open source Kettle project, to simplify how queries are developed. This allows users to create ECL queries in a drag and drop interface. This feature is not available with Hadoop's Pig or Hive query languages. Besides being primitive, these languages are also hard to program and maintain. Moreover, it becomes a really difficult task to extend and reuse the code.
Moreover, HPCC Systems are designed to answer real-world questions. Hadoop, on the other end needs users to put together separate queries for each variable they seek, which makes the process more complex, unlike in case of HPCC Systems.
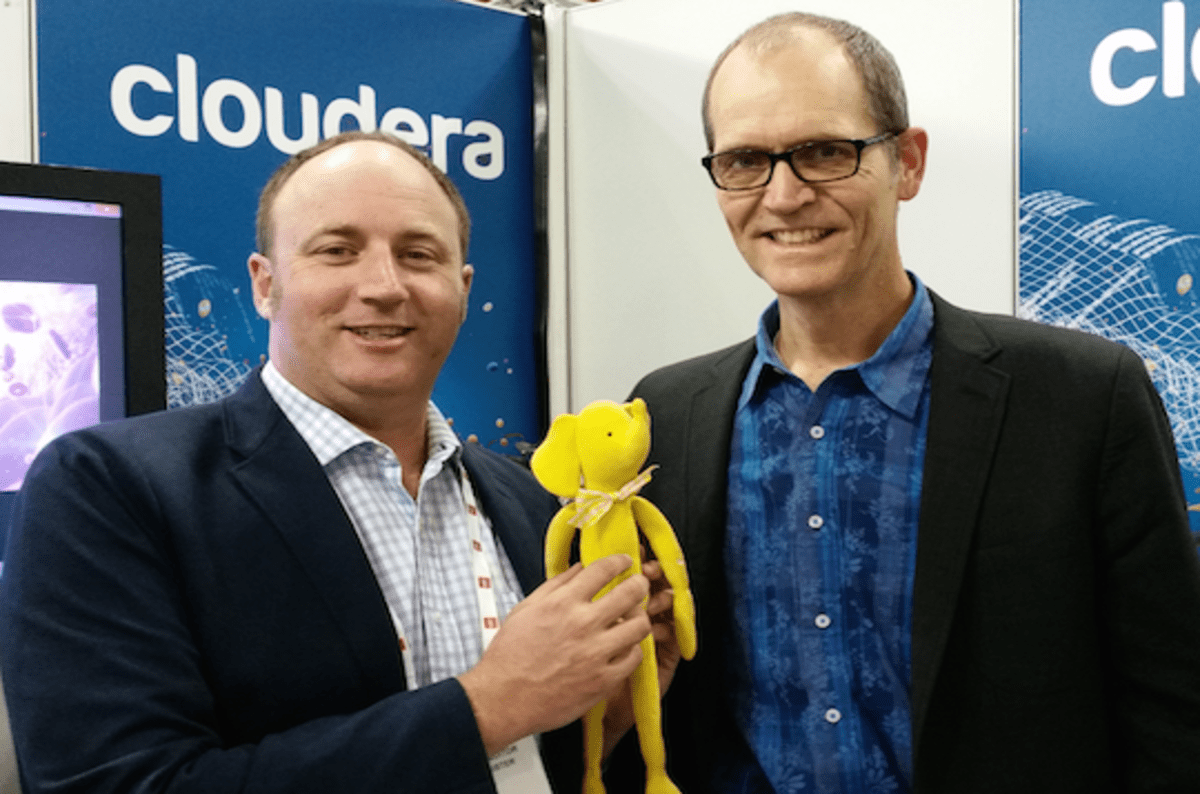 The inventor of Hadoop, Doug Cutting[/caption]
Hadoop was originally part of the Nutch project put together by Google. The organization aimed at parsing and analyzing log files. Until 2006, it wasn’t even Google’s own Apache project. However, since then, Hadoop has come to become the de facto standard for big data projects, and has a user base much larger than that of HPCC Systems. This is not all, Hadoop is supported by an open source community in the millions and an entire ecosystem of start-ups.
In other words, Hadoop reflects the capability to cater to a wider range of end users than the data management systems that have come before. Scalability, flexibility, and cost-effectiveness are the three key advantages of leveraging Hadoop.
Hadoop’s cost-effectiveness is what truly drives its popularity among users. Moreover, with HPCC Systems, much of the required functionalities are available outside the box, however, Hadoop runs on commodity hardware, where someone or a third-party provider has to be hired for putting everything together. Cloudera serves as the best-known and most successful example of Hadoop startups. The organization furnishes turnkey Hadoop implementations to companies as diverse as eBay, Chevron, and Nokia.
 Hadoop[/caption]
The rapid explosion of data is what’s fueling this transformation. Data is growing at a tremendous scale and speed, as more and more things get hooked up to computers; whether it’s your house, your TV, your cell phone, or the flight you took. This demands different architecture and different way of working with the data.
Thus, HPCC Systems might be the need of the hour if enterprises are looking for a robust solution that provides enterprise-grade functionality. However, Hadoop should be the best alternative, if enterprises just intend to get a feel for what big data is all about. Moreover, Hadoop provides a huge open-source ecosystem of developers working on it daily, besides a host of third-party organizations who want to make great use of the opportunity that big data presents.
 Hadoop vs HPCC Systems[/caption]
Hadoop is more commonly associated with the term “Big Data.” The underlying technology makes massive amounts of data accessible and is based on the open source Apache Hadoop project.
However, there is a competitor to Hadoop, called High Performance Computing Cluster (HPCC). The technique is more mature and enterprise-ready. LexisNexis developed HPCC Systems as an open source initiative. The initiative has helped Lexis Nexis to power its $1.5 billion data-as-a-service (DaaS) business.
HPCC Systems are open-sourced under the Apache 2.0 license, like their Hadoop counterparts. Moreover, both make use of commodity hardware and local storage interconnected through IP networks. This allows parallel data processing and/or querying across the architectures. However, this is where the similarities end.
Are HPCC Systems more efficient than Hadoop?
[caption id="attachment_15887" align="aligncenter" width="1798"] High Performance Computing Cluster[/caption]
HPCC Systems has been in production use for over 12 years now. But, the open source version has only been available since the last couple of years. These systems offer more mature enterprise-ready package. HPCC Systems essentially use a higher-level programming language called enterprise control language (ECL), that is based on C++. This is opposed to Hadoop’s Java-based approach. Moreover, Java relies on a Java virtual machine (JVM) to execute.
Key advantages of HPCC Systems:
- Ease of use
- Backup and recovery of production
- Speed is enhanced as C++ runs natively on top of the operating system
- Possesses more mission-critical functionality
How beneficial is it to integrate an Enterprise Control Language?
[caption id="attachment_15888" align="alignright" width="237"] Apache Hive[/caption]
ECL is very much similar to high-level query languages such as SQL. Users can tell the computer what they want rather than instructing it how it’s done, implying ECL is declarative in nature, somewhat like SQL. To put it to perspective, a Microsoft Excel expert should generally have no major trouble picking up ECL.
HPCC Systems has worked with analytics provider Pentaho and its open source Kettle project, to simplify how queries are developed. This allows users to create ECL queries in a drag and drop interface. This feature is not available with Hadoop's Pig or Hive query languages. Besides being primitive, these languages are also hard to program and maintain. Moreover, it becomes a really difficult task to extend and reuse the code.
Moreover, HPCC Systems are designed to answer real-world questions. Hadoop, on the other end needs users to put together separate queries for each variable they seek, which makes the process more complex, unlike in case of HPCC Systems.
How does Hadoop weigh in front of HPCC Systems?
[caption id="attachment_15890" align="aligncenter" width="1200"]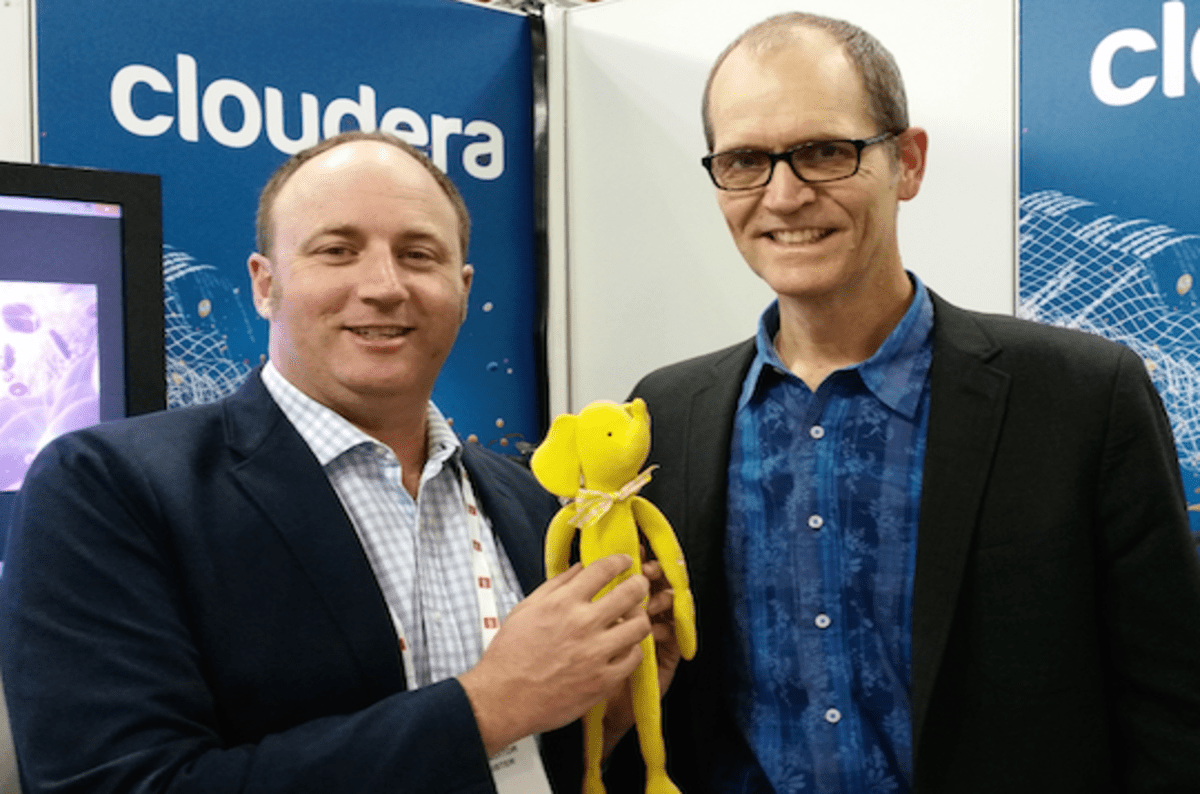 The inventor of Hadoop, Doug Cutting[/caption]
Hadoop was originally part of the Nutch project put together by Google. The organization aimed at parsing and analyzing log files. Until 2006, it wasn’t even Google’s own Apache project. However, since then, Hadoop has come to become the de facto standard for big data projects, and has a user base much larger than that of HPCC Systems. This is not all, Hadoop is supported by an open source community in the millions and an entire ecosystem of start-ups.
In other words, Hadoop reflects the capability to cater to a wider range of end users than the data management systems that have come before. Scalability, flexibility, and cost-effectiveness are the three key advantages of leveraging Hadoop.
Hadoop’s cost-effectiveness is what truly drives its popularity among users. Moreover, with HPCC Systems, much of the required functionalities are available outside the box, however, Hadoop runs on commodity hardware, where someone or a third-party provider has to be hired for putting everything together. Cloudera serves as the best-known and most successful example of Hadoop startups. The organization furnishes turnkey Hadoop implementations to companies as diverse as eBay, Chevron, and Nokia.
Last Words
[caption id="attachment_15891" align="alignleft" width="267"] Hadoop[/caption]
The rapid explosion of data is what’s fueling this transformation. Data is growing at a tremendous scale and speed, as more and more things get hooked up to computers; whether it’s your house, your TV, your cell phone, or the flight you took. This demands different architecture and different way of working with the data.
Thus, HPCC Systems might be the need of the hour if enterprises are looking for a robust solution that provides enterprise-grade functionality. However, Hadoop should be the best alternative, if enterprises just intend to get a feel for what big data is all about. Moreover, Hadoop provides a huge open-source ecosystem of developers working on it daily, besides a host of third-party organizations who want to make great use of the opportunity that big data presents.
- From Humanoid Robots to Telecom Trials, 12 Major Announcements at NVIDIA GTC Berlin 2026
- Anyone Can Make a Robot Move, Few Can Make It Stop
- After ISRO’s PSLV Failure, TakeMe2Space Looks to SpaceX for Reliable Launch
- Why AI Agents are the Next Frontier in Quantum Security
- Physical AI Squeezes Labour Market, And Low-Skilled Immigrant Jobs May Be First to Fall
- Rocket Math Isn’t Mathing: Why India’s Space Launches are Expensive