
5 min
 Traders follow a simple motto: buy low and sell high. But when the opposite happens, the stock market goes berserk.
On a fine morning in 2012, the NYSE had to step in and cancel numerous trades due to erroneous trading by Knight Capital which saw the biggest drop ever since it went public. Instead of at least attempting to provide liquidity via limit trades, Knight's algorithm acted as a market order.
Naturally, when the entire logic of trading was perverted courtesy of Knight's busted algorithm, everything went chaos, and stocks went higher because they went higher, and the higher they went, the greater the incentive for the algorithm to keep pushing the stock higher.
In other terms, the algorithm bought high and sold low. This was clearly a scenario from the whole “what could go wrong” mindset in deploying advanced methodologies. Now, in 2019, machine learning algorithms are deployed aggressively in the finance and healthcare sector.
Whether it is the market crash or a wrong diagnosis, the after-effects will be certainly irreversible.
Tracking the development of machine learning algorithm throughout its life cycle, therefore, becomes crucial.
Life Cycle Of ML Models
The typical life cycle of deployment machine learning models involves a training phase, where a typical data scientist develops a model with good predictive based on historical data. This model is put into production with the hope that it would continue to have similar predictive performance during the course of its deployment. But there can be problems associated with the information that is deployed into the model such as:- an incorrect model gets pushed
- incoming data is corrupted
- incoming data changes and no longer resembles datasets used during training
Significance Of Similarity Scores
There are three pressing issues that Similarity scores aim to address:- Low number of samples: since the Similarity score is calculated based on the parameters of the multinoulli distribution and does not rely on the inference distribution, it is agnostic of the number of samples
- Inference samples fall in a narrow range of training distribution:
- The subset of patterns seen during inference might either have poor training coverage or good training coverage.
Architecture Of ML Health
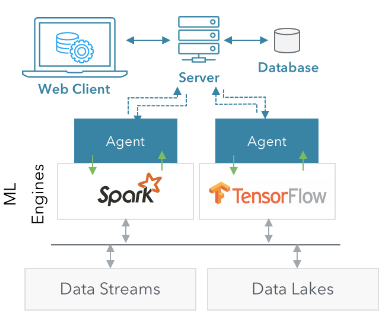 Source: Paper by ParallelM
At the core of this architecture is a Server and an Agent. The Server keeps track of all the deployments across agents, while the agents themselves are agnostic of all the jobs running in the system.
Users can leverage built-in applications and health metrics, create new applications and/or metrics, or import their existing ML pipelines and health-metric computations using any of the popular programming languages.
Datasets Used
The results were taken by running the model on three publicly available datasets (a) Human Activity Recognition (Samsung) (b) Video Transcoding Time [20] and (c) TELCO Samsung is an activity recognition dataset with 6 classes as labels. It consists of 560 features. Video dataset has video transcoding time as the label and consists of 10 is a binary classification dataset with SLA violations as the label. It consists of 24 Features. Activity and Video datasets are used as is without normalization. Random forest classification and regression are used respectively for the Activity and Video datasets. These datasets are divided into train and test using random shuffling. The sources of these datasets do not claim to provide varying distributions. TELCO dataset inherently consists of different loads seen in the network. Ideally, this should be reflected in the data-deviation scores. Know more about the research hereKey Takeaways
- Similarity score performs consistently well in the presence and absence of noise agnostic of the number of samples present in inference. This is demonstrated by the results across three datasets, briefly described below.
- Similarity score shows the highest correlation with the predictive performance of the algorithm/model when a small number of samples are present in the incoming data across the three datasets.
- Similarity score shows a high correlation with the predictive performance of the algorithm/model when the nature of incoming data changes and the number of samples is small. This is demonstrated using the TELCO dataset across three different loads.
- All the data deviation scores perform equally well when there is data corruption, irrespective of the number of samples in the incoming data across all three datasets.
- From Humanoid Robots to Telecom Trials, 12 Major Announcements at NVIDIA GTC Berlin 2026
- Anyone Can Make a Robot Move, Few Can Make It Stop
- After ISRO’s PSLV Failure, TakeMe2Space Looks to SpaceX for Reliable Launch
- Why AI Agents are the Next Frontier in Quantum Security
- Physical AI Squeezes Labour Market, And Low-Skilled Immigrant Jobs May Be First to Fall
- Rocket Math Isn’t Mathing: Why India’s Space Launches are Expensive