Key takeaways
- NVIDIA researchers developed a multilingual AI model to facilitate real-time conversations across different languages.
- The team won the LIMMITS ’24 challenge by replicating a speaker's voice using a three-second sample.
- Personal motivations drove the researchers to create solutions for communicating with their spouses' families.
- The project utilized the P-Flow model, showcasing its potential in multilingual applications.
- The achievement highlights advancements in AI technology for enhancing cross-cultural communication.
NVIDIA researchers, Akshit Arora and Rafael Valle, wanted to speak to their wives’ families in their native languages. Arora, a senior data scientist supporting one of NVIDIA’s major clients, speaks Punjabi, while his wife and her family are Tamil speakers, a divide he has long sought to bridge. Valle, originally from Brazil, faced a similar challenge as his wife and family speak Gujarati.
“We’ve tried many products to help us have clearer conversations,” said Valle. This motivation led them to build multilingual text-to-speech models that could convert their voice into different languages in real time, which led them to winning competitions.
Arora, in an exclusive interview with AIM, shed more light on this. “When this competition came to our radar, it occurred to us that one of the models that we had been working on called P-Flow, would be perfect for this kind of a competition,” said Arora, which is also narrated in his latest blog.
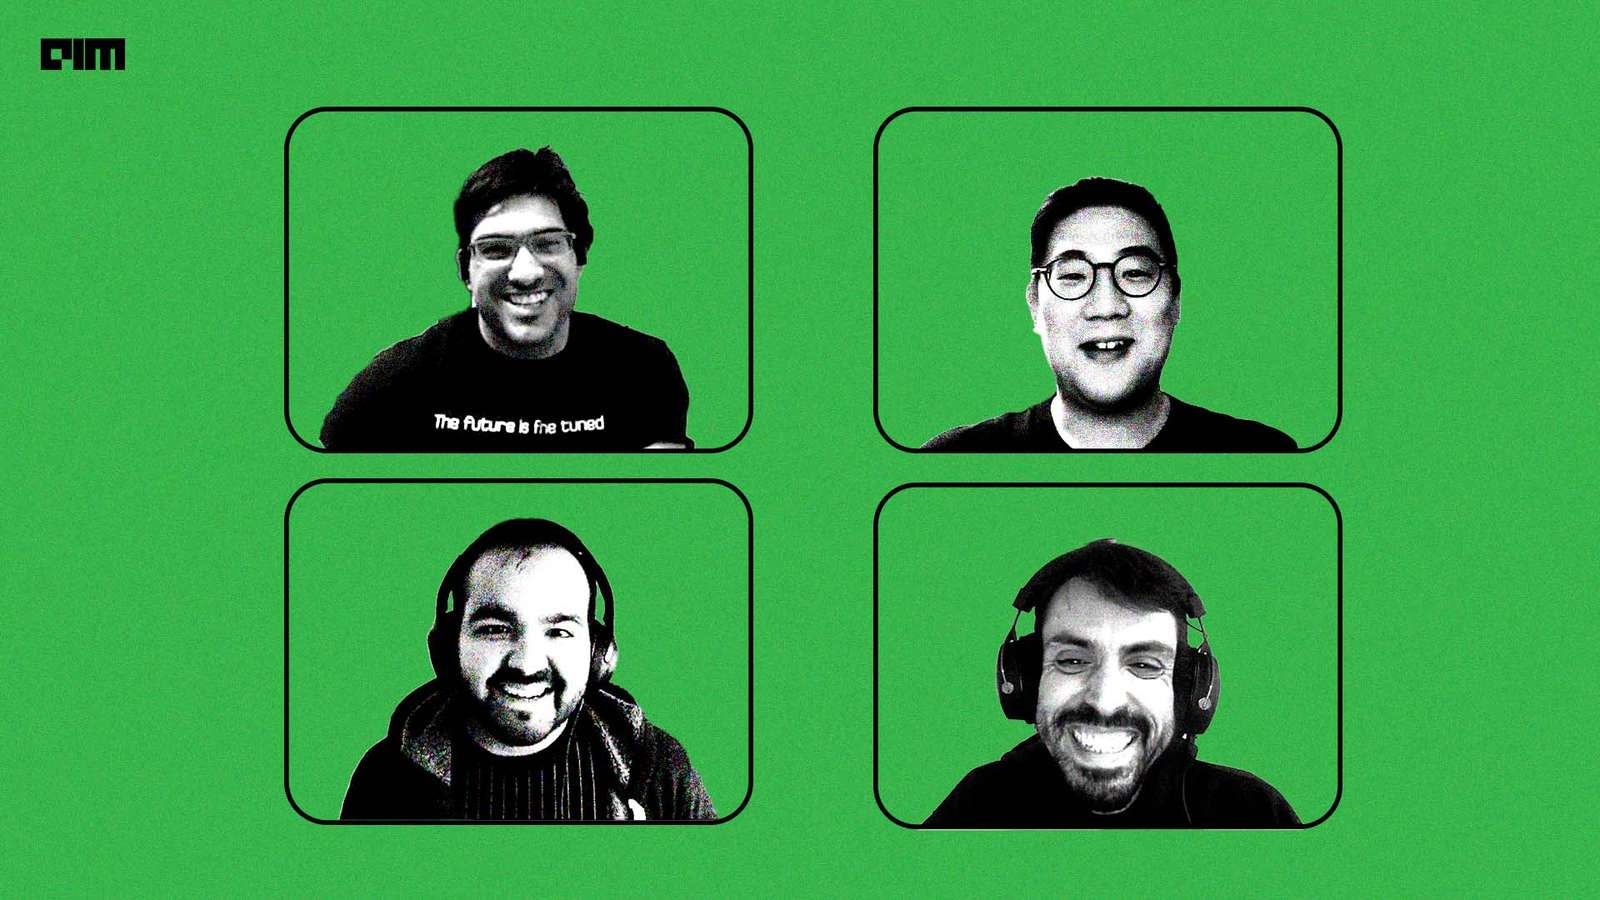
Arora and Valle, along with Sungwon Kim and Rohan Badlani, triumphed in the LIMMITS ’24 challenge, which tasked participants with replicating a speaker’s voice in real-time in different languages. Their innovative AI model achieved this feat using only a brief three-second speech sample.
Fortunately, Kim, a deep learning researcher at NVIDIA's Seoul office, had been working on an AI model well-suited for the challenge for some time. For Badlani, residing in seven different Indian states, each with its own dominant language, inspired his involvement in the field.
The Signal Processing, Interpretation, and Representation (SPIRE) Laboratory at IISc in Bangalore orchestrated the MMITS-VC challenge, which stood as one of the major challenges within the IEEE International Conference on Acoustics, Speech, and Signal Processing (ICASSP) 2024.
In this challenge, a total of 80 hours of Text-to-Speech (TTS) data were made available for Bengali, Chhattisgarhi, English, and Kannada languages. This additional dataset complemented the Telugu, Hindi, and Marathi data previously released during LIMMITS 23.
Never seen before
The competition included three tracks where the models were tested. “One of the models got into the top leaderboard on all the counts for one of the tracks,” said Arora. “In these kinds of competitions, not even a single model performs best on both the tracks. Every model is good at certain things and not good at other things,” explained Arora.
NVIDIA's strategy for Tracks 1 and 2 revolves around the utilisation of RAD-MMM for few-shot TTS. RAD-MMM works by disentangling attributes such as speaker, accent, and language. This disentanglement enables the model to generate speech for a specific speaker, language, and accent without the need for bilingual data.
In Track 3, NVIDIA opted for P-Flow, a rapid and data-efficient zero-shot TTS model. P-Flow utilises speech prompts for speaker adaptation, enabling it to produce speech for unseen speakers with only a brief audio sample. Part of Kim’s research, P-Flow models borrow the technique large language models employ of using short voice samples as prompts so they can respond to new inputs without retraining.
One of the unique things about P-Flow is its zero-shot capabilities. “Our zero shot TTS model happened to perform the best in the zero shot category on the speaker similarity and naturalness course,” said Arora. They would also be presenting this model at GTC 2024.
A long project
Last year, the researchers also used RAD-MMM, developed by NVIDIA Applied Deep Learning Research Team, and developed “VANI” or “वाणी”, which a very lightweight multi-lingual accent controllable speech synthesis system. This was also used in the competition.
The journey began nearly two years ago when Arora and Badlani formed the team to tackle a different version of the challenge slated for 2023. Although they had developed a functional code base for the so-called Indic languages, winning in January required an intense sprint, as the 2024 challenge came onto their radar just 15 days before the deadline.
P-Flow is set to become a part of NVIDIA Riva, a framework for developing multilingual speech and translation AI software, included in the NVIDIA AI Enterprise software platform. This new capability will enable users to deploy the technology within their data centres, personal systems, or through public or private cloud services.
Arora expressed hope that their customers would be inspired to explore this technology further. “I enjoy being able to showcase in challenges like this one the work we do every day,” said Arora.