Key takeaways
- Google has developed Visual Language Maps, combining visual-language features with spatial mapping for precise navigation.
- VLMaps can be created using standard exploration techniques from robot video feeds without needing extra labelled data.
- The system uses a visual-language model to generate pixel-level representations, enhancing the mapping of real-world environments.
- Landmark names are encoded in an open-vocabulary format and aligned with VLMap pixels through cosine similarity calculations.
- Large language models like GPT-3 assist in generating executable navigation code from natural language instructions.
Google in collaboration with two German Universities – The University of Technology Nuremberg and University of Freiburg has introduced Visual Language Maps or VLMaps. VLMaps merges pre-trained visual-language features with spatial mapping of the real world to replicate precision of classic geometric maps.
Standard exploration techniques can be used to create VLMaps from robot video feeds without any additional labeled data, and these maps facilitate natural language indexing.
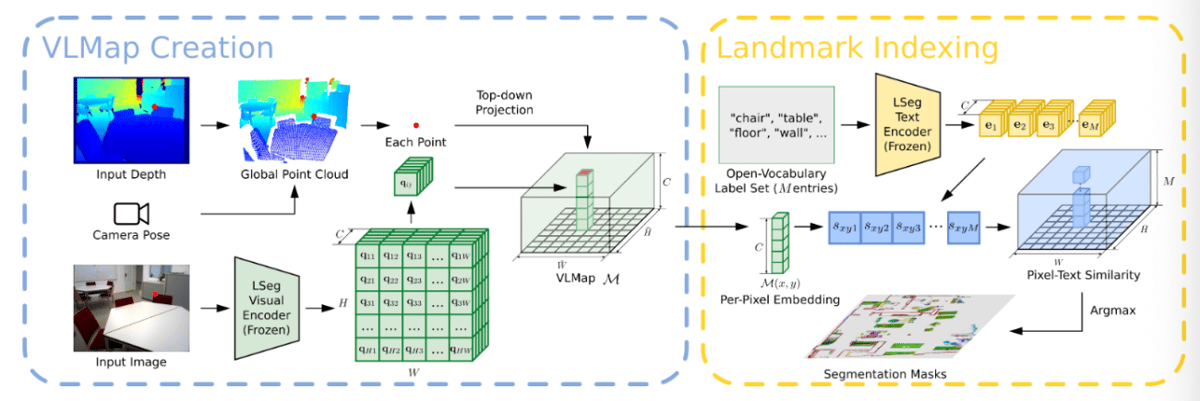
This is accomplished by utilising a visual-language model to generate rich pixel-level representations from the RGB-D video feed of the robot, and then projecting these representations onto the 3D surface of the environment. This surface is captured through depth data used for reconstruction using visual odometry.
Ultimately, the scene's top-down representation is created by saving the visual-language characteristics of every image pixel at the corresponding location of the grid map pixel.
How VLMaps navigates & processes natural language
Firstly, the text encoders within the Visual Language Model are used to encode the names of landmarks in an open-vocabulary format, such as "chair", "green plant", and "table". Next, these landmark names are aligned with the pixels in the VLMap by calculating the cosine similarity between their embeddings. By performing an argmax operation on the similarity score, the mask for each type of landmark is obtained.
Additionally, large language models are used to create navigation policies in the form of code that can be executed. To achieve this, GPT-3 is utilised. It is provided with a few examples as prompts. GPT-3 parses the language instructions and produces a string of executable code, which includes expressions of functions or logical structures and API calls with parameterisation (e.g., robot.move_to(target_name) or robot.turn(degrees)).
Using VLMaps between multiple robots
VLMaps facilitate natural language-based, long-horizon spatial goal navigation by using open-vocabulary landmark indexing.
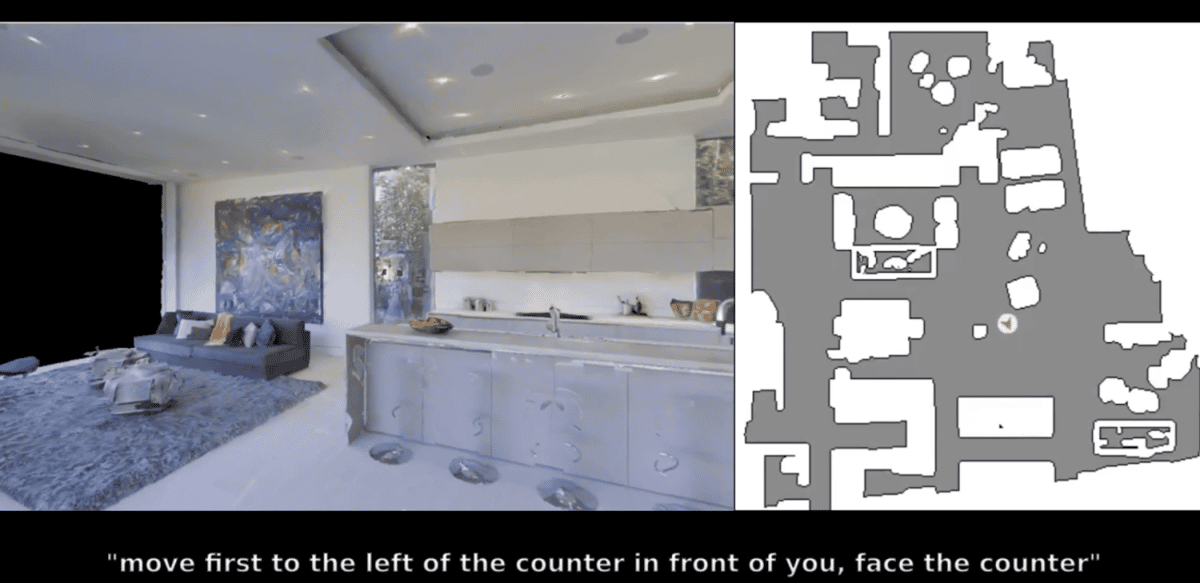
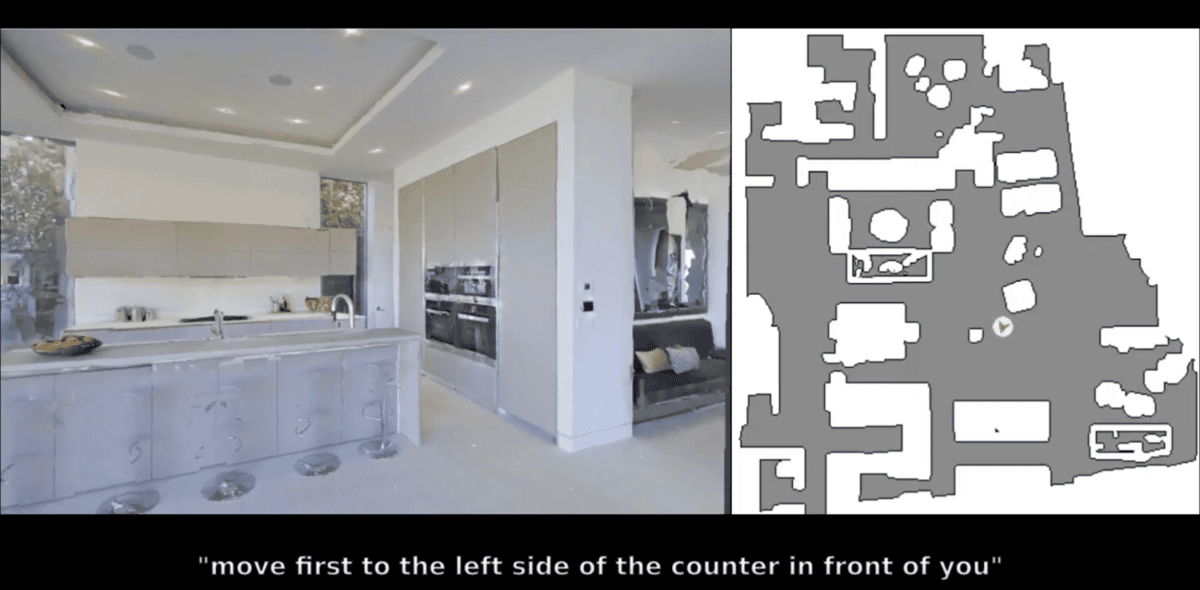
Sharing a VLMap between multiple robots allows for the generation of obstacle maps specific to different embodiments in real-time, which improves navigation efficiency. For instance, while a ground robot must avoid obstacles, a drone can ignore them.
The team conducted experiments to demonstrate how a single VLMap representation in each scene can adjust to different embodiments by creating custom obstacle maps and enhancing navigation efficiency.
Spotted an error? Tell our editors. Read our editorial standards and corrections.