
5 min
 Google is at an inflection point where it is doubling down on its existing deep learning techniques. For example, the company’s latest research, AutoAugment: Learning Augmentation Policies from Data, explores a reinforcement learning algorithm which increases the amount and diversity of data in an existing training dataset. The latest research tackles deep learning’s biggest hurdle — huge amount of quality data to train models. So, the Mountain View-based company took it upon itself to find ways to automatically augment existing data with machine learning. Building on the results of AutoML, the AI research team has designed neural network architecture and optimisers to replace components of systems which were previously designed by humans. Basically, the team has attempted to automate the procedure of data augmentation.
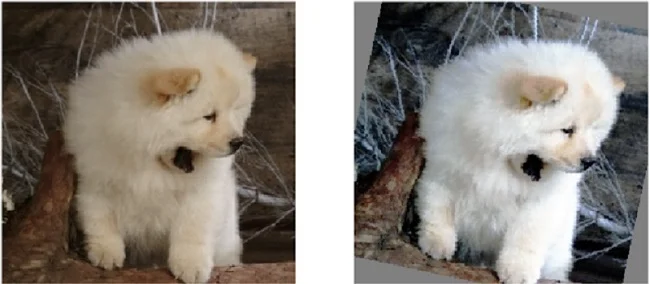
The paper describes a procedure called data augmentation for images that help in searching for improved data augmentation policies. The key highlight is creating a search space of data augmentation policies, evaluating the quality of a particular policy directly on the dataset of interest. For implementation, the researchers have designed a search space where a policy consists of many sub-policies, one of which is randomly chosen for each image in each mini-batch. A sub-policy consists of two operations, each operation is an image processing function such as translation, rotation, or shearing, and the probabilities and magnitudes with which the functions are applied. “We use a search algorithm to find the best policy such that the neural network yields the highest validation accuracy on a target dataset,” notes the research paper.
According to Google, their the research team score is unlike the earlier state-of-the-art deep learning models which leveraged hand-designed data augmentation policies. In fact, this the team has relied on RL to find the optimal image transformation policies from data. “The result improved performance of computer vision models without relying on the production of new and ever-expanding datasets,” noted the blog.

Your reaction
Discussion
What's your take on this story?
No comments yet — be the first to share your view.