Key takeaways
- 2022 witnessed significant advancements in art generation technologies, particularly in text-to-image, text-to-audio, and text-to-video.
- OpenAI's DALL E-2 led the trend in text-to-image generation, followed by other notable systems like Imagen and Midjourney.
- The capabilities of these generators are becoming accessible beyond the tech-savvy community, reaching a broader audience.
- The evolution of these technologies reflects a fusion of mechanisation and creativity, reminiscent of artistic concepts from earlier cinema.
The 1964 American movie, ‘What A Way To Go!’, had the lead character Larry Flint create a painting machine to produce his abstract art. He develops abstract painting machines consisting of a controllable arm with a paint-brush hand. Explaining the concept to Louisa, the female lead, he says, "The sonic vibrations that go in there get transmitted to this photoelectric cell which gives those dynamic impulses to the brushes and the arms. It's a fusion of a mechanised world and the human soul.”
(A still from the movie ‘What A Way To Go!’)
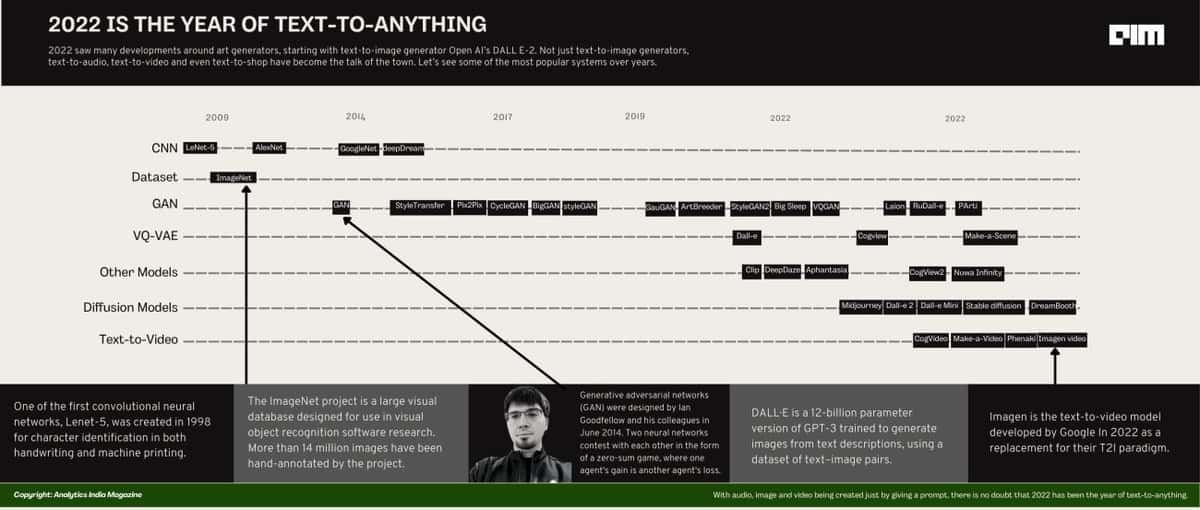
What the director had envisioned in 1964 with the movie, our programmers have achieved all that and much more in 2022. This year saw many developments around art generators, starting with text-to-image generator Open AI’s DALL E-2. Not just text-to-image generators, text-to-audio, text-to-video and even text-to-shop have become the talk of the town. Let’s see some of the most popular systems.
Text-to-image
The year began with DALL E-2, followed swiftly by Imagen, Midjourney and Stable Diffusion making their mark in the industry. Today, text-to-image is not limited to the “tech-savvy” community alone. It’s being increasingly put to varied uses. Cosmopolitan, for instance, had its cover designed by DALL E2 for its June 2022 edition. Jason Allen won first prize in the Colorado State Fair fine arts competition by submitting an art made by Midjourney. And not to forget, our own in-house event Cypher 2022, took Midjourney graphics to a whole different level by adorning the entire venue in futuristic images.
(Most of our promotional posters were designed with the help of Midjourney)
As we speak, we are witnessing a text-to-image revolution unfold right before our eyes – one that was kickstarted by DALL E-2, and leveraged to new heights by Stable Diffusion. Being open source, Stable Diffusion gave us options we never thought we could have. For example, today, popular platforms like Photoshop, Blender, and even Canva use Stable Diffusion plugins, and the results are just awesome.
Text-to-video
If text-to-image is here, can text-to-video be far behind? Can’t say if we’ve succeeded at this or not, given that the computation cost for text-to-video generation is exponentially high, making training from scratch nearly unaffordable for most users. However, there have been some developments around this segment too.
Beginning with Stable Diffusion X Runway, the industry has seen many other players release their own text-to-video models, such as DeepMind's 'Transframer,' which can generate coherent 30-second videos, and Microsoft's NUWA Infinity, which claims to be capable of generating high-quality videos from any given prompts.
Meta jumped into the bandwagon with its new AI system, 'Make-A-Video' that allows users to input prompts to make high-quality video clips. What lies ahead is a question in its own accord but since we are discussing images and videos in 2D, the question arises if there is a generative model that makes 3D models using text prompts?
Text-to-3D
Yes! Google's ever-innovative researchers have discovered a method to produce 3D models based on a user's word input. The new technology, dubbed 'DreamFusion’, employs 2D Diffusion and is expected to make significant advances in text-to-image generation.
Text-to-audio
And if text-to-image and text-to-video were not enough, now there is also text-to-audio in the market.
A team of Meta scientists have released AudioGen, an auto-regressive generative model that generates audio samples based on text inputs.
With audio, image and video being created just by giving a prompt, there is no doubt that 2022 has been the year of text-to-anything. This also begs the question, what’s next? With AI advancing at unimaginable speed, it’s difficult to predict that. But let’s keep our eyes peeled for it.