
AI4Bharat has launched a series of innovations aimed at enhancing Indian language technology, including speech recognition, data annotation, and expressive text-to-speech (TTS).
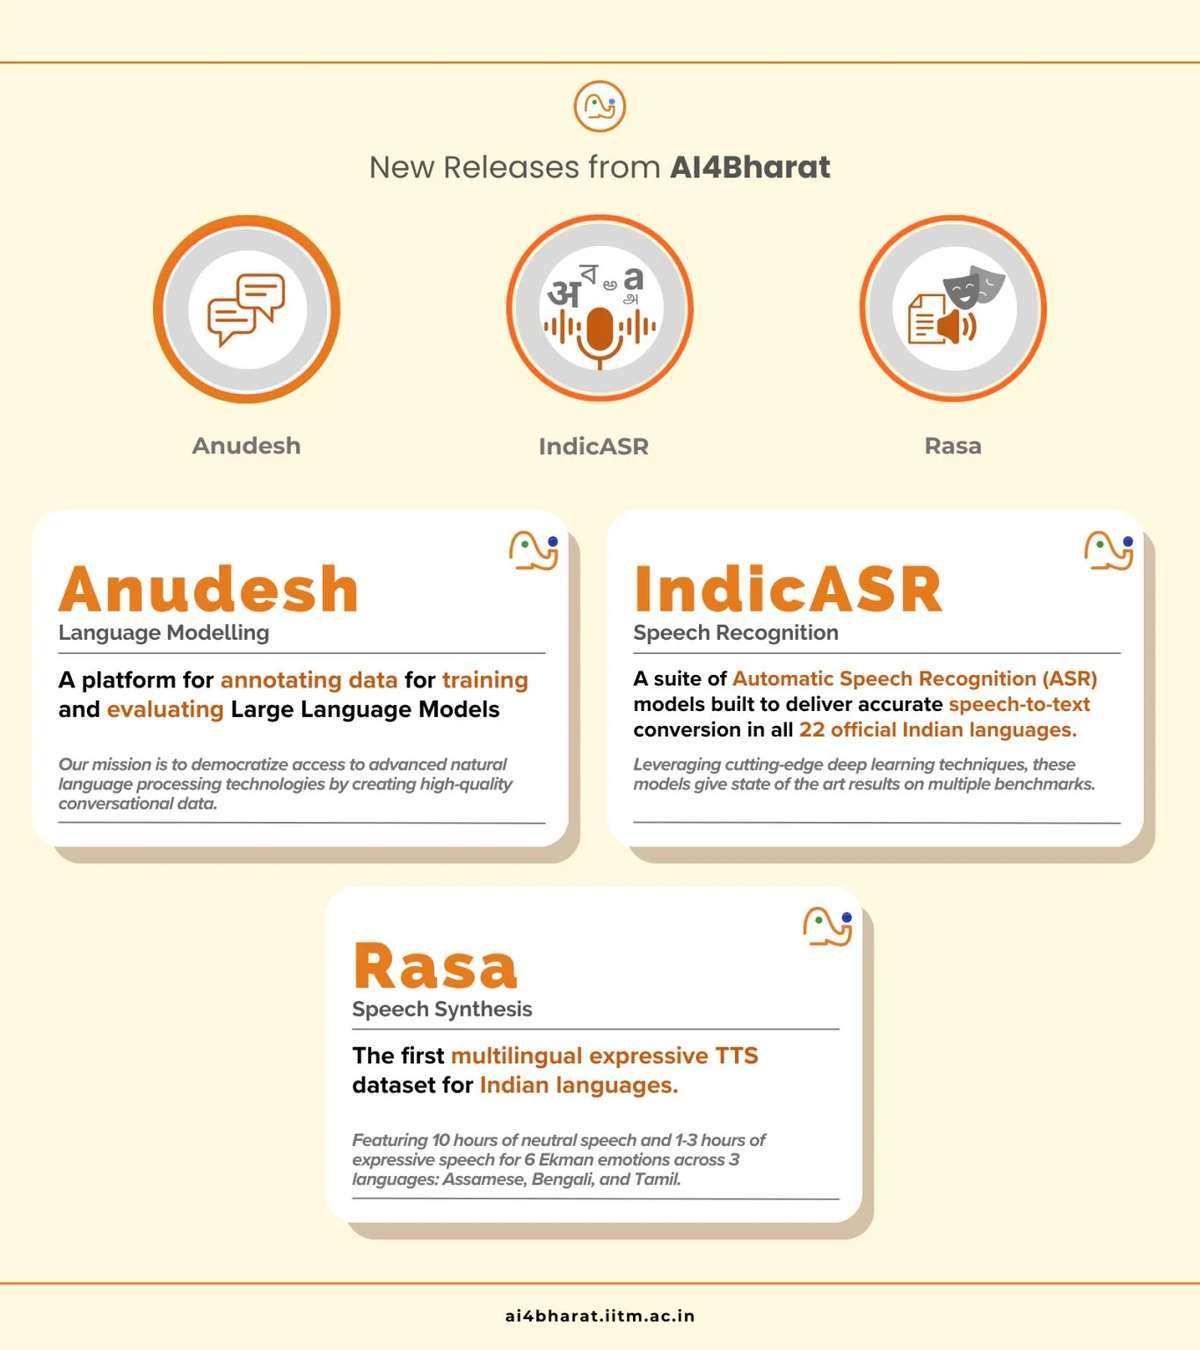
One of the key releases is IndicASR, India’s first speech recognition model covering all 22 official languages. A web demo is available for users to test and provide feedback. Also called ndicConformers, it is a comprehensive set of ASR models designed to accurately convert speech to text in all 22 official Indian languages.
Another major release is Anudesh, v0.1, an open-source platform designed to improve LLMs for Indian languages through data annotation. The platform’s first version facilitates conversational data collection through LLM interactions and supports model evaluation workflows.
Additionally, AI4Bharat has introduced Rasa, a dataset for expressive TTS that spans nine languages and features 14 speakers. The dataset includes at least 20 hours of speech per speaker, aiming to feature both male and female voices across all 22 official Indian languages. In its initial version, it presents a practical approach to gathering high-quality data for languages with limited resources, focusing on easily accessible neutral speech data, complemented by smaller samples of expressive speech.
The organisation has also revamped its website, making datasets, models, and tools more accessible. Users can now find clear download instructions, usage guidelines, and supporting Colab notebooks for easier integration of AI4Bharat’s resources.
Last month, Sarvam AI also launched ASR models Shuka v1, which comprises approximately 60 million parameters and is trained on less than 100 hours of audio data.
- Anthropic Seeks Up to $64.4 Bn at $1.4 Tn Valuation With IPO
- IBM Ends H-1B, Green Card Sponsorship for Most Roles in Consulting Division
- PuppyGraph Raises $10 Mn to Help AI Agents Query Enterprise Tables
- Cognizant Commits 25,000 Professionals to Deploy Claude in Enterprises
- TSMC October Revenue Hits Record $17.81 Bn on Skyrocketing AI Chip Demand
- Froncort.AI Gets $2.3M From Google.org to Expand AI-Based Disease Screening in India