
Researchers from ByteDance and the University of Hong Kong recently developed Groma, a multimodal Large Language Model (MLLM) that excels in region-level image tasks by utilising a localised visual tokenisation approach and leveraging GPT-4V.
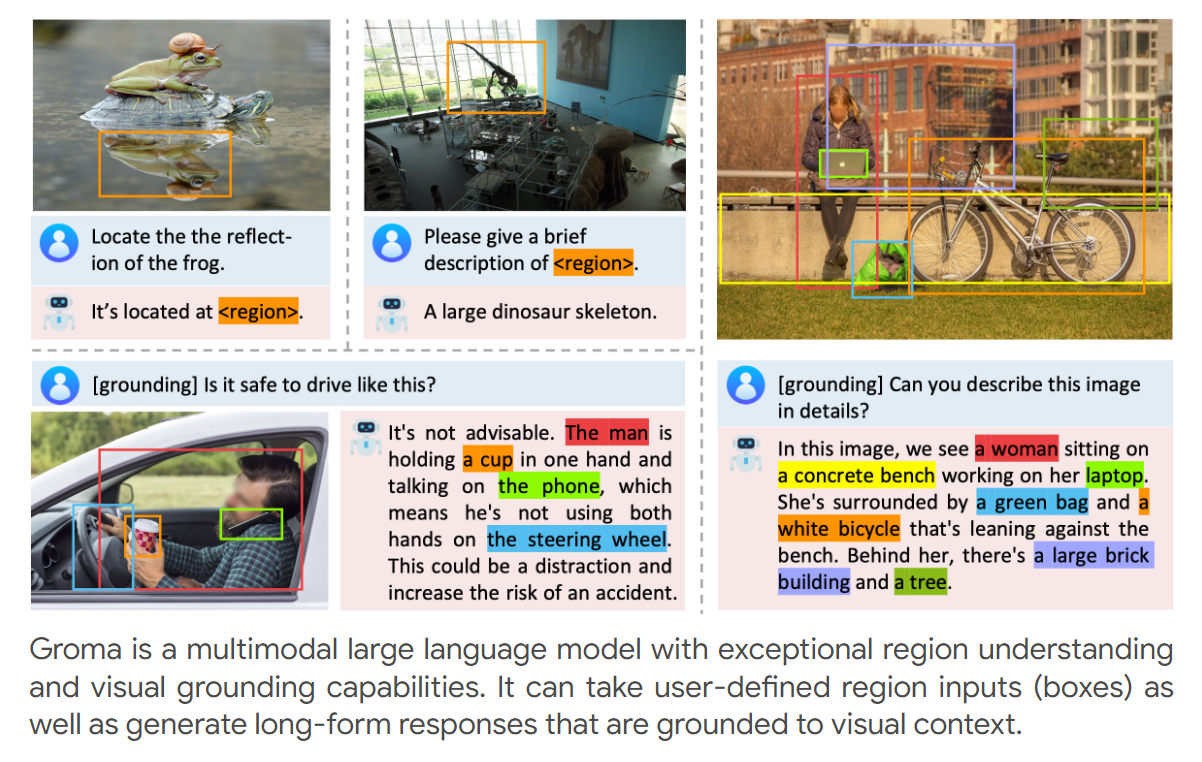
Groma excels not only in comprehensive image understanding but is also adept at region-level tasks such as region captioning and visual grounding. Instead of depending on LLMs or external modules for localization, Groma leverages the spatial understanding capability of the visual tokenizer. This ‘perceive-then-understand’ design also resembles human vision process.
In this localized visual tokenization mechanism, an image is segmented into regions of interest, which are then converted into region tokens. Groma encodes the image into both global image tokens and local region tokens. By integrating region tokens into user instructions and model responses, Groma understands user-specified region inputs and ground its textual output to images.
Source: github.io
Furthermore, to improve Groma's ability to engage in visually grounded conversations, the team curated a dataset of 30k visually grounded conversations for instruction finetuning. This marks the first grounded chat dataset constructed with both visual and textual prompts, leveraging the powerful GPT-4V for data generation.
In contrast to other MLLMs that depend on the language model or external module for localization, Groma consistently shows superior performances in standard referring and grounding benchmarks. This highlights the benefits of embedding localization into image tokenization.

Your reaction
Discussion
What's your take on this story?
No comments yet — be the first to share your view.