
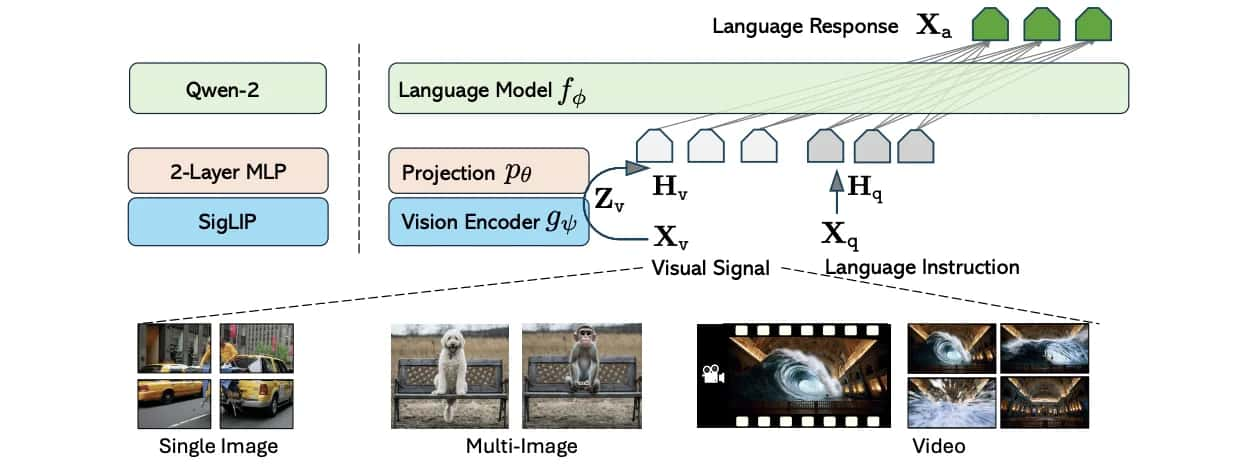
A team of researchers has introduced LLaVA-OneVision, a new open-source large multimodal model (LMM) that demonstrates unprecedented capabilities across single-image, multi-image, and video understanding tasks. The model, developed by consolidating insights from the LLaVA-NeXT blog series, achieves state-of-the-art performance on various benchmarks and exhibits emerging capabilities through task transfer.
Read the full paper here
LLaVA-OneVision outperforms existing open-source models and approaches the capabilities of advanced commercial models like GPT-4V in several areas. The model excels in tasks such as chart and diagram understanding, visual reasoning, and real-world image comprehension.
The model offers strong performance across various scenarios, including single-image, multi-image, and video processing. It demonstrates emerging capabilities through effective cross-scenario task transfer, enabling it to adapt and excel in different contexts. Additionally, LLaVA-OneVision achieves state-of-the-art results on numerous benchmarks, solidifying its position as a leading solution in its field.
The researchers employed a curriculum learning approach, training the model in stages to handle increasingly complex tasks. They also curated a large collection of high-quality datasets for training, emphasising the importance of data quality over quantity.
LLaVA-OneVision's architecture builds on previous LLaVA models, incorporating improvements in visual representations and training strategies. The team used the Qwen-2 language model and SigLIP vision encoder as core components.
This breakthrough has significant implications for the development of general-purpose AI assistants capable of understanding and reasoning about visual information across various modalities. The researchers have open-sourced their model, code, and datasets to facilitate further advancements in the field.
As AI continues to evolve, LLaVA-OneVision represents a significant step towards more versatile and capable multimodal systems that can understand and interact with visual information in increasingly sophisticated ways.
- Chai Point Cuts Monthly AWS Bill by 58%
- Bengaluru AI Startup Simplismart Raises $14 Mn in NVIDIA-Backed Round
- Maya Research Releases Open-Weight Speech Model Supporting 12 Languages
- Anthropic Sued Over Alleged Use of Elvis Presley Songs to Train Claude, Denies Claim
- CoRover Lists Three BharatGPT Models On Government-Backed AIKosh Platform
- Cent Raises $15 Million to Expand AI-Powered Preventive Healthcare