Key takeaways
- JPMorgan launches DocLLM, a generative model for multimodal document understanding.
- Utilizes bounding box information, avoiding costly image encoders for spatial layout analysis.
- Employs a disentangled spatial attention mechanism for effective text-layout alignment.
- Pre-trained on diverse datasets, including legal documents and unique layouts.
- Outperforms existing LLMs in various document intelligence evaluations.
JPMorgan has introduced DocLLM, a generative language model designed for multimodal document understanding. DocLLM stands out as a lightweight extension to LLMs for analysing enterprise documents, spanning forms, invoices, reports, contracts that carry intricate semantics at the intersection of textual and spatial modalities.
Unlike existing multimodal LLMs, DocLLM strategically avoids expensive image encoders and focuses exclusively on bounding box information to incorporate spatial layout structures. The model introduces a disentangled spatial attention mechanism by decomposing the attention mechanism in classical transformers into a set of disentangled matrices.
DocLLM tackles irregular layouts and heterogeneous content in visual documents by employing a pre-training objective that focuses on learning to infill text segments.
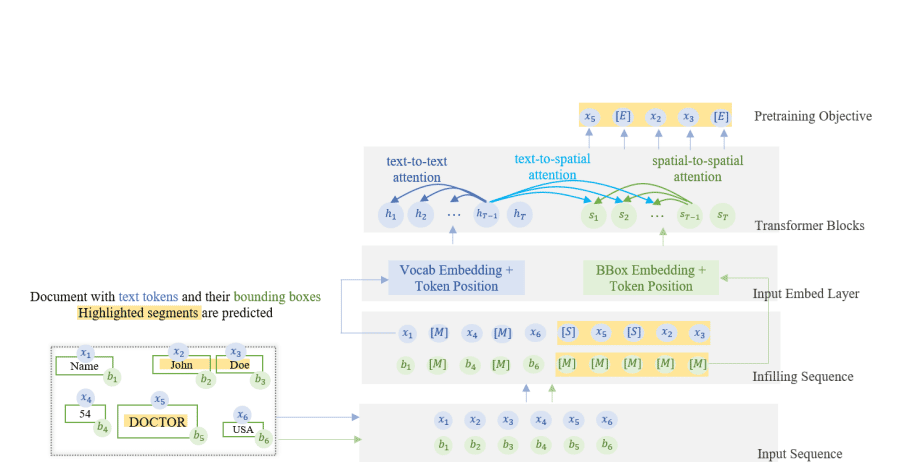
The model features a disentangled spatial attention mechanism facilitating cross-alignment between text and layout modalities, an infilling pre-training objective adept at handling irregular layouts effectively.
For pre-training DocLLM, data was gathered from two primary sources: IIT-CDIP Test Collection 1.0 and DocBank. The former comprises over 5 million documents related to legal proceedings against the tobacco industry during the 1990s, while the latter consists of 500,000 documents, each featuring distinct layouts.
Extensive evaluation across various document intelligence tasks demonstrates DocLLM's superiority over state-of-the-art LLMs. The model outperforms equivalent models on 14 out of 16 known datasets and exhibits robust generalisation to previously unseen datasets in 4 out of 5 settings.
Looking ahead, JPMorgan expresses its commitment to infusing vision into DocLLM in a lightweight manner, further enhancing its capabilities.