
Meta has introduced MEGALODON, a neural architecture for efficient sequence modelling with unlimited context length. It is designed to address the limitations of the Transformer architecture in handling long sequences, including quadratic computational complexity and limited inductive bias for length generalisation.
Click here to check out the GitHub repository.
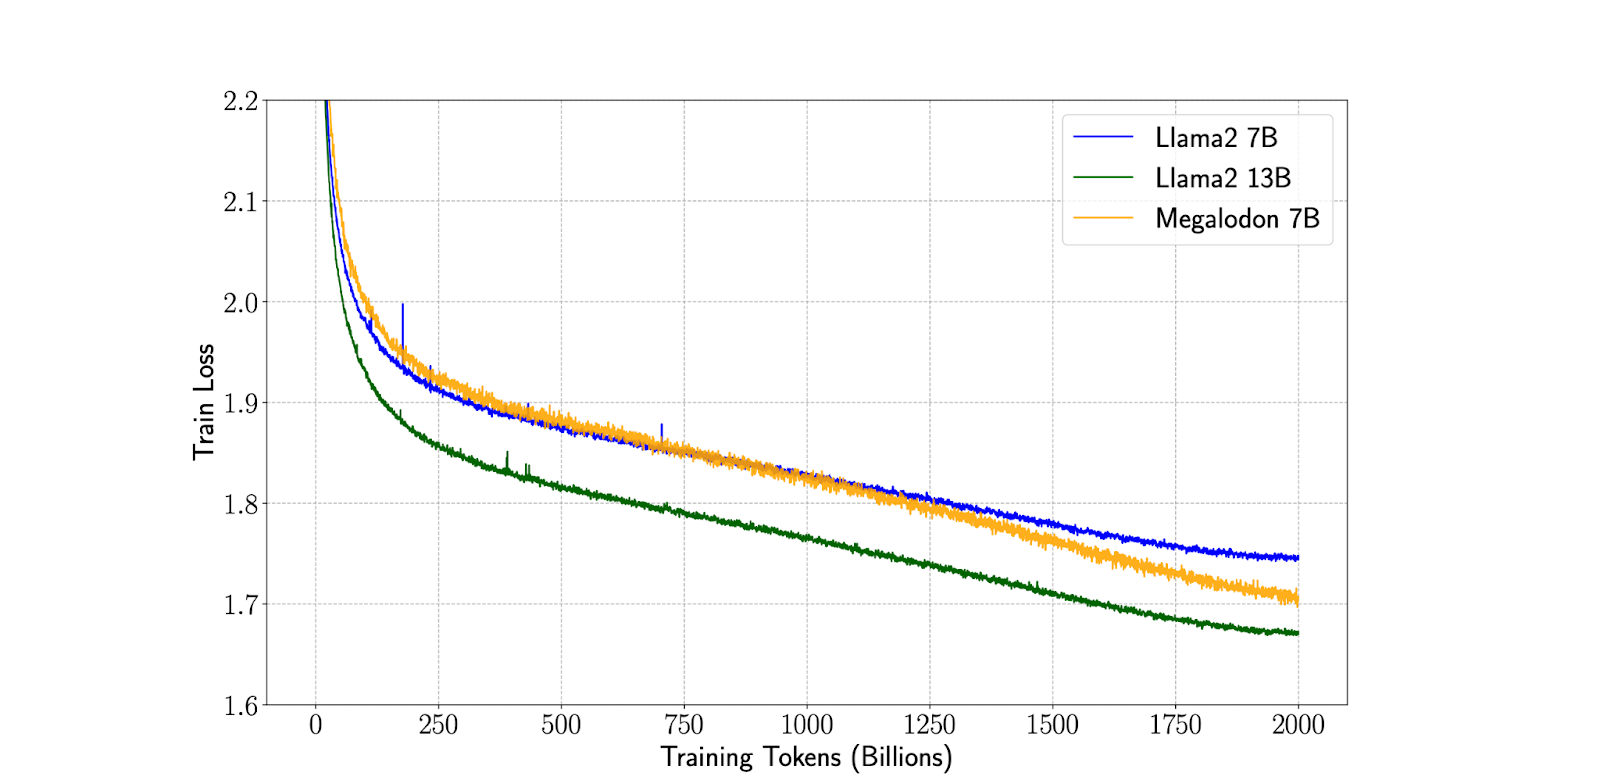
In direct comparisons with Llama 2, MEGALODON demonstrates superior efficiency at a scale of 7 billion parameters and 2 trillion training tokens, with a training loss of 1.70—positioned between LLAMA2-7B (1.75) and LLAMA2-13B (1.67). MEGALODON's improvements over Transformers are consistent across a range of benchmarks, encompassing different tasks and modalities.
To evaluate MEGALODON's performance, various experiments were conducted, including large-scale long-context pretraining. The model was scaled up to 7 billion parameters and applied to large-scale language models pretraining on 2 trillion tokens.
MEGALODON introduces key innovations such as the complex exponential moving average (CEMA) component, which extends the multi-dimensional damped EMA to the complex domain, and the timestep normalization layer, which allows normalization along the sequential dimension in autoregressive sequence modeling tasks. Other improvements include normalized attention and pre-norm with two-hop residual configurations.
MEGALODON’s linear computational and memory complexity during training and inference is achieved by chunking input sequences into fixed blocks as in MEGA-chunk. This results in efficient long-context pretraining and better data efficiency. MEGALODON is evaluated across various scales of language modeling and downstream domain-specific tasks, showcasing its ability to model sequences of unlimited length.
MEGALODON's instruction fine-tuning performance is also notable. Fine-tuning the base model of MEGALODON-7B on proprietary instruction-alignment data yields strong performance on MT-Bench, comparable to LLAMA2-Chat, which employs reinforcement learning from human feedback.
In terms of image classification, MEGALODON exhibits top-1 accuracy improvements over DeiT-B and MEGA on ImageNet-1K. Its performance on auto-regressive language modelling tasks on PG19 surpasses state-of-the-art baselines.
- HCLTech, PTC Launch Pre-Configured PLM Solution for Semiconductor Firms
- IBM, Microsoft Launch Agentic AI Platform With Over 6,000 AI Agents
- NHA Selects EkaCare for AI Voice Scribe in Public Health Facilities
- SoftBank Takes $7 Billion Hit on US AI Data Centre Investments
- Anthropic Seeks Up to $64.4 Bn at $1.4 Tn Valuation With IPO
- IBM Ends H-1B, Green Card Sponsorship for Most Roles in Consulting Division