
NVIDIA recently released a new language model Nemotron-4 15B which trained on a staggering 8 trillion text tokens. It comprises 15 billion parameters, with the ability to perform a variety of tasks in English, coding and multilingual languages.
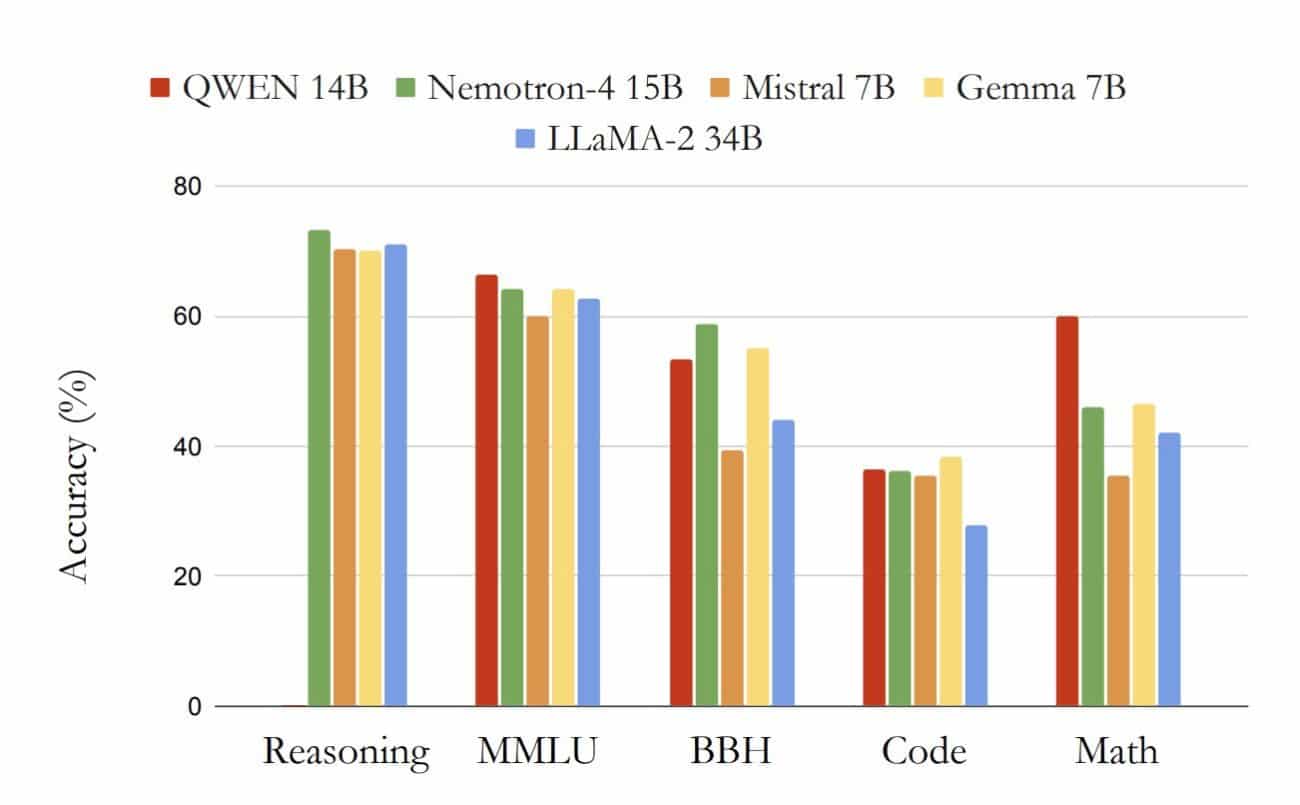
The researchers noted that Nemotron performs better than other similarly-sized, decoder-only transformer models in four out of seven evaluation areas and competes closely with the top models in the remaining domains.
Nemotron matches Qwen-14B at MMLU benchmarks and code but outperforms Gemma 7B, Mistral 7B and LLaMA-2 34B. Nemotron outperforms every other model in reasoning but falls short in maths against Qwen. Interestingly, Qwen is missing in the reasoning.
Nemotron-4 15B outperforms mGPT 13B and XGLM 7.5B in Multilingual Classification. It also does better than Palm-62B and Mistral 7B in generating multilingual text.
NVIDIA'S Latest
Nemotron-4 15B is built using a basic setup that only decodes or generates text, focusing on the order of words. It has 32 layers to process information, a capacity to handle a lot of details at once (6144 units of data), and uses 48 different focus points to understand the context better. Its training utilised a mix of English, multilingual, and source-code data, focusing on quality and diversity to enhance model performance across different languages and programming languages.
The model's training process employed 384 DGX H100 nodes. This extensive training allowed Nemotron-4 15B to achieve high accuracies in a broad range of tasks, including commonsense reasoning, maths, code, and multilingual evaluations, demonstrating its versatility and efficiency.
Nemotron-4 15B's achievements are part of NVIDIA's ongoing efforts in AI and model development.
Key offerings include the Megatron-LM series, optimised for tasks like text summarisation and question answering, and BERT-based models for understanding sentence context.
Although Nemotron-4 15B is not open source their previous iteration, Nemotron-3B, a family of models with 8 billion parameters available on Github. The Nemotron-3 Chat is fine tuned using supervised fine-tuning to produce accurate and informative responses to the prompt.
- OpenAI Introduces ChatGPT Wallet for Agent-Led Payments
- ReNew Pledges ₹80,000 Cr for Green Data Centre to Fuel India’s AI Push
- Mars Opens Hyderabad GCC With Genpact to Expand Digital, AI Capabilities
- Shield AI Opens Bengaluru Engineering Office to Build Defence Autonomy Software
- Adobe, Google Expand AI Partnership Across Creative and Productivity Tools
- Google Launches Gemini 4 Hydrogen for Faster Coding and AI Workflows