
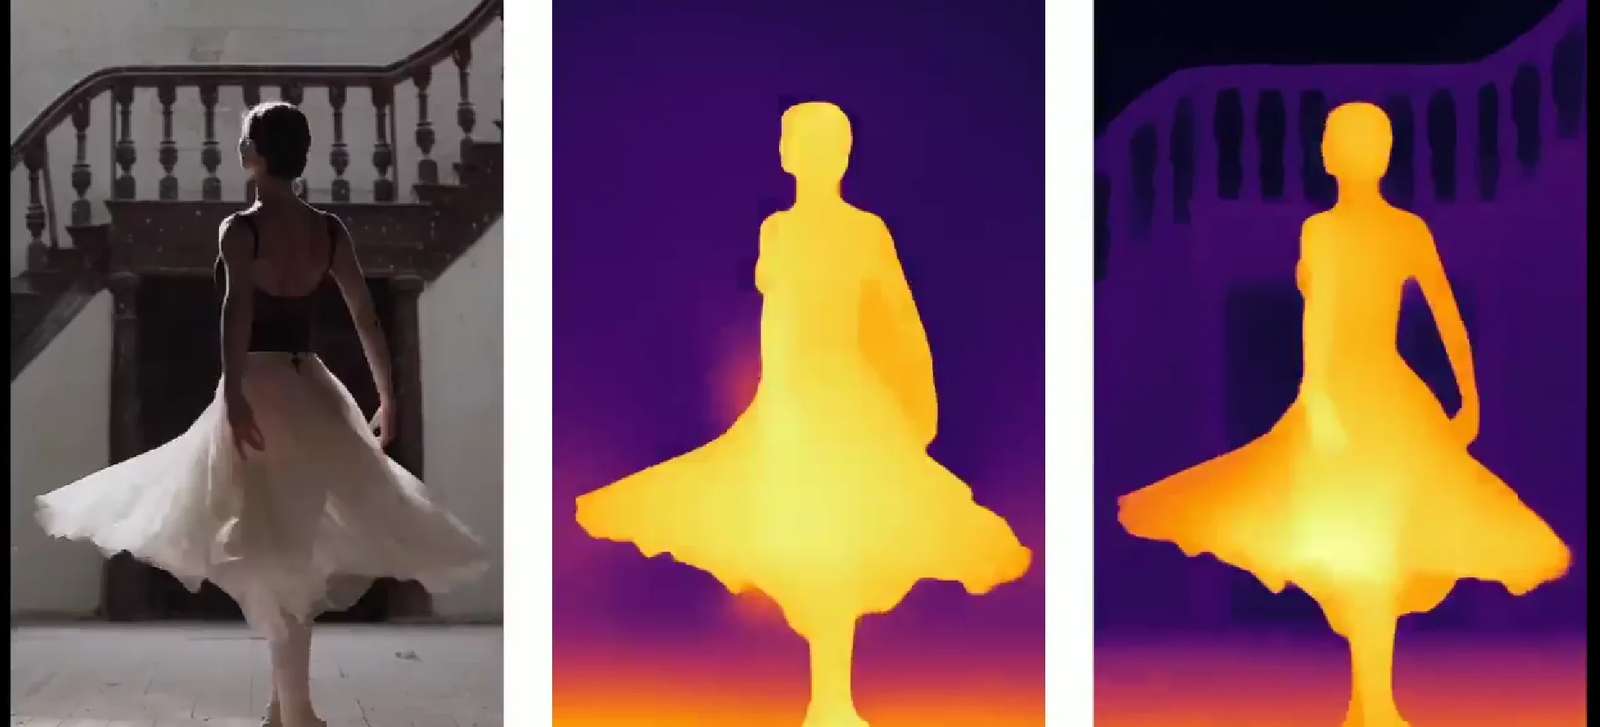
TikTok has unveiled Depth Anything, a groundbreaking development in the realm of Monocular Depth Estimation (MDE). This innovation harnesses the potential of a colossal dataset, comprising 1.5 million labeled images and an astonishing 62 million-plus unlabeled images.
By jointly training on such a massive scale, Depth Anything emerges as a foundational model for MDE with an array of advanced features.
Click here to check out the demo.
Key features of Depth Anything include
- Zero-shot relative depth estimation, surpassing MiDaS v3.1 (BEiTL-512)
- Zero-shot metric depth estimation, outperforming ZoeDepth
- Optimal in-domain fine-tuning and evaluation on NYUv2 and KITTI datasets
Unlike previous approaches, the focus of Depth Anything is not on introducing novel technical modules. Instead, the emphasis lies on constructing a straightforward yet potent foundational model capable of handling diverse images in any scenario.
To achieve this, the dataset is scaled up significantly through the implementation of a data engine designed for collecting and automatically annotating a vast pool of unlabeled data, totaling approximately 62 million images. This extensive dataset expansion proves instrumental in reducing generalisation errors.
Two effective strategies are explored in the process:
- Challenging Optimisation Target: A more demanding optimization target is created using data augmentation tools. This compels the model to actively seek additional visual knowledge, thereby acquiring robust representations.
- Auxiliary Supervision: An auxiliary supervision is developed to ensure the model inherits rich semantic priors from pre-trained encoders. This enhances the model's ability to interpret and understand images.
Extensive evaluation of Depth Anything's zero-shot capabilities involves six public datasets and randomly captured photos, showcasing its impressive generalisation ability.
Furthermore, through fine-tuning with metric depth information from NYUv2 and KITTI, Depth Anything establishes new State-of-the-Art (SOTA) benchmarks. The improved depth model also yields superior results in depth-conditioned ControlNet.
Read: This New AI tool Could Mark the Beginning of the End for TikTok and Instagram Influencers
- Coforge Revenue Rises 54% as AI Engineering and Deal Bookings Gain Momentum
- Tech Mahindra Partners With SpaceXSI to Bring AI Into Software Engineering
- Infosys AI Revenue Rises 29% in Q2, FY27 Growth Guidance Cut
- LTM Launches BlueVerse Industrial AI Lab in Chennai
- Chariot Launches Speech Recognition Model for 10 Indian Languages
- Meta Expects Up To $145 Billion In Capex As AI Investments Expand