
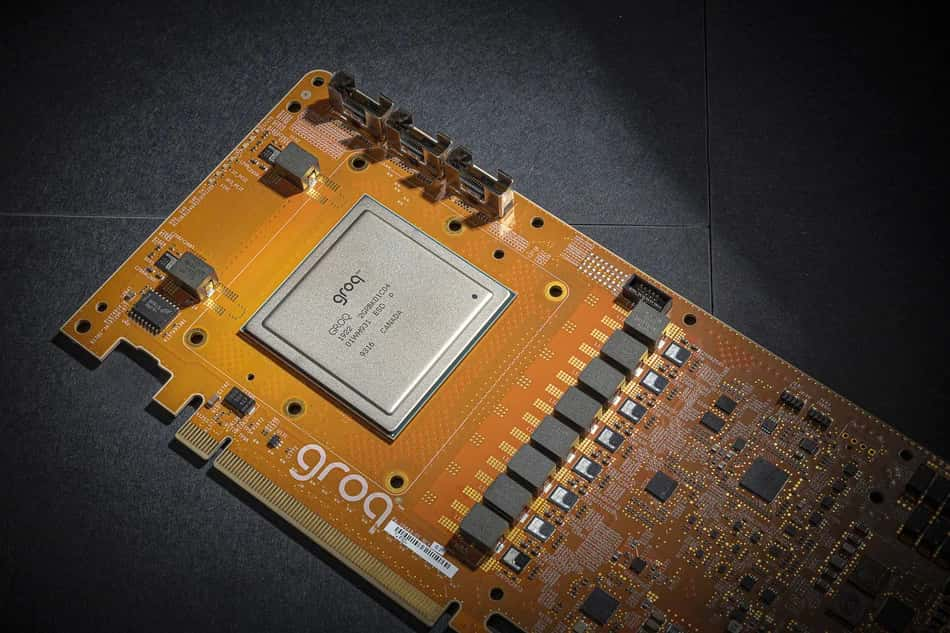
Groq recently introduced the Language Processing Unit (LPU), a new type of end-to-end processing unit system. It offers the fastest inference for computationally intensive applications with a sequential component, such as LLMs.
It has taken the internet by storm with its extremely low latency, serving at an unprecedented speed of almost 500 T/s.
This technology aims to address the limitations of traditional CPUs and GPUs for handling the intensive computational demands of LLMs. It promises faster inference and lower power consumption compared to existing solutions.
Groq's LPU marks a departure from the conventional SIMD (Single Instruction, Multiple Data) model employed by GPUs. Unlike GPUs, which are designed for parallel processing with hundreds of cores primarily for graphics rendering, LPUs are architected to deliver deterministic performance for AI computations.
Energy efficiency is another noteworthy advantage of LPUs over GPUs. By reducing the overhead associated with managing multiple threads and avoiding core underutilisation, LPUs can deliver more computations per watt, positioning them as a greener alternative.
Groq's LPU has the potential to improve the performance and affordability of various LLM-based applications, including chatbot interactions, personalised content generation, and machine translation. They could act as an alternative to NVIDIA GPUs especially since A100s and H100s are in such high demand.
Groq was founded in 2016 by its chief Jonathan Ross. He initially began what became Google's TPU (Tensor Processing Unit) project as a 20% project and later joined Google X's Rapid Eval Team before founding Groq.
- Gnani AI Launches Prisma v3.0 Speech Recognition Model for 10 Languages
- Venttup Raises $3 Million To Expand Precision Manufacturing
- Articul8 Launches Bivia To Help Enterprise AI Agents Make Decisions
- NVIDIA Launches Open-Weight Transcription Model for 40 Languages
- Sarvam AI Rolls Out Indus Cowork to 2,500 Maharashtra Govt Officials
- Coforge Introduces Autonomous Software Factory to Coordinate AI Agents