
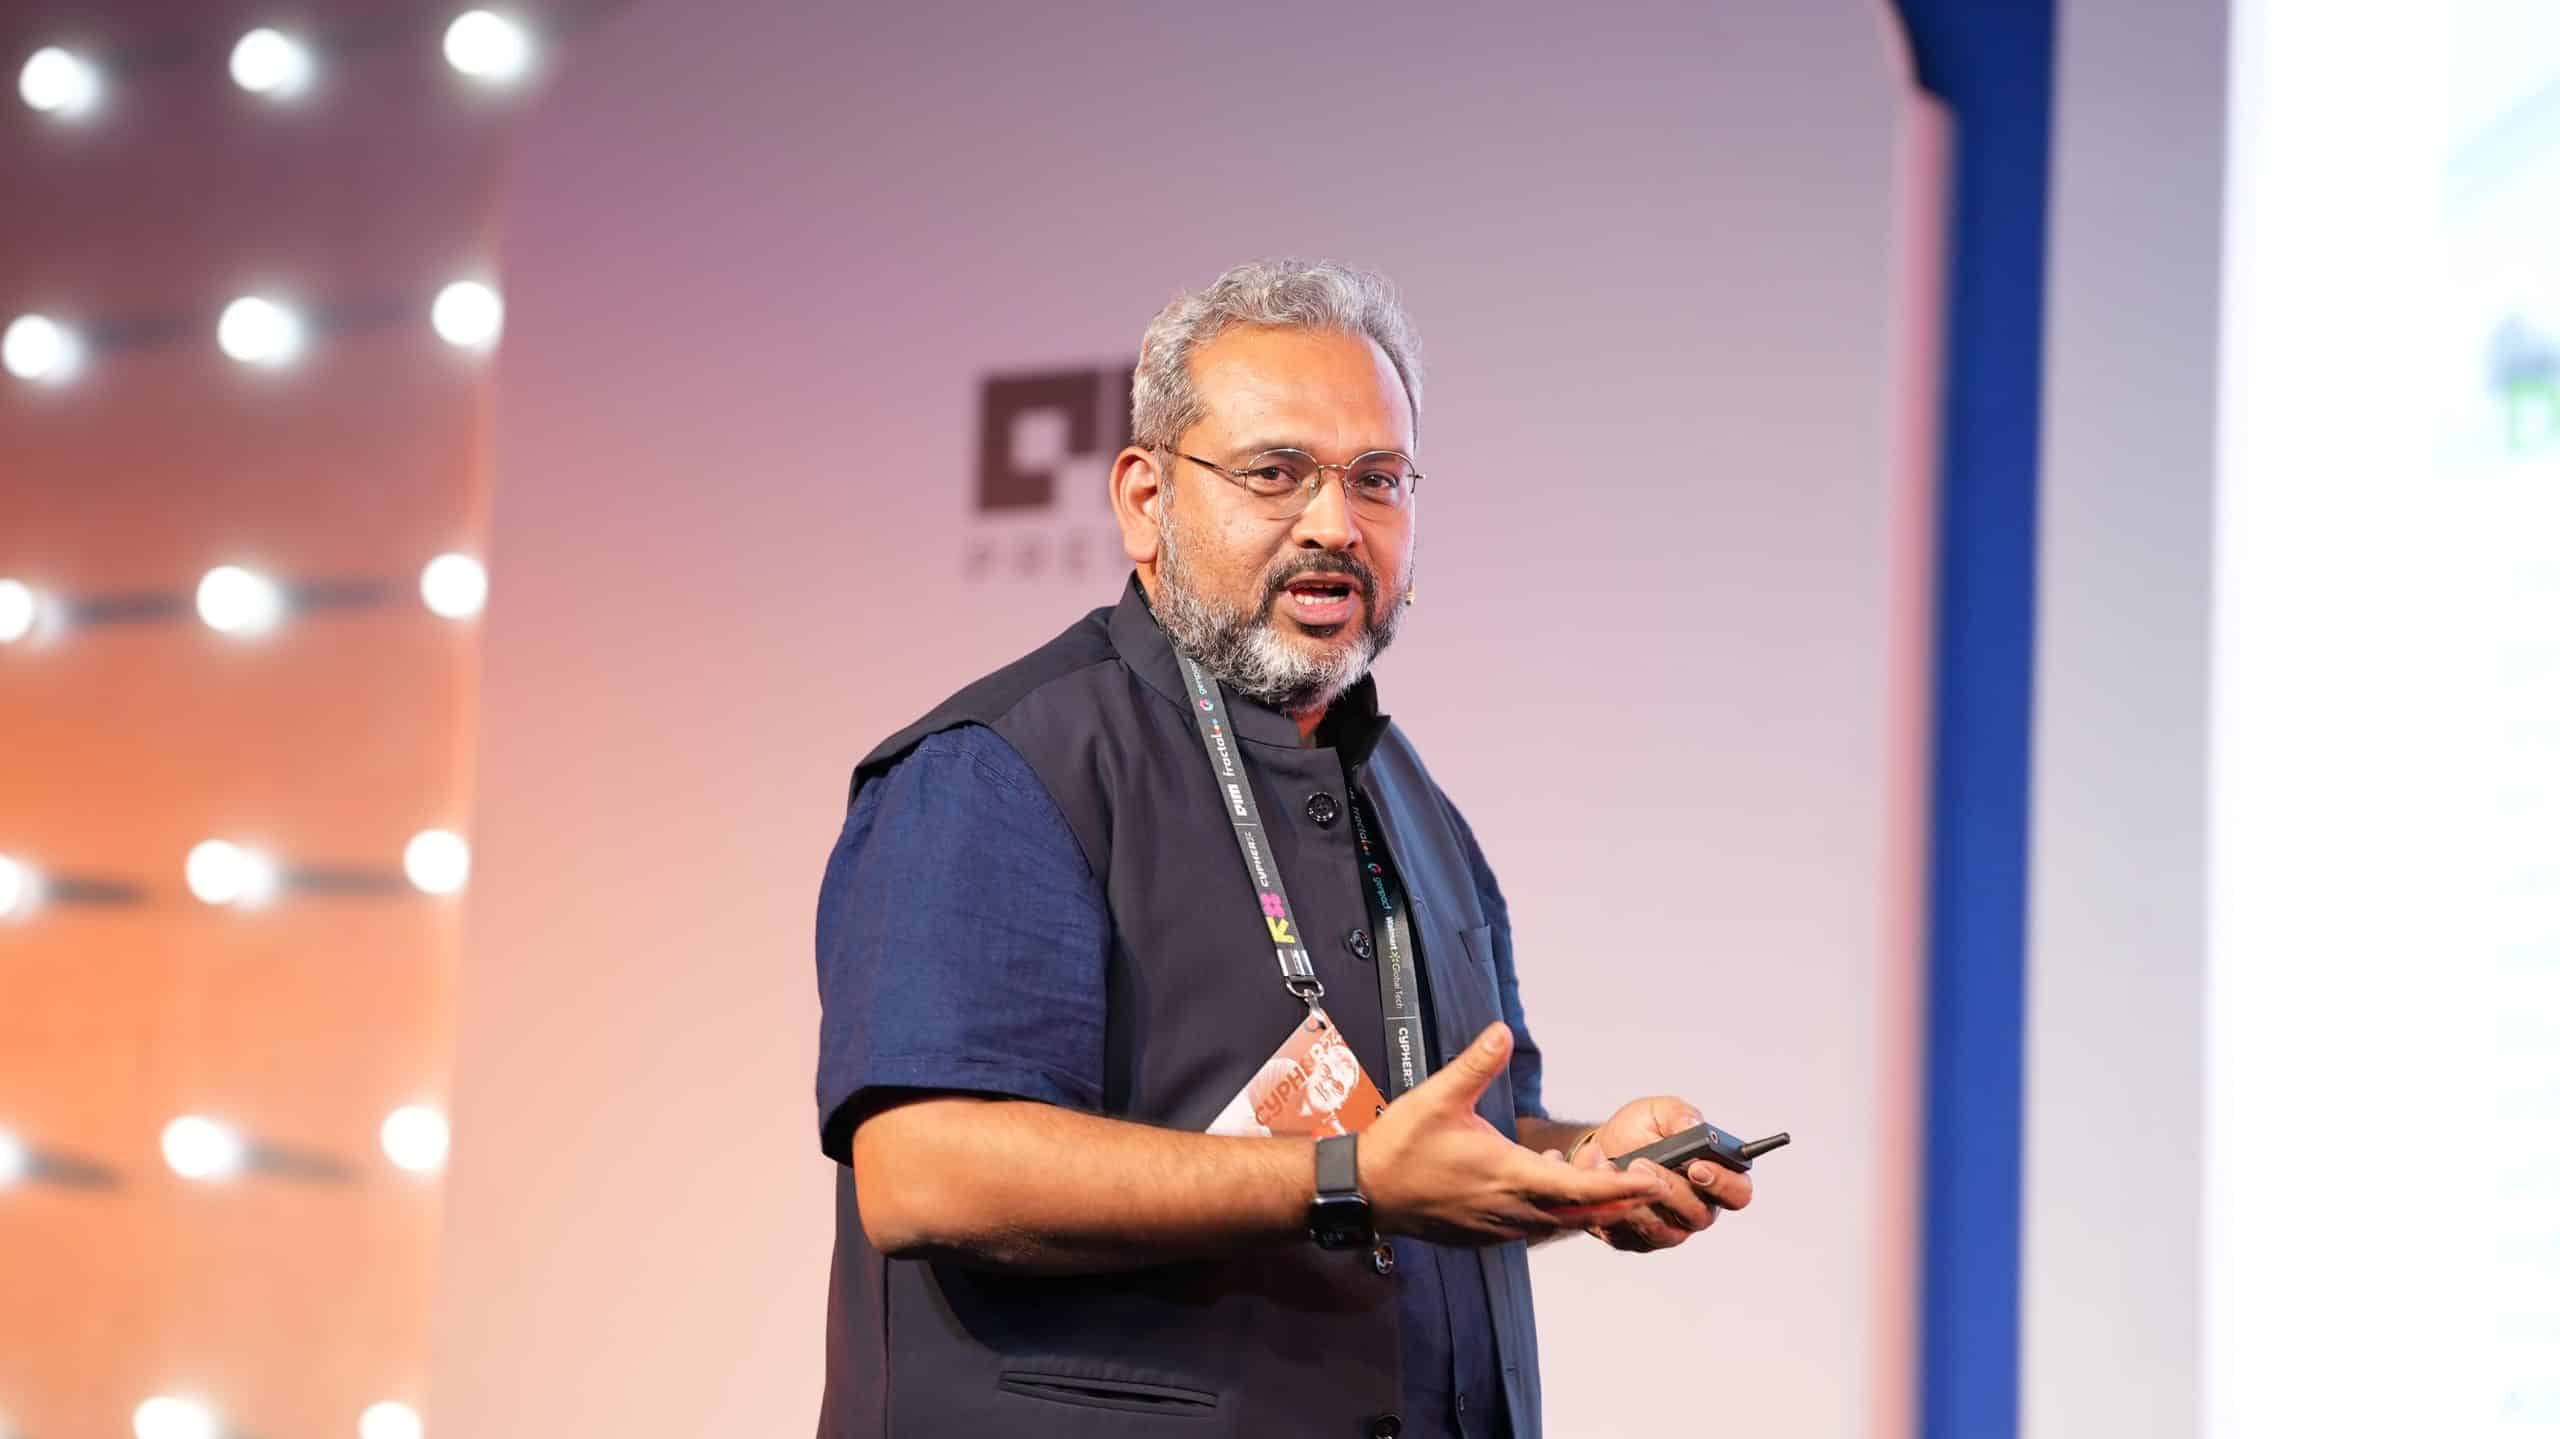
Nikhil Malhotra, chief innovation officer at Tech Mahindra, announced at Cypher 2024, India’s biggest AI conference, that the company will launch Project Indus 2 within a couple of months.
“NVIDIA is a great partner, and you should all look forward to next month when we plan to launch Project Indus 2. We’re going to make it state-of-the-art in terms of Hindi and its various dialects, using a modern, open-source approach. I developed this model to raise awareness and show the world that India has the capability to achieve this,” said Malhotra.
Most recently, Malhotra also met NVIDIA chief Jensen Huang and the team at NVIDIA’s offices to discuss sovereign LLMs.
Tech Mahindra launched Project Indus earlier this June through its R&D arm, Makers Lab. This AI model is built to converse in multiple Indic languages and dialects, starting with Hindi and its 37+ variations.
The model has 1.2 billion parameters and was trained on 22 billion tokens. It is built on GPT-2 and designed to handle the complexities of the Hindi language.
Furthermore, Malhotra shared that when they began working on Project Indus, the goal was not to focus on any specific language but to address various dialects. “India is home to 24 mother tongues and 1,645 dialects. Officially, the country speaks 19,200 dialects, some of which have become extinct or are endangered,” he said.
“It's not just about Hindi. It’s going to include variations of Hindi like Dogri, as well as languages such as Pancha Pargania and Magahi,” he added.
He said that Project Indus can work on AI PCs locally without the requirement of GPUs. “The model is benchmarked on Intel Xeon servers, not GPUs. Since it’s based on Intel Xeon, our model runs on these AI PCs.”
Malhotra revealed that they are not in the race of building 175 billion parameter models. “We are not in a race of saying you're building 170 billion parameters, because most of my research over the last 20 years in language says that after 3 billion to 4 billion parameters, the model knows the language,” he explained.
Era of Sovereign LLMs
Malhotra said that it's not just India that is working on sovereign LLMs. “There are countries in Southeast Asia that have now taken the lead. All of them want to build large language models for their country, using their data hosted within the country. These models will reflect their culture, be aware of biases within that culture, and align with their country’s vision,” he said.
Moreover, Malhotra shared that Tech Mahindra has built the first sovereign LLM for Indonesia, called Garuda. “This is a big model. It’s about an eight to nine billion parameter model. It's actually trained on the entire Nvidia stack of Nemo,” said Malhotra.
Earlier this year, Tech Mahindra partnered with Indosat Ooredoo Hutchison to Build Garuda, an LLM for Bahasa Indonesia and its Dialects.
“The era of sovereign LLMs has just begun,” he said, adding that soon many countries, including Malaysia, Australia, and New Zealand, will be building indigenous LLMs that understand local languages and not just English.
What’s Next?
Malhotra said that one of the things he wants to do with AI, and one of his research goals, is to explore how AI can become less compute-intensive.
Furthermore, he also unveiled his innovative concept for AI development, which he calls the ‘min-max regret model.’ This approach shifts away from traditional reward models and aims to empower AI to "dream" about its capabilities and understand its existence in a more profound way.
Malhotra explained that this dreaming model allows AI to contemplate its own questions and aspirations. “Can you dream about yourself? Once you develop your dream, now come back to life and start with the life that you have,” he said, highlighting the physical aspect of existence and how it relates to AI.
Drawing a parallel between human cognition and AI functionality, Malhotra said that just as humans subconsciously store information in the hippocampus, AI systems will use their ‘memory’ to inform decision-making processes.
“A lot of the data that you collect to do a lot of your information still resides at the back of the hippocampus, which is a memory. And as a result, you pull out that memory when you have to cycle,” he elaborated, likening it to learning to ride a bike—an instinctual skill honed from childhood that remains stored in our subconscious.

Your reaction
Discussion
What's your take on this story?
No comments yet — be the first to share your view.