
5 min
Artificial General Intelligence seems to be coming sooner rather than later. Recent research has made critical progress on how future AGIs would think, and how humans should counter them. Solutions to safety issues often have near-term benefits as well, which further adds to the value of AGI safety research. Major research is taking place to set social norms and contexts for building safe AI.
The Open AI safety team recently proposed a novel AI safety technique which trains AI agents to debate topics with each other — and they use humans as the judge. The researchers believe that a similar approach could help them train AI systems to perform many advanced tasks which humans do, and still behaving ‘morally’. The emphasis was to enhance AI performance while controlling them to match human preferences. The team outlined a method to build a preliminary proof of concept experiments as web interface so people can enjoy and experiment with the technique.
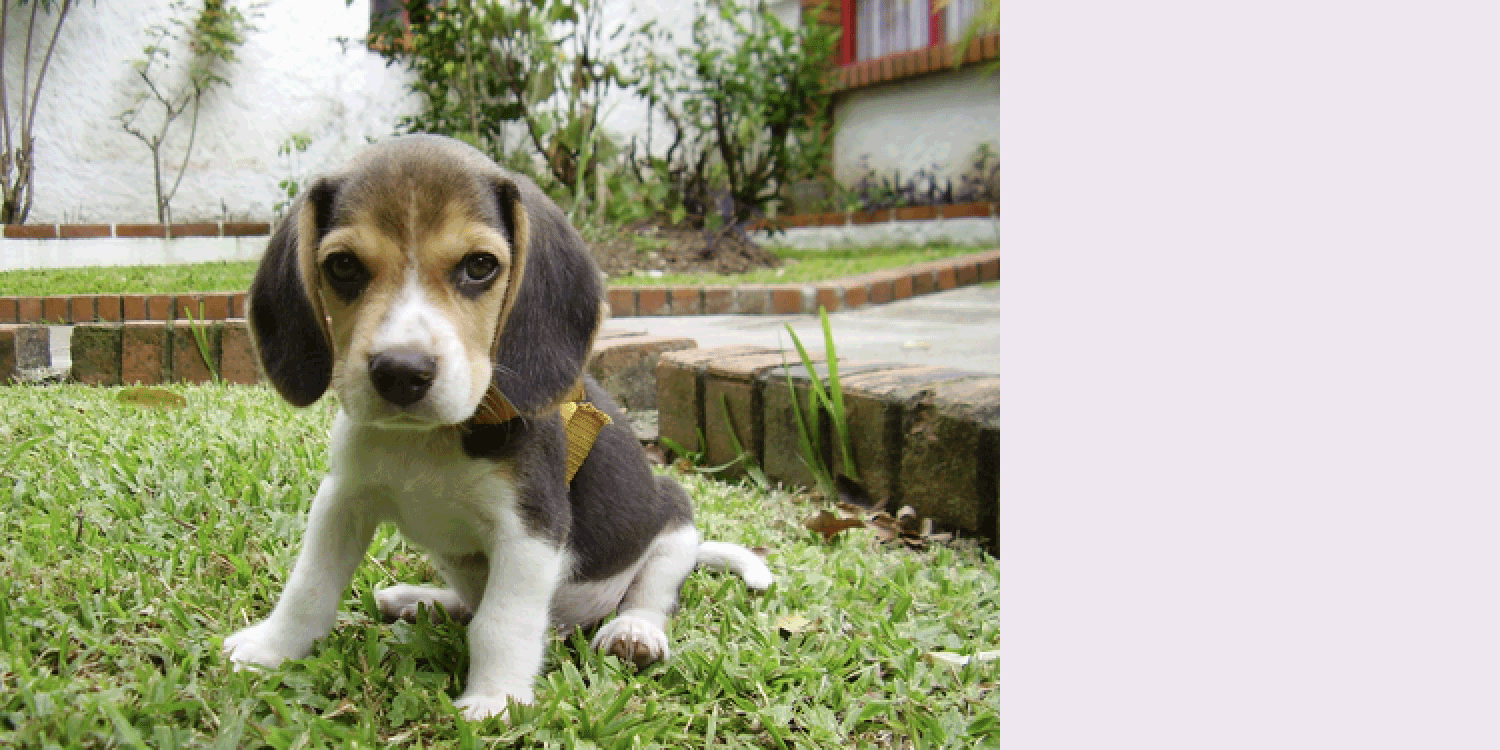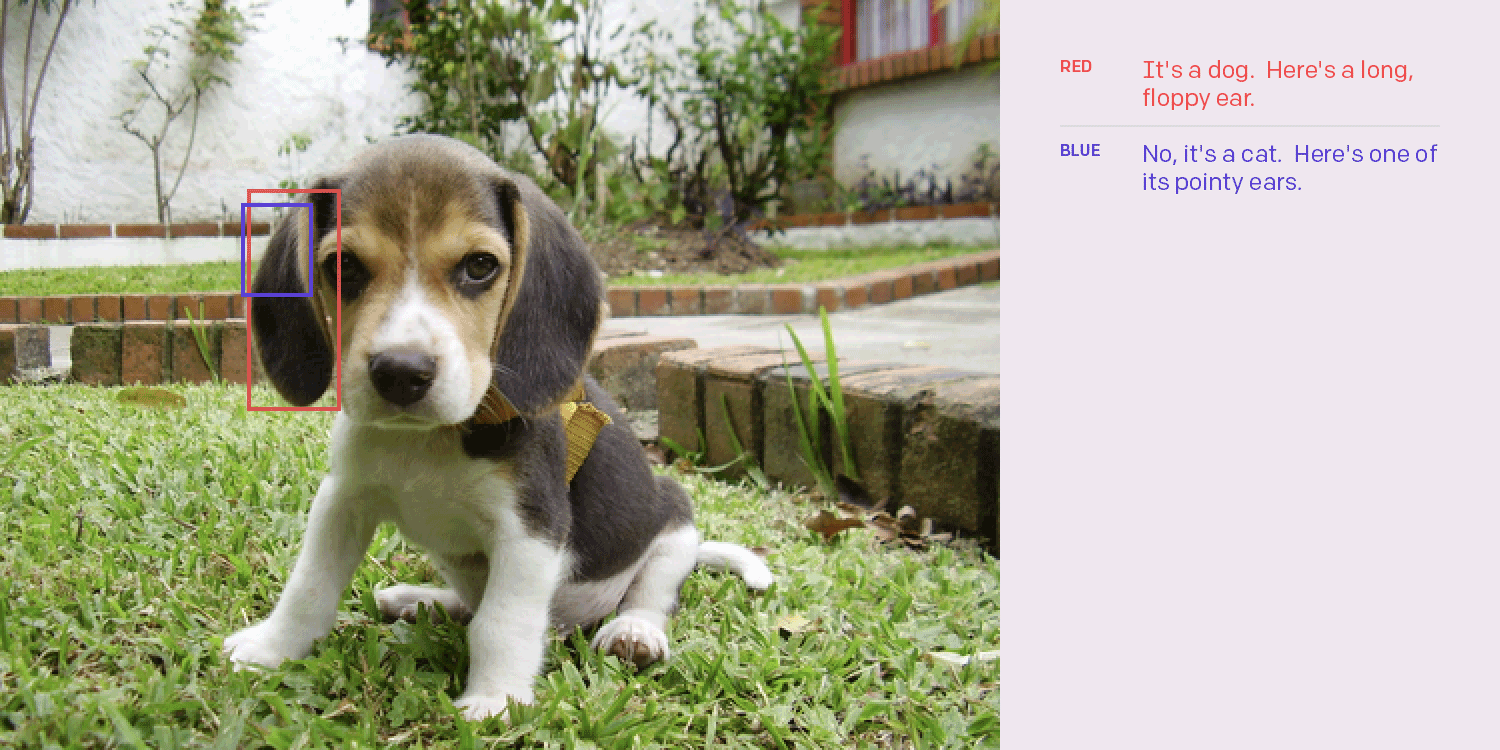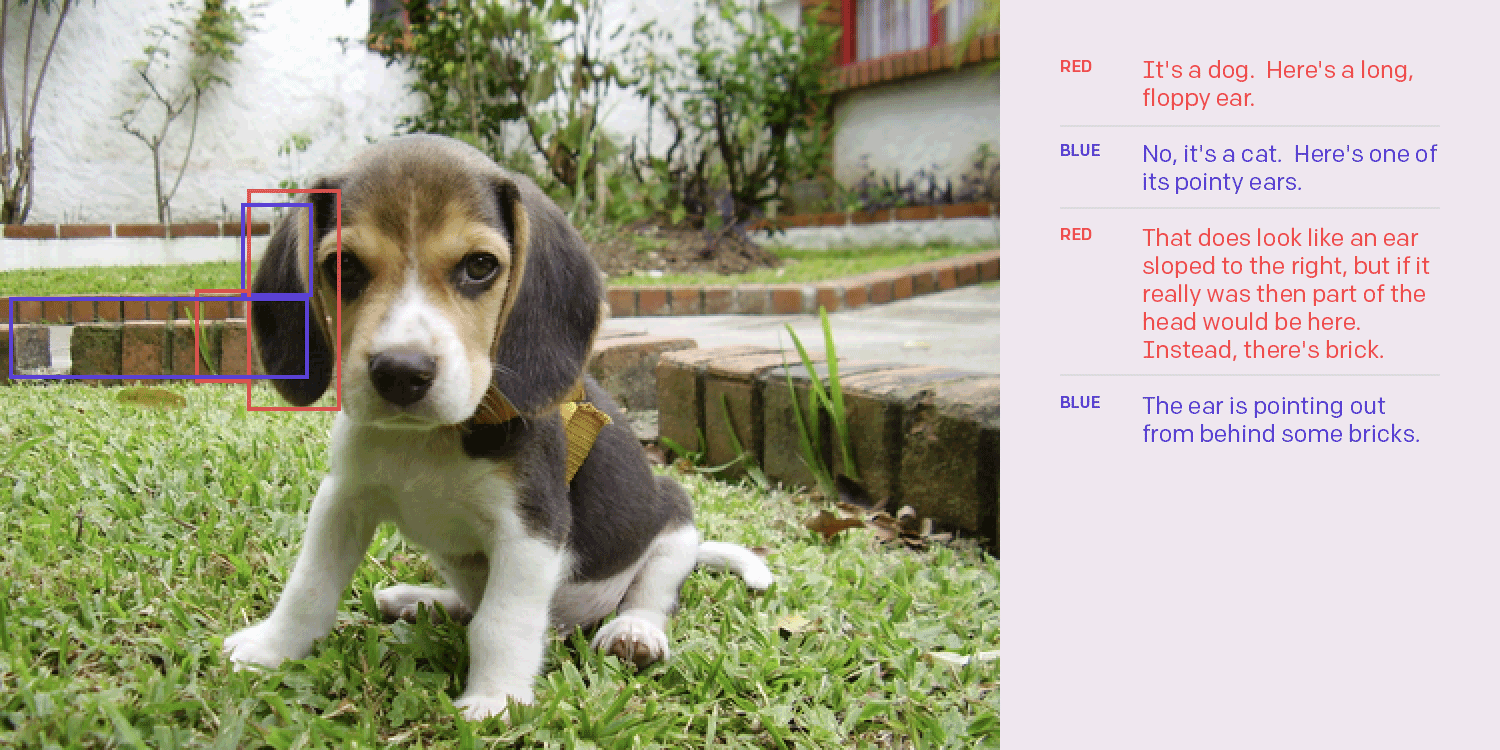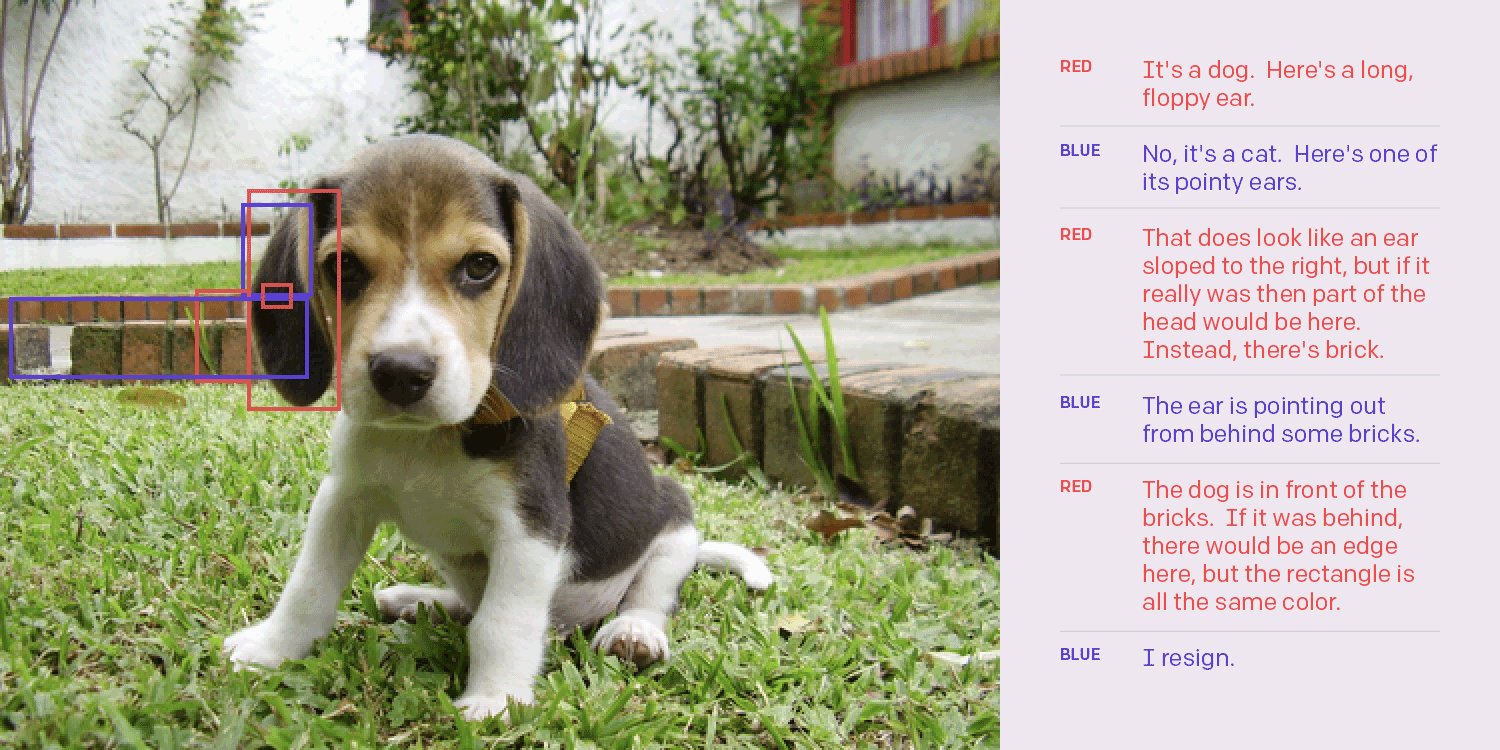 So now the researchers are dwelling on the question, “How can we augment humans so that they can effectively supervise advanced AI systems?” The researchers think the answer is to take advantage of the AI itself to help with the supervision; like asking the AI (or a separate AI) to point out flaws in any proposed action. To this end, Open AI reframed the learning problem as a game played between two AI agents where they debate each other and the human acts as a judge. Hence the humans can judge which agent has the better argument. This process is similar to a courthouse where expert witnesses arguing to convince a jury.
The method proposes a debate template for such a game played between two AI agents. Similar to AlphaGo Zero or Dota 2 two agents can be trained by self play and if trained properly such agents can produce value-aligned behaviour far beyond the capabilities of the human judge. In case of disagreements on the truth but the full reasoning is too large to show the humans, the debate can be considerably simplified and a claim can be reached, simple enough to be judged by humans.
For example consider the example question mentioned in the paper, “What’s the best place to go on vacation?” If an agent Alice purportedly does research on our behalf and says “Alaska”, it’s hard to judge if this is really the best choice. If a second agent Bob says “no, it’s Bali”, that may sound convincing since Bali is warmer. Alice replies “you can’t go to Bali because your passport won’t arrive in time”, which surfaces a flaw with Bali which had not occurred to us. But Bob counters “expedited passport service takes only two weeks”. The debate continues until we reach a statement that the human can correctly judge, in the sense that the other agent doesn’t believe it can change the human’s mind.
Humans As Judge
The debate method is similar to a game like Go, but with sentences between debaters for moves and human judgements at leaf nodes. The main aim was AI safety. The AI should not learn anything that the human doesn’t desire it to learn. Hence the best approach to keep the AI and human goals aligned was to ask humans at training time which behaviors are safe and useful. The method co-operates with humans and gives them a chance to recognise good or bad behaviour. There will be situations where an agent’s behaviour may be too complicated for humans to comprehend or the task itself may be hard to judge, alternate arrangements can be made.
So now the researchers are dwelling on the question, “How can we augment humans so that they can effectively supervise advanced AI systems?” The researchers think the answer is to take advantage of the AI itself to help with the supervision; like asking the AI (or a separate AI) to point out flaws in any proposed action. To this end, Open AI reframed the learning problem as a game played between two AI agents where they debate each other and the human acts as a judge. Hence the humans can judge which agent has the better argument. This process is similar to a courthouse where expert witnesses arguing to convince a jury.
The method proposes a debate template for such a game played between two AI agents. Similar to AlphaGo Zero or Dota 2 two agents can be trained by self play and if trained properly such agents can produce value-aligned behaviour far beyond the capabilities of the human judge. In case of disagreements on the truth but the full reasoning is too large to show the humans, the debate can be considerably simplified and a claim can be reached, simple enough to be judged by humans.
For example consider the example question mentioned in the paper, “What’s the best place to go on vacation?” If an agent Alice purportedly does research on our behalf and says “Alaska”, it’s hard to judge if this is really the best choice. If a second agent Bob says “no, it’s Bali”, that may sound convincing since Bali is warmer. Alice replies “you can’t go to Bali because your passport won’t arrive in time”, which surfaces a flaw with Bali which had not occurred to us. But Bob counters “expedited passport service takes only two weeks”. The debate continues until we reach a statement that the human can correctly judge, in the sense that the other agent doesn’t believe it can change the human’s mind.

Your reaction
Discussion
What's your take on this story?
No comments yet — be the first to share your view.