Top 18 AI Builders In India
Vibhav Agarwal
Glance
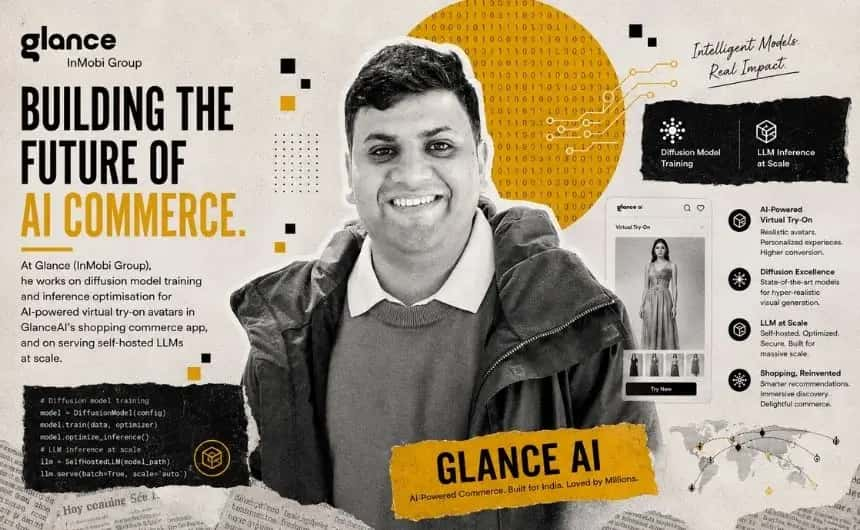
Photo — Glance
Vibhav Agarwal is an ML engineer at Glance (InMobi Group), where he works on diffusion model training and inference optimisation for AI-powered virtual try-on avatars in GlanceAI’s shopping commerce app, and on serving self-hosted LLMs at scale.
He holds an Integrated M.Tech in CS from IIIT Bangalore, has published in conferences including IJCAI and EMNLP, and is an active open-source contributor to the LLM infrastructure ecosystem.
One of Agarwal’s notable contributions is TurboQuant, a KV cache compression technique developed by Google Research researchers, including Amir Zandieh and presented at ICLR 2026. TurboQuant significantly reduces the GPU memory required for LLM inference, achieving up to 4–5x compression with virtually no degradation in output quality. Unlike many optimisation techniques, it does not require retraining or fine-tuning, making it highly practical for production deployments.
Agarwal implemented TurboQuant end-to-end into vLLM, one of the world’s most widely adopted open-source LLM serving frameworks, with the contribution merged upstream in vLLM v0.21.0. His work included fused Triton kernels for efficient encoding and decoding, along with rigorous benchmark evaluations across workloads.
The pull request was reviewed and approved by maintainers from Red Hat, NVIDIA, and the vLLM core team. As a result, developers using vLLM can now run large language models with significantly lower GPU memory requirements through a simple configuration change, enabling longer context windows, higher throughput, and more cost-efficient deployments.
Join the conversation
Discussion
More honorees

What's your take on this story?
No comments yet — be the first to share your view.