Key takeaways
- TikTok launches Depth Anything, a foundational model for Monocular Depth Estimation using 62 million images.
- Achieve advanced depth estimation capabilities with zero-shot performance surpassing existing models like MiDaS and ZoeDepth.
- Utilize a data engine for collecting and annotating vast datasets, enhancing model generalization.
- Focus on simplicity and effectiveness rather than introducing new technical modules for image processing.
- Implement challenging optimization targets and auxiliary supervision to strengthen model representations and semantic understanding.
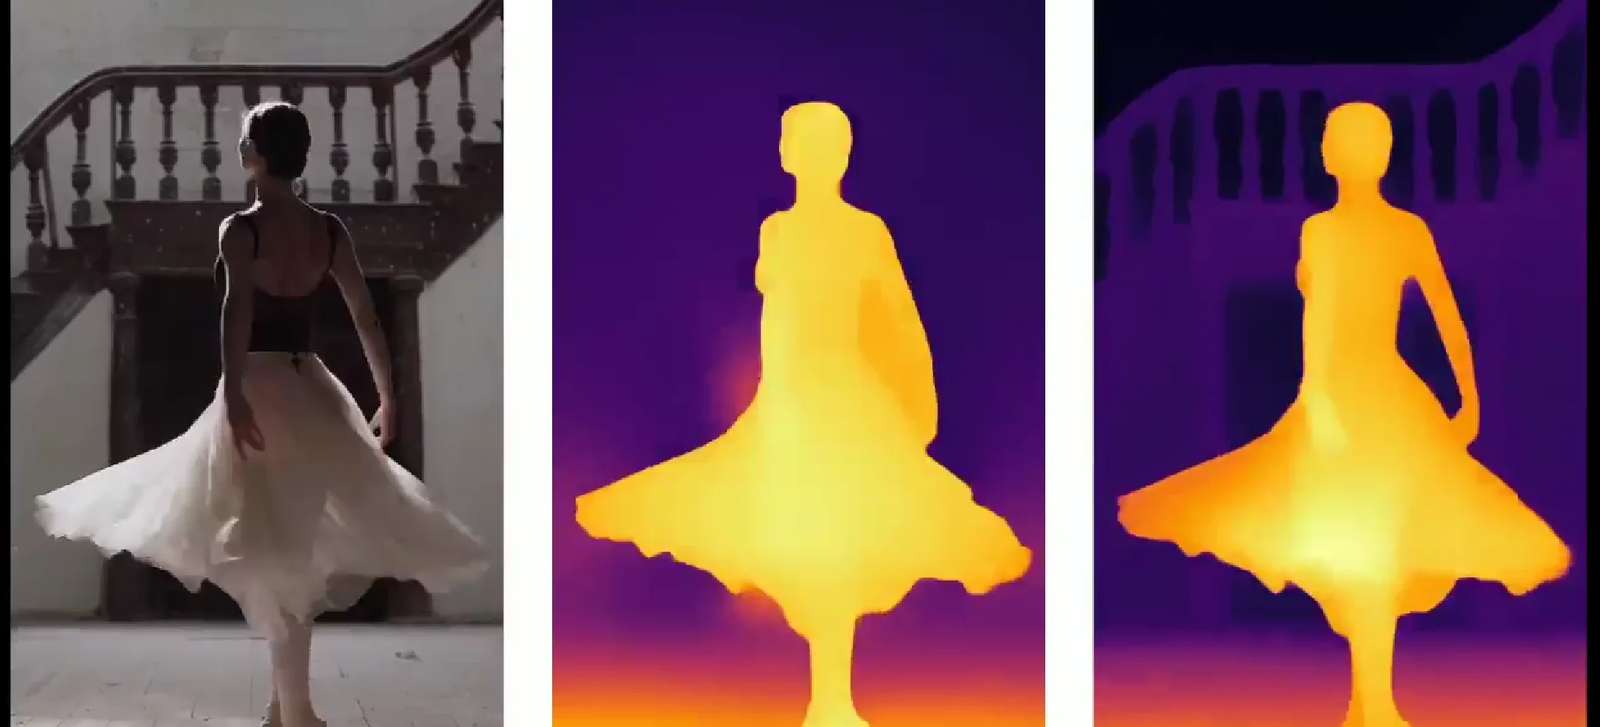
TikTok has unveiled Depth Anything, a groundbreaking development in the realm of Monocular Depth Estimation (MDE). This innovation harnesses the potential of a colossal dataset, comprising 1.5 million labeled images and an astonishing 62 million-plus unlabeled images.
By jointly training on such a massive scale, Depth Anything emerges as a foundational model for MDE with an array of advanced features.
Click here to check out the demo.
Key features of Depth Anything include
- Zero-shot relative depth estimation, surpassing MiDaS v3.1 (BEiTL-512)
- Zero-shot metric depth estimation, outperforming ZoeDepth
- Optimal in-domain fine-tuning and evaluation on NYUv2 and KITTI datasets
Unlike previous approaches, the focus of Depth Anything is not on introducing novel technical modules. Instead, the emphasis lies on constructing a straightforward yet potent foundational model capable of handling diverse images in any scenario.
To achieve this, the dataset is scaled up significantly through the implementation of a data engine designed for collecting and automatically annotating a vast pool of unlabeled data, totaling approximately 62 million images. This extensive dataset expansion proves instrumental in reducing generalisation errors.
Two effective strategies are explored in the process:
- Challenging Optimisation Target: A more demanding optimization target is created using data augmentation tools. This compels the model to actively seek additional visual knowledge, thereby acquiring robust representations.
- Auxiliary Supervision: An auxiliary supervision is developed to ensure the model inherits rich semantic priors from pre-trained encoders. This enhances the model's ability to interpret and understand images.
Extensive evaluation of Depth Anything's zero-shot capabilities involves six public datasets and randomly captured photos, showcasing its impressive generalisation ability.
Furthermore, through fine-tuning with metric depth information from NYUv2 and KITTI, Depth Anything establishes new State-of-the-Art (SOTA) benchmarks. The improved depth model also yields superior results in depth-conditioned ControlNet.
Read: This New AI tool Could Mark the Beginning of the End for TikTok and Instagram Influencers
Spotted an error? Tell our editors. Read our editorial standards and corrections.