
At a time when AI prototypes can be built in hours with a few prompts and a coding assistant, the harder question for enterprises is no longer whether they can build AI, but whether they can trust it in production.
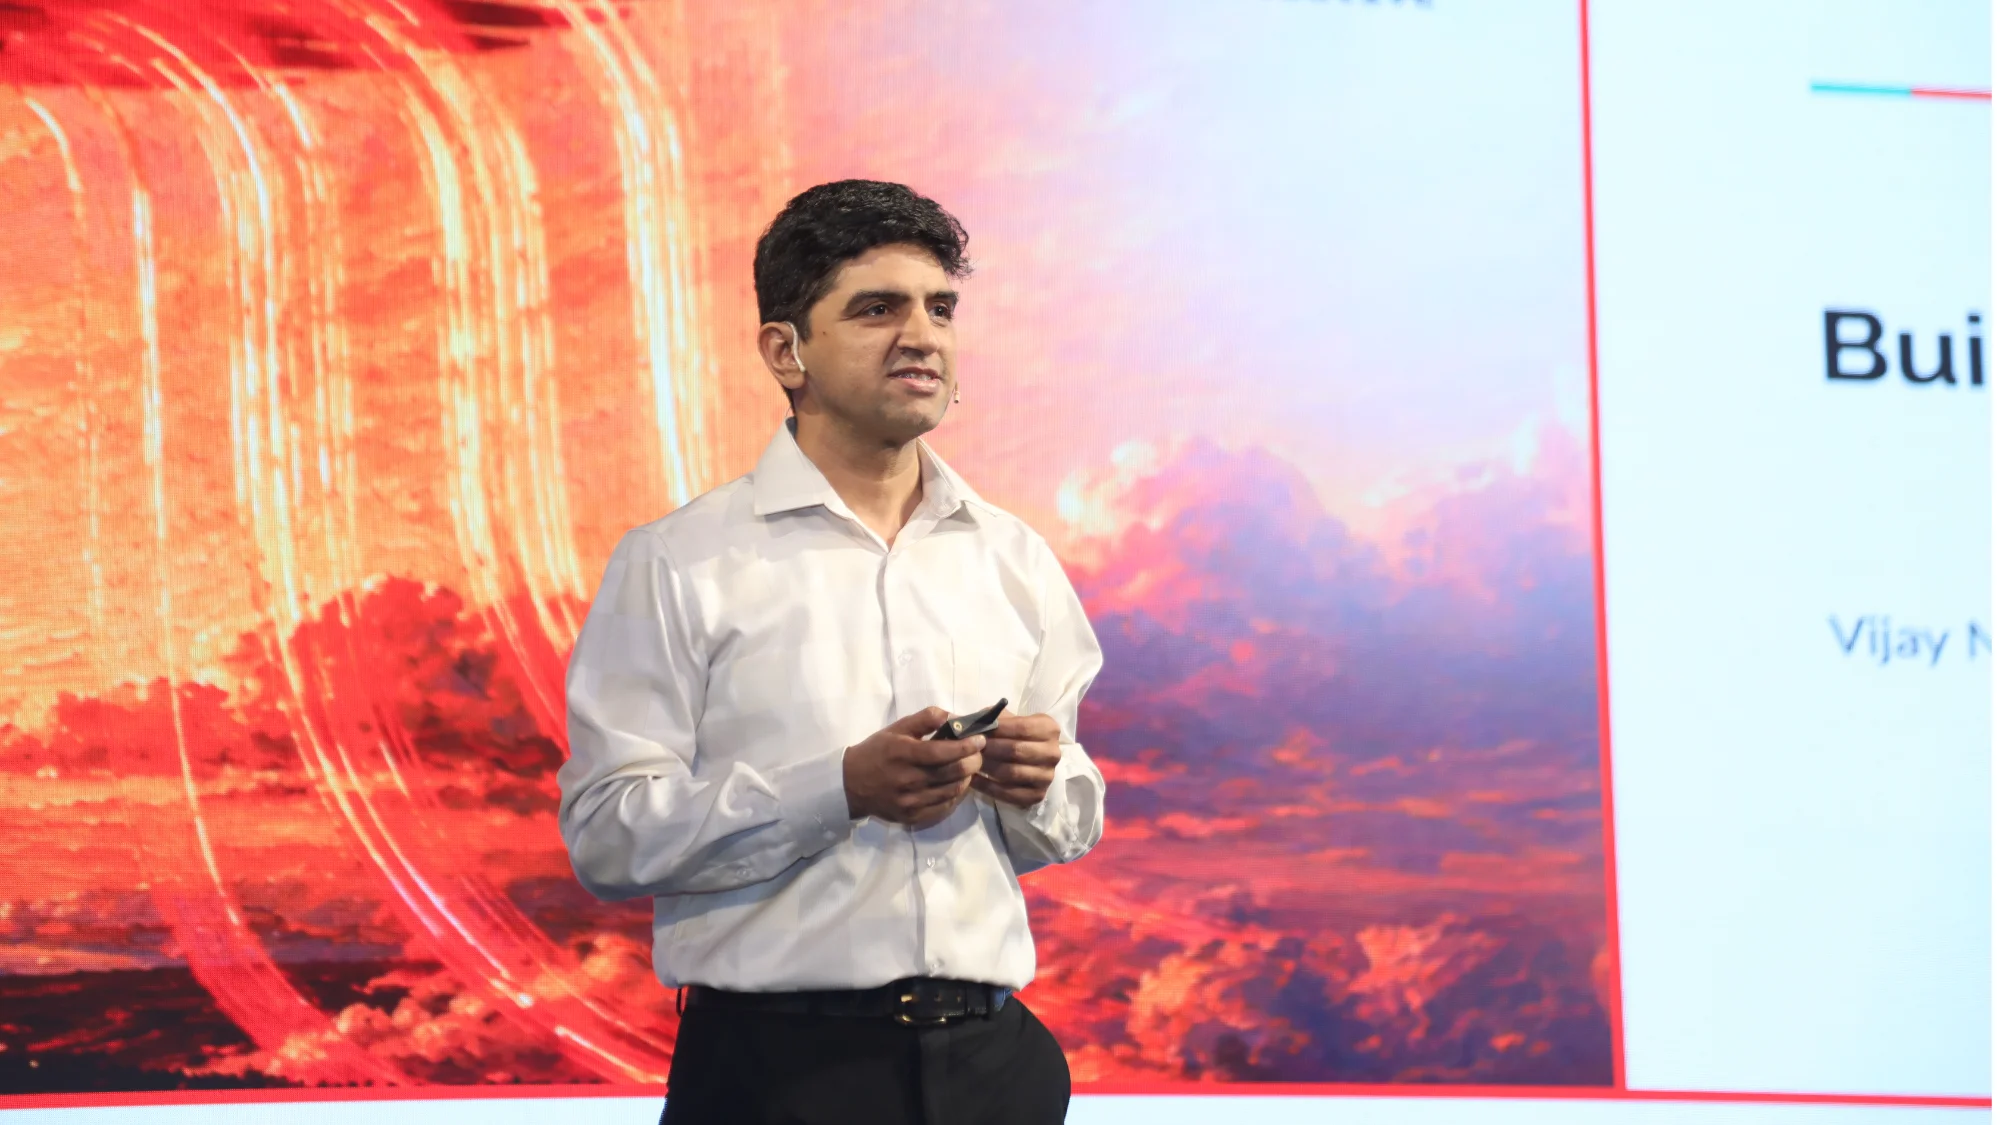
Speaking at Data Engineering Summit 2026, Vijay Narayanan, Head of Innovation and AI at Kotak Mahindra Bank, lays out what separates a flashy demo from an enterprise-grade AI system that customers, employees, and businesses can reliably depend on every day.
“Prototypes are very easy to create now thanks to AI and generative AI in particular,” Narayanan says.
He further says that generative AI has significantly eased the process of building and modifying software. It can also generate images and videos, create Kubernetes manifests, and automate workflow definitions. According to him, these capabilities are dramatically accelerating prototyping across a wide range of enterprise use cases.
The Real Challenge Starts After Demo
Narayanan argues that the industry is currently underestimating the engineering discipline required to deploy AI responsibly at scale.
Moving from experimentation to production brings new concerns, such as who has access, how reliability is assessed, how regressions are identified, and how risks are handled.
According to Narayanan, enterprises often discover these challenges only after an AI system begins failing in real-world environments.
Unlike traditional software, AI systems behave probabilistically, making debugging and validation significantly harder. Narayanan stresses that organisations need to define clear acceptance standards early and build those expectations directly into automated testing frameworks.
Identity and Access Control Cannot Be an Afterthought
Narayanan highlights that identity and access management (IAM) is foundational for enterprise AI.
He warns that many organisations are building AI agents on top of enterprise data without fully integrating existing access-control systems into those AI workflows.
He explains this with the example of an AI agent handling highly sensitive information. Narayanan says that even if the original documents are protected within enterprise systems, an AI assistant can still inadvertently expose sensitive data if access controls are not properly enforced at the agent layer.
“You have to make sure that the person who is calling that AI agent actually understands the identity, understands the access-control mechanism, and understands the user restrictions,” he says.
Narayanan adds that enterprises cannot afford to treat IAM as an afterthought. Without deep integration between AI systems and enterprise identity stacks, companies risk privilege escalation, unauthorised access, and the absence of audit trails.
Prompts Should Be Treated Like Code
Narayanan pushes back against the idea that prompts are merely inputs rather than software artefacts.
“English is the new programming language,” he says. “But that doesn’t mean we shouldn’t treat English as code.”
In his view, prompts require the same operational rigour as traditional software components. That means version control, audit trails, traceability, and governance processes similar to those used in modern software engineering.
The same philosophy extends to datasets, evaluation benchmarks, and AI APIs.
AI APIs Need Enterprise-Grade Reliability
Narayanan emphasises that AI agents should not be treated differently from other mission-critical enterprise systems when it comes to operational reliability.
He advocates using structured API specifications such as OpenAPI alongside clearly defined service-level agreements (SLAs) for latency, throughput, and availability.
Narayanan says machine-readable specifications can help enterprises automatically generate observability artefacts, alerting rules, and operational thresholds.
“Just like any other APIs, you could get denial-of-service attacks, broken object authorisation risks, or lack of multi-tenancy,” he warns.
Operational risks become even more complex when AI agents interact with other agents in multi-agent workflows.
Enterprises Need Controlled Rollouts
Narayanan also cautions organisations against rolling out AI capabilities to all users simultaneously without monitoring and safeguards.
“You can just roll it out in a big-bang fashion and hope and pray that nothing goes wrong,” he jokes. “That’s a very good strategy to upset a lot of people really, really quickly.”
Instead, he recommends feature toggles, phased deployments, calibrated rollouts, and telemetry-driven monitoring.
According to him, observability must be built into AI systems from the start rather than added later.
“You want to monitor behaviour, operational risks, and then expand the rollout of that AI capability,” he says. This also includes investing in API and AI gateways that handle rate limits, token caching, usage controls, and budgetary guardrails.
Don’t Blindly Trust AI-Generated Code
While Narayanan acknowledges the productivity gains from AI-assisted software development, he warns against assuming generated code is production-ready by default.
“Just like humans can generate code with vulnerabilities, AI can do it, except much faster,” he quips.
He adds that overreliance on AI-generated code could also weaken engineering fundamentals over time.“We are fast forgetting how to code,” he remarks.
For Narayanan, the path to enterprise-grade AI is ultimately less about impressive demos and more about discipline, governance, reliability, and operational maturity.
The companies that succeed with AI, he suggests, will not necessarily be the ones building the flashiest prototypes, but the ones capable of turning those prototypes into systems enterprises can safely trust at scale.

Your reaction