
While speaking to AIM, Harkirat Behl, one of the creators of the Phi model, said that his team was working on the next version of Phi-2 and making it more capable. “Phi-1.5 started showing great coding capabilities, Phi-2 was code with common sense abilities, and the next one would be even more capable,” he said.
Microsoft has now unveiled Phi-3-Mini, a 3.8 billion parameter language model trained on an extensive dataset of 3.3 trillion tokens. Despite its compact size, Phi-3-Mini boasts performance levels that rival larger models such as Mixtral 8x7B and GPT-3.5.
“One of the things that makes Phi-2 better than Meta’s Llama 2 7B and other models is that its 2.7 billion parameter size is very well suited for fitting on a phone,” said Behl. Phi-3 makes it even better now.
For instance, Phi-3-Mini achieves 69% on the MMLU benchmark and 8.38 on the MT-bench, making it suitable for deployment on mobile phones.
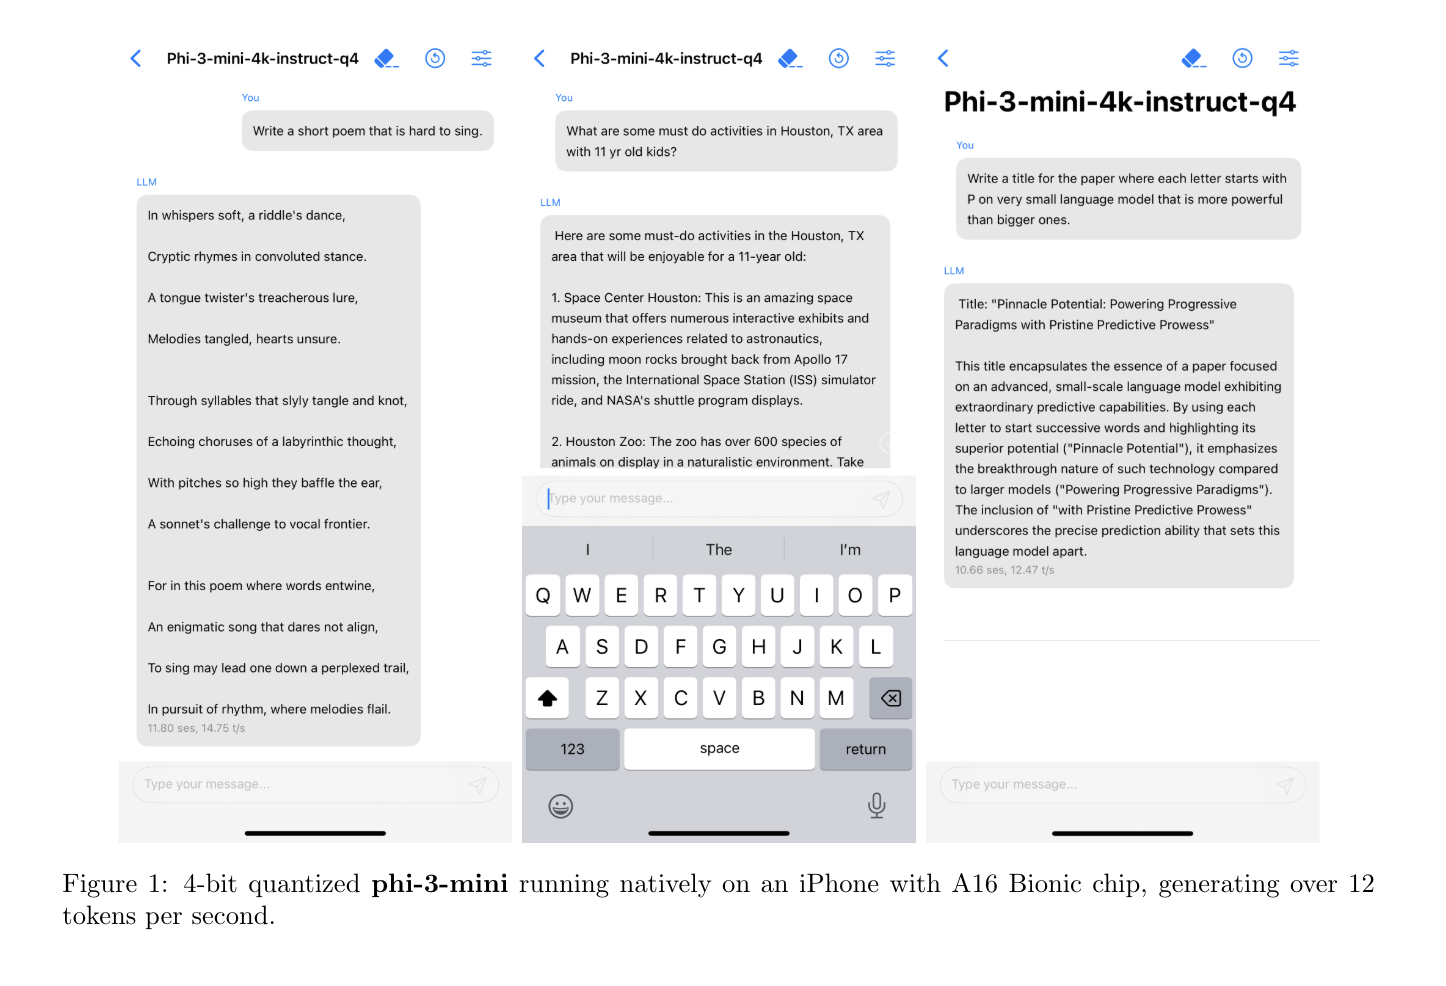
Phi-3-Mini, being highly capable, can run locally on a cell phone. Its small size allows it to be quantized to 4 bits, occupying approximately 1.8GB of memory. Microsoft tested the quantized model by deploying Phi-3-Mini on an iPhone 14 with an A16 Bionic chip, running natively on the device and fully offline, achieving more than 12 tokens per second.
The innovation behind Phi-3-Mini lies in its training dataset, an expanded version of the one used for its predecessor, Phi-2. This dataset comprises heavily filtered web data and synthetic data. The model has also been optimised for robustness, safety, and chat format.
Microsoft has also introduced Phi-3-Small and Phi-3-Medium models, both significantly more capable than Phi-3-Mini. Phi-3-Small, with 7 billion parameters, utilises the tiktoken tokenizer for improved multilingual tokenization. It boasts a vocabulary size of 100,352 and a default context length of 8K.
The Phi-3-small 7 billion parameter model achieves an MMLU score of 75.3 outperforms Meta's recently launched Llama 3 8B Instruct with a score of 66.
The model follows the standard decoder architecture of a 7B model class, featuring 32 layers and a hidden size of 4096. To minimise KV cache footprint, Phi-3-Small employs a grouped-query attention, with four queries sharing one key.
Additionally, it utilises alternative layers of dense attention and a novel blocksparse attention to optimise KV cache savings while maintaining long context retrieval performance. An additional 10% multilingual data was used for training this model.
However, Phi-3-Mini has its limitations. While it demonstrates a similar level of language understanding and reasoning ability as much larger models, it is fundamentally limited by its size for certain tasks. For example, it lacks the capacity to store extensive "factual knowledge," resulting in lower performance on tasks such as TriviaQA.
Microsoft believes such weaknesses can be addressed by augmenting the model with a search engine. Additionally, the model's language capabilities are mostly restricted to English, highlighting the need to explore multilingual capabilities for Small Language Models.

Your reaction
Discussion
What's your take on this story?
No comments yet — be the first to share your view.