Key takeaways
- Soket AI Labs launches Pragna-1B, India's first open-source multilingual Indic language model.
- Model supports Hindi, Gujarati, Bangla, and English, enhancing AI accessibility across diverse languages.
- Pragna-1B features 1.25 billion parameters and a context length of 2048 tokens, ensuring efficient performance.
- Despite its size, it matches larger models, delivering culturally relevant outputs for Indian contexts.
- Engineered for on-device deployment, Pragna-1B promotes inclusive technology within India's linguistic landscape.
Soket AI Labs has introduced Pragna-1B, India's first open-source multilingual model designed to cater to the linguistic diversity of the country.
Available in Hindi, Gujarati, Bangla, and English, Pragna-1B represents a significant step towards inclusive AI technology, transcending linguistic barriers and enhancing user engagement across diverse linguistic landscapes.
Click here to check out the model on Hugging Face.
Pragna-1B features a Transformer Decoder-only model with 1.25 billion parameters and a context length of 2048 tokens. Pragna-1B's training involved 1.25 billion parameters, focusing on Hindi, Bangla, and Gujarati, processing approximately 150 billion tokens.
It is engineered for efficient deployment on-device, Pragna-1B delivers state-of-the-art performance for vernacular languages in a small form factor.
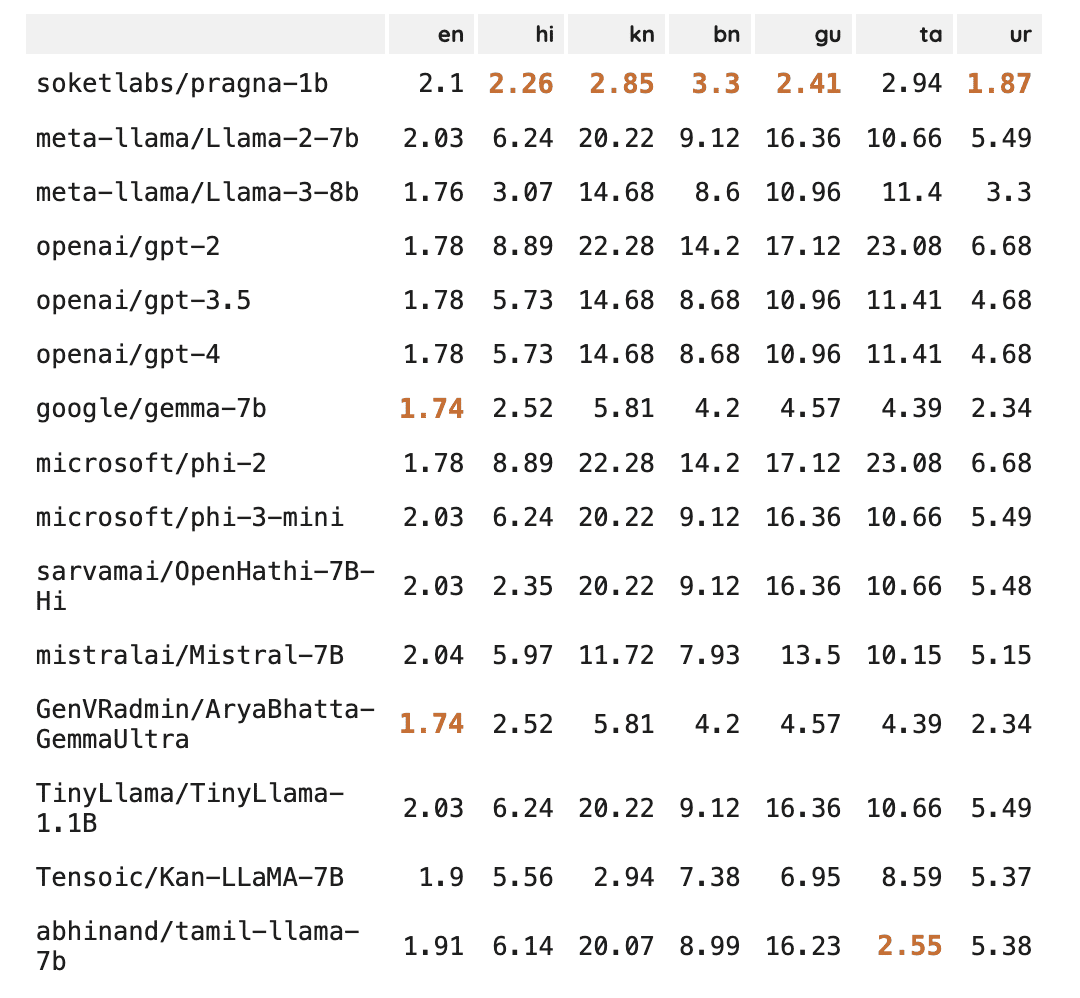
Despite its modest parameter count, Pragna-1B's performance matches that of larger 7 billion parameter models, offering comprehensive multilingual support for English, Hindi, Bangla, and Gujarati.
The model is meticulously trained on curated datasets specifically designed to encompass the Indian context, Pragna-1B ensures accurate and culturally relevant outputs.
Pragna-1B is a decoder-only transformer model inspired by TinyLlama, with the following specifications:
- Layers: 22
- Attention Heads: 32
- Context Length: 2048
- Hidden Dimension: 2048
- Expansion Dimension: 5632
- Vocabulary Size: 69632
Pragna employs a Byte-Pair Encoding (BPE) tokenizer, specifically trained for handling Indian languages, achieving a vocabulary size of 69,632.
Soket AI Labs created "Bhasha," a series of high-quality datasets specifically designed for training Indian language models.
- Bhasha-wiki: Includes 44.1 million articles translated from English Wikipedia into six Indian languages.
- Bhasha-wiki-indic: A refined subset of Bhasha-wiki, focusing on content relevant to India.
- Bhasha-SFT: Facilitates the development of language models for various NLP tasks.
The researchers are also experimenting with a Mixture of experts model, expanding the languages, along with different architectures for increasing optimisation.