
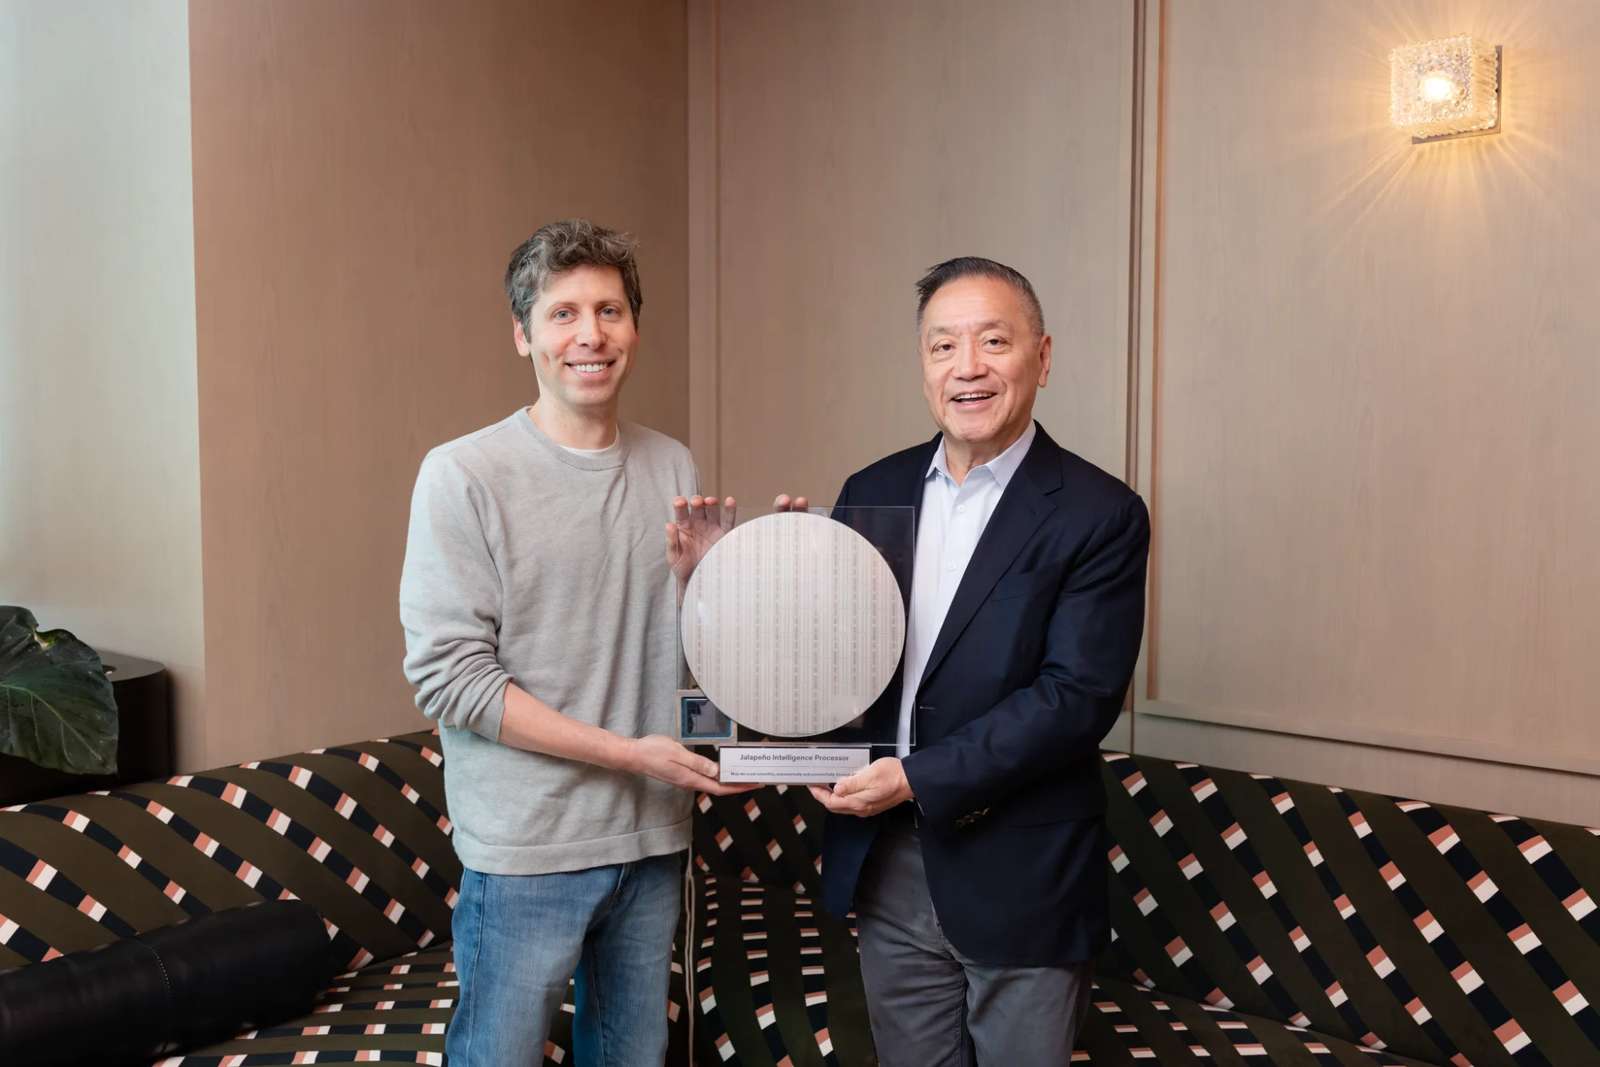
OpenAI and Broadcom have unveiled Jalapeño, a custom AI accelerator built for large language model (LLM) inference. The chip is OpenAI’s first in-house Intelligence Processor and reflects the company’s effort to build more of the infrastructure behind its AI products.
The companies said the chip was designed specifically for LLM inference rather than being adapted from existing AI accelerators. Engineering samples are already running machine learning workloads in the lab, including GPT-5.3-Codex-Spark, with OpenAI claiming early tests indicate the chip delivers performance per watt above current state-of-the-art systems.
Jalapeño is the first product in a multi-generation compute platform being developed by OpenAI and Broadcom, with deployments planned at gigawatt-scale data centres beginning in 2026 alongside partners including Microsoft.
“The world is moving to a compute-powered economy,” said Greg Brockman, President and Co-founder of OpenAI. “Jalapeño is part of our long-term full-stack infrastructure strategy to make compute more abundant, resulting in AI which is faster, more reliable, more affordable for people and businesses, and can be used to solve more important problems.”
OpenAI said the chip was designed using insights from its model roadmap, serving systems, kernels and product requirements. Broadcom contributed silicon implementation and networking technologies, while Celestica worked on board, rack and system integration.
According to the companies, the architecture is intended to reduce data movement and better balance compute, memory and networking resources, allowing the hardware to operate closer to its theoretical performance limits.
“Jalapeño was designed from the ground up for LLM inference using detailed insights from our close collaboration with OpenAI researchers,” said Richard Ho, who leads OpenAI’s hardware program. “We optimised the architecture around the kernels, memory movement, networking, and serving patterns that matter most for frontier AI models.”
The announcement comes as AI companies seek alternatives to relying entirely on third-party accelerators for inference workloads. OpenAI said designing its own hardware allows it to optimise the stack across models, software, networking and infrastructure.
The company also claimed the accelerator moved from initial design to manufacturing tape-out in nine months, which it described as one of the fastest ASIC development cycles in advanced semiconductor development. OpenAI said its own AI models were used to accelerate parts of the chip design and optimisation process.
“The same models served to users are helping improve the infrastructure used to run future models,” the company said, adding that AI-assisted chip development could lower compute costs across the industry.
Broadcom CEO Hock Tan said the partnership extends beyond a single chip generation.
“Our collaboration with OpenAI represents a fundamental commitment to scaling the physical infrastructure required for the next decade of AI,” Tan said. “This is just the beginning of a multi-generation roadmap.”
OpenAI said improvements in inference efficiency could translate into faster ChatGPT responses, lower API costs, and more dependable access during periods of high demand. The company plans to share detailed technical performance data for Jalapeño in the coming months.
- AI Productivity to Add $28 Billion to $84 Billion to India's GDP: Cognizant Study
- OpenAI's Codex Helps in Aerodynamic Engineering for Mazda
- Bengaluru Accounts for 34% of India's FDE Talent: Report
- 84% See AI Productivity Gains, but Only 10% Allow Agent Autonomy: TCS Study
- Snowflake Introduces Business Ontology, Cortex AI Gateway to Bring AI Agents Into Enterprise Workflows
- Three Members Behind Claude Code Leave Anthropic Within 10 Days