
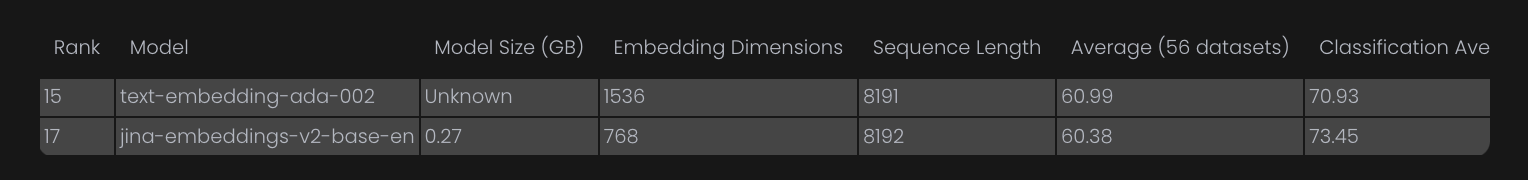
Berlin-based Jina AI has unveiled its latest achievement, the second-generation text embedding model known as jina-embeddings-v2. This groundbreaking model boasts an impressive context length of 8,192 tokens, a milestone that places it in direct competition with OpenAI's proprietary model, text-embedding-ada-002, on both the Massive Text Embedding Benchmark (MTEB) leaderboard and in terms of capabilities.
Check out the model on Hugging Face.
Jina AI's jina-embeddings-v2, when directly compared to OpenAI's 8K model text-embedding-ada-002, demonstrates its mettle. Notably, jina-embedding-v2 surpasses its OpenAI counterpart in terms of Classification Average, Reranking Average, Retrieval Average, and Summarization Average.
jina-embeddings-v2 was meticulously crafted from the ground up through intensive research and development, data collection, and fine-tuning. The result is a model that represents a significant leap from its predecessor.
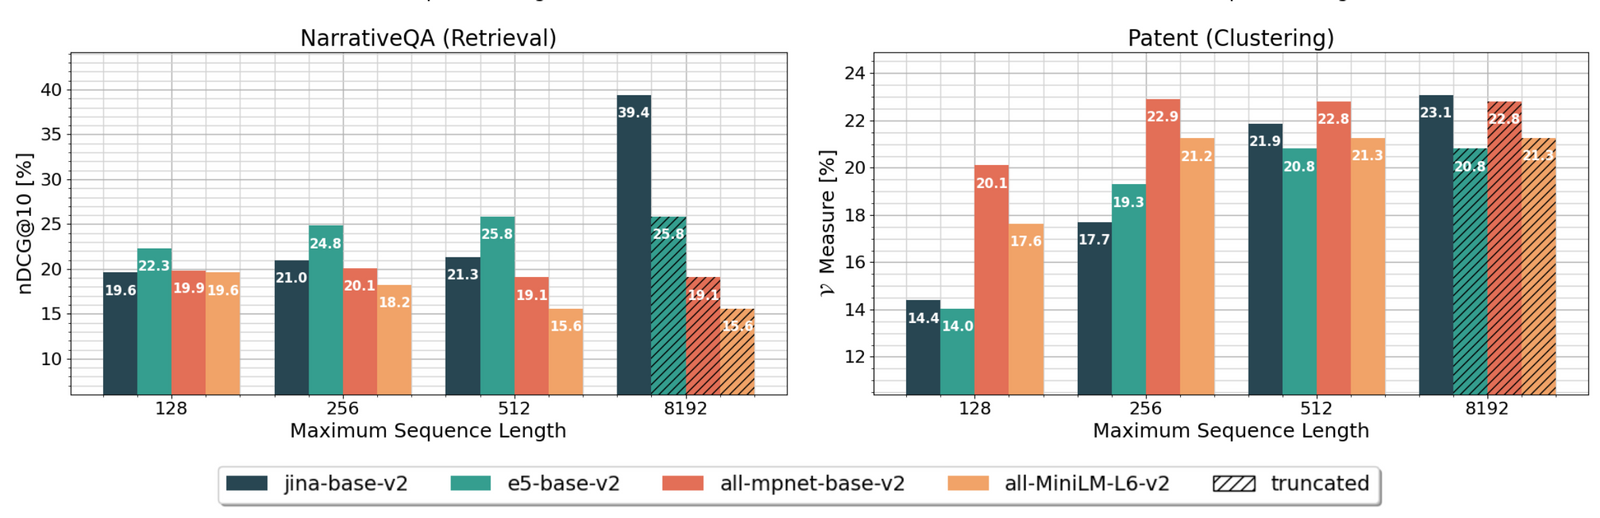
Beyond its technical achievement, jina-embeddings-v2's 8K context length opens new doors for various industry applications, including legal document analysis, medical research, literary analysis, financial forecasting, and conversational AI. Benchmarking shows that this extended context allows jina-embeddings-v2 to outperform other leading base embedding models in several datasets, highlighting the practical advantages of longer context capabilities.
Reflecting on this, Dr. Han Xiao, CEO of Jina AI, shared his thoughts: "in the ever-evolving world of AI, staying ahead and ensuring open access to breakthroughs is paramount. With jina-embeddings-v2, we've achieved a significant milestone. Not only have we developed the world's first open-source 8K context length model, but we have also brought it to a performance level on par with industry giants like OpenAI. Our mission at Jina AI is clear: we aim to democratise AI and empower the community with tools that were once confined to proprietary ecosystems. Today, I am proud to say, we have taken a giant leap towards that vision."
A forthcoming academic paper detailing the technical intricacies and benchmarks of jina-embeddings-v2 will provide the AI community with deeper insights.
Jina AI is setting its sights on launching German-English models, further expanding its repertoire as it continues to advance and democratise artificial intelligence through open source and open science.
- Coforge Revenue Rises 54% as AI Engineering and Deal Bookings Gain Momentum
- Tech Mahindra Partners With SpaceXSI to Bring AI Into Software Engineering
- Infosys AI Revenue Rises 29% in Q2, FY27 Growth Guidance Cut
- LTM Launches BlueVerse Industrial AI Lab in Chennai
- Chariot Launches Speech Recognition Model for 10 Indian Languages
- Meta Expects Up To $145 Billion In Capex As AI Investments Expand