
The launch of AI generators has taken the internet by the storm, with the launch of OpenAI's DALLE-2 text-to-image generator and Meta’s text-to-video AI tool, Make-A-Video.
To combat this, Google in a blog post on Thursday, announced Imagen Video, a text-to-video AI generator that can produce 1280x768 videos – at 24 frames per second – from a written prompt. Currently, in the research phase, Google Imagen adds to the rapid development of video synthesis models.
According to Google's research paper, the newly launched AI generator has several stylistic abilities, such as generating videos of artwork by famous painters, 3D rotating objects while preserving object structure, and rendering text by various animation styles. An excerpt of the paper reads, “Our work aims to generate videos from the text. Prior work on video generation has focused on more restricted datasets with autoregressive models, latent-variable models with autoregressive priors, and more recently non-autoregressive latent-variable approaches.”

Source: Google
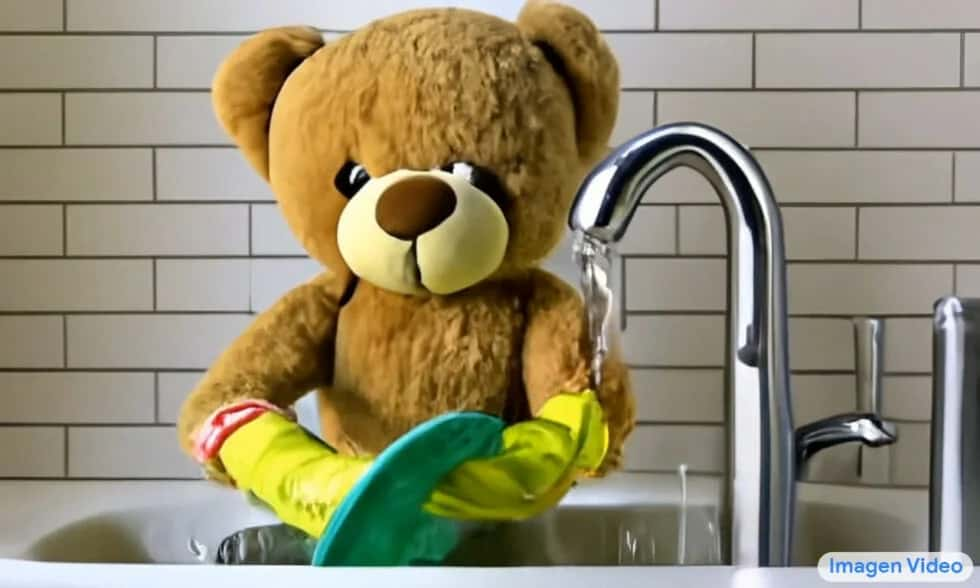
Imagen Video's abilities consists of a "cascade" of seven diffusion models that transform the initial text prompt (such as "a bear washing the dishes") into a low-resolution video (16 frames, 24×48 pixels, at 3 fps). The AI generator upscales the output into progressively higher resolutions with higher frame rates with each step. The final output video is 5.3 seconds long.
At present, the firm has decided not to release the model or its source code due to ‘safety and ethical challenges’ with AI-based video. As the AI and text encoder is trained on problematic data, Google states that there are "social biases and stereotypes which are challenging to detect and filter”. “We have decided not to release the Imagen Video model or its source code until these concerns are mitigated,” said Google.
- Coforge Revenue Rises 54% as AI Engineering and Deal Bookings Gain Momentum
- Tech Mahindra Partners With SpaceXSI to Bring AI Into Software Engineering
- Infosys AI Revenue Rises 29% in Q2, FY27 Growth Guidance Cut
- LTM Launches BlueVerse Industrial AI Lab in Chennai
- Chariot Launches Speech Recognition Model for 10 Indian Languages
- Meta Expects Up To $145 Billion In Capex As AI Investments Expand