Key takeaways
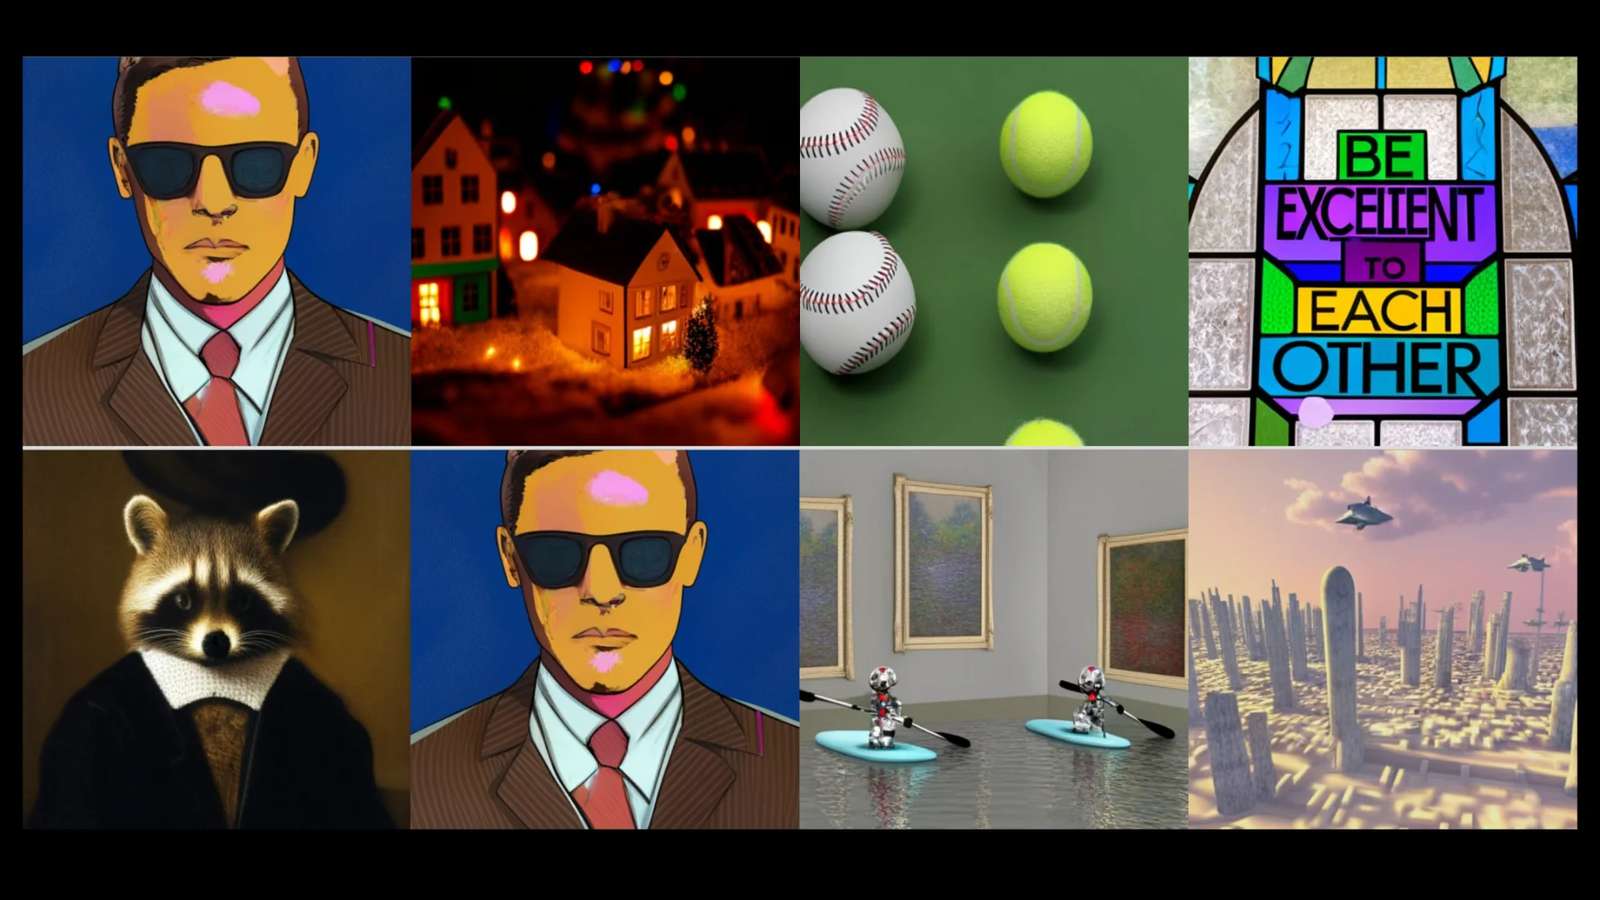
- Google's Muse is a new text-to-image Transformer model that claims to deliver state-of-the-art image generation.
- The model employs a compressed, discrete latent space for faster processing and parallel decoding methods.
- Muse's training involves predicting masked image tokens, making it more efficient than traditional pixel-space diffusion models.
- It offers advanced editing capabilities like zero-shot and mask-free editing based on text prompts.
- The model's fine-grained language understanding enhances its ability to generate high-fidelity images and comprehend complex visual concepts.
Since the beginning of 2021, advances in AI research have been revolutionised with the birth of a plethora of deep learning-backed text-to-image models like DALL-E-2, Stable Diffusion, and Midjourney, to name a few. Adding to the list is Google’s Muse, a text-to-image Transformer model that claims to achieve state-of-the-art image generation performance.
Given the text embedding obtained from a large language model (LLM) that has already been trained, Muse is trained on a masked modelling task in discrete token space. Muse has been trained to predict randomly masked image tokens. Muse asserts to be more effective than pixel-space diffusion models like Imagen and DALL-E 2 since it uses discrete tokens and requires fewer sample iterations. The model generates a zero-shot, mask-free editing for free by iteratively resampling image tokens conditioned on a text prompt.
Check out more about Muse here.
Unlike Parti and other autoregressive models, Muse uses parallel decoding. A pre-trained LLM enables fine-grained language understanding, translating to high-fidelity image generation and comprehending visual concepts such as objects, their spatial relationships, pose, cardinality, etc. Additionally, Muse supports inpainting, outpainting, and mask-free editing without the need to modify or invert the model.
With an FID score of 6.06, the 900M parameter model achieves a new SOTA on CC3M. On zero-shot COCO evaluation, the Muse 3B parameter model obtains an FID of 7.88 and a CLIP score of 0.32.
Model Architecture:
For both the base and super-res Transformer layers, the text encoder creates a text embedding that is used for cross-attention with image tokens. The base model then uses a VQ Tokenizer that generates a 16*16 latent space of tokens after being pre-trained on lower resolution (256*256) images. The cross-entropy loss then learns to predict the masked tokens that have been masked at a variable rate for each sample. After training the base model, the reconstructed lower-resolution tokens and text tokens are then fed into the super-res model. Now the model can predict masked tokens at a higher resolution.
Spotted an error? Tell our editors. Read our editorial standards and corrections.