

For decades, the global technology narrative had followed a predictable script. American venture capital fuelled foundational breakthroughs while China deployed massive, state-directed infrastructure to achieve sheer dominance. India was often relegated to the back office.
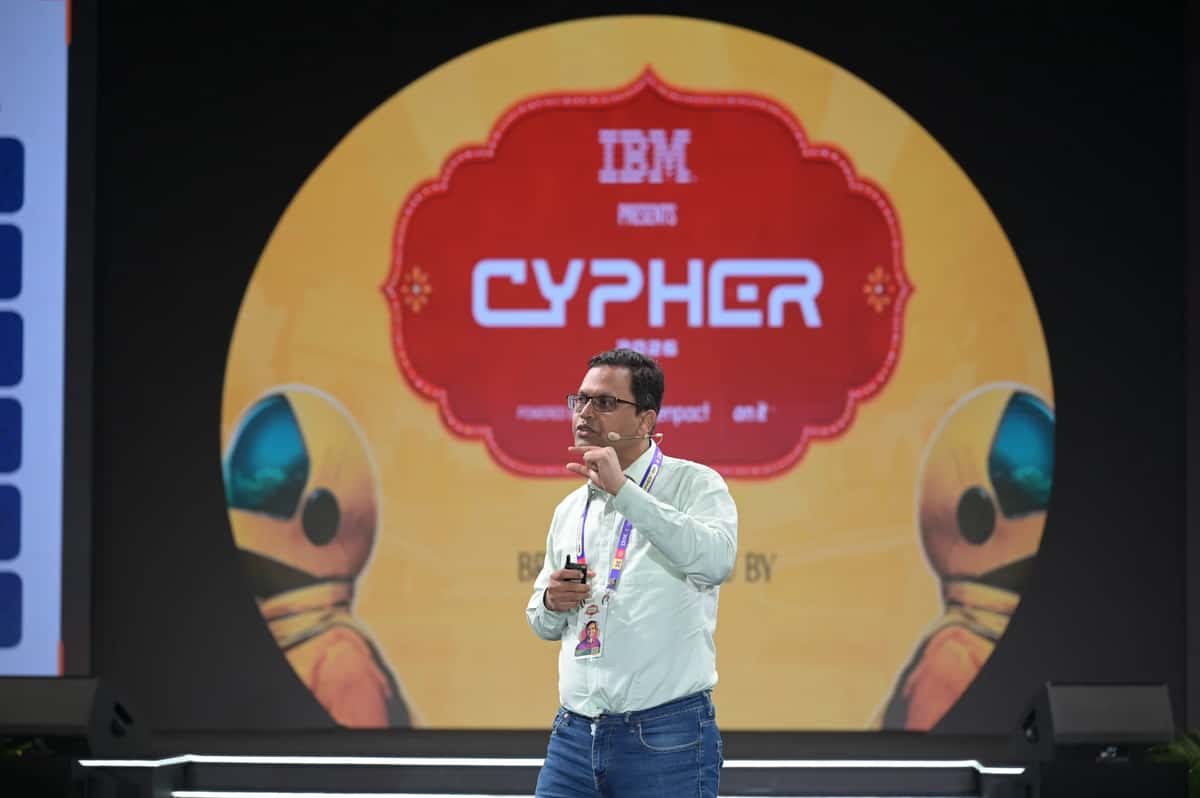
But when Pratyush Kumar, Co-founder of Bengaluru-based Sarvam AI, stepped onto the stage at Cypher 2026 in Bengaluru, he pitched that AI will not be built by a couple of companies.
On day 1 at Cypher, Paytm Founder and CEO Vijay Shekhar Sharma, too raised a similar concern and offered personal funds to founders building their own AI models.
India has the capital, compute and talent to build frontier AI models that compete with OpenAI, Google and Chinese players, but the country needs to overcome its hesitation and start building at scale.
“I don’t see any structural reason not to be doing that,” Kumar said, arguing that building competitive AI models was largely a question of capital, compute and talent rather than a fundamental technological barrier. China, he added, had already demonstrated that it was possible to challenge established AI players.
“Given India’s scale, this is something that we should absolutely be doing,” he said, adding that many of the top technical and business leaders at global technology companies are Indians.
From Access to Advantage
Building AI at scale in India had required rethinking the entire economics of compute. Rather than relying on standard commercial API endpoints that bled enterprise budgets dry, Sarvam had built an infrastructure layer directly on bare-metal GPU clusters.
They had taken a 2,000 Blackwell cluster for real-time inferencing and optimised open architectures, compiling them, parallelizing cache memory, and stripping away unnecessary latency. The result? High-throughput inferencing that ran 5x cheaper than GPT-level models, fully optimized for rapid, high-volume workloads like conversational voice systems and real-time processing.
Today, frontier models are widely available, allowing companies to experiment with AI across coding, cybersecurity, document processing, voice, and enterprise reasoning.
Addressing a packed room of tech leaders and product teams, he emphasised that raw access to top-tier AI models no longer creates a competitive moat. Instead, the real strategic edge lies in an enterprise's ability to turn its massive daily transaction volume into a self-learning loop that continually strengthens the business.
Describing a meeting with a large shipping company that generates vast amounts of data across its global operations, he said the company wants to turn its operational strengths, data, and talent into an AI advantage. The key question, he said, is: “What is it that I am compounding on as I use AI?”
Own the Stack, Train the Model
To build AI capabilities, Kumar argues, enterprises need greater control over the underlying infrastructure. “You cannot play the AI game and own that stack unless you have compute,” he says.
Sarvam pre-trained its 105 billion-parameter model on 4,000 H100 graphics processing units (GPUs). The model also powers its Indus assistant.
Above the compute layer sit models, a context engine, harnesses, agents and a control plane. Kumar sees enterprise context as a capability that can accumulate value even as the underlying models change. “A thing that will continue to compound is if enterprises clean up their context,” he says.
Harnesses can compensate for a model’s weaknesses. Kumar says Sarvam improved an open-source coding harness to raise accuracy while keeping the model itself unchanged.
Enterprises will also need controls to manage the systems they deploy. Kumar expects governance spending to grow alongside AI adoption.
“I think for every dollar spent on AI, at least a dollar will be spent on governance because it’s that important,” he says.
Kumar says enterprises can reduce costs by four to 10 times by renting or buying GPUs and hosting open models for their own workloads.
Within two to three years, Kumar expects model fine-tuning to become as straightforward as deploying code. Enterprises will be able to supply their data, trigger training and evaluation, and push a model into production through a largely automated pipeline.
Odisha, Voice Calls and a February Target
Sarvam is applying its model-building approach to a project with the Odisha government to digitise land records. The documents contain printed text, handwriting, strike-offs and notes written over existing entries, making them difficult to process using conventional optical character recognition (OCR).
Kumar says the project would have taken 10 years to complete, while Sarvam aims to finish it in two.
The startup built a 4 billion-parameter OCR model from scratch for the work. Building the model itself gives Sarvam greater control over how it is optimised for the documents, Kumar says.
“Because we built it ourselves, we can optimise it,” he says.
Government staff correct the model’s output, and those corrections feed back into training. Kumar says typical OCR accuracy ranges from 85% to 90%. He puts Sarvam’s base model accuracy on the complex land records at about 30%, adding that it has since crossed 60%.
Voice AI is another part of Sarvam’s business. Kumar says about 450 million voice calls take place on the startup’s platform each year, using its GPUs and models.
Separately, Sarvam is targeting 1 billion voice minutes by March. Its models also support voice-based food ordering on Swiggy through Indus.
Sarvam is also training a 1 trillion-parameter model that Kumar says should be out in February next year. He expects it to handle most enterprise tasks and compete globally across reasoning, vision and audio. At its Epoch conference, Sarvam had outlined plans to release the model within six months.
- AI Can Be Cyborg or Centaur. But Can Enterprises Monetise It?
- AMD’s Server CPU Business Faces a New AI Boom
- How an Engineer Is Using AI to Bridge the Accessible Education Gap
- AI Agents are Making Human Customer Service a Specialist Job
- Why Nandan Nilekani-Backed F2A Believes India's Investment Opportunity Lies in Edge AI
- India Needs to Build the AI 'Brain' for Robotics, Not Just Import Hardware