
Microsoft has introduced a new type of language model called 1-bit LLM, and recent research like BitNet has contributed to this project.
The crux of this innovation lies in the representation of each parameter in the model, commonly known as weights, using only 1.58 bits. Unlike traditional LLMs, which often employ 16-bit floating-point values (FP16) for weights, BitNet b1.58 restricts each weight to one of three values: -1, 0, or 1. This substantial reduction in bit usage is the cornerstone of the proposed model.
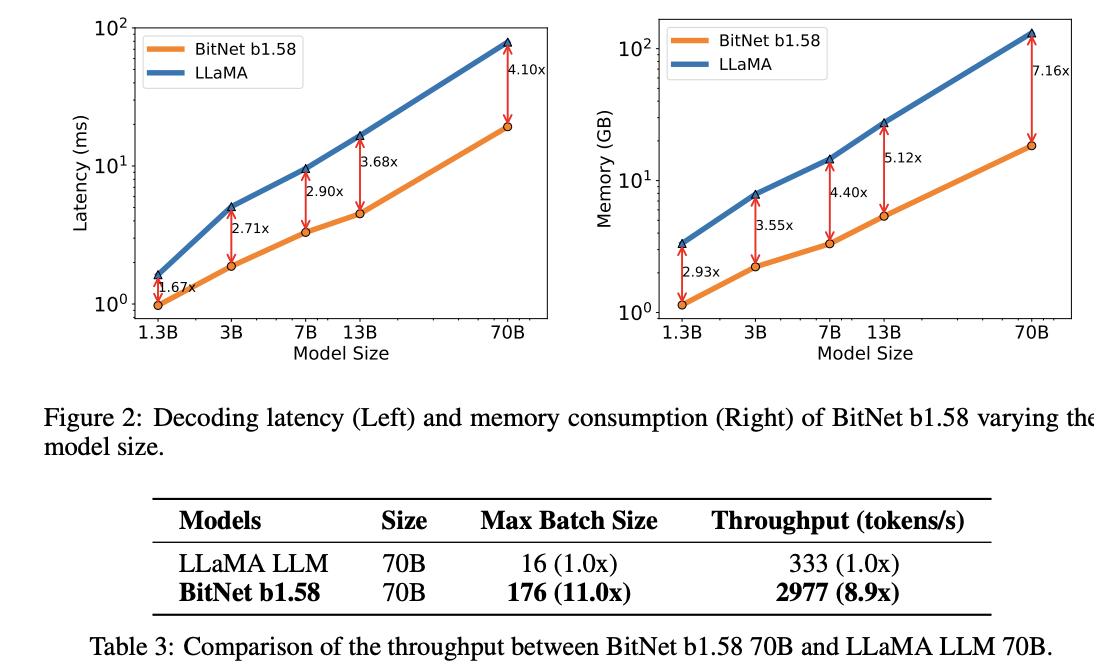
They found that BitNet b1.58, despite using only 1.58 bits per parameter, the model performs as well as the traditional models with the same model size and training data in terms of both perplexity and end-task performance. Importantly, it is more cost-effective in terms of factors like latency, memory usage, throughput, and energy consumption.
This 1.58-bit LLM introduces a new way of scaling and training language models, offering a balance between high performance and cost-effectiveness. Additionally, it opens up possibilities for a new way of computing and suggests the potential for designing specialized hardware optimized for these 1-bit LLMs.
The paper also touches upon the potential for native support of long sequences in LLMs facilitated by BitNet b1.58. The authors suggest future work to explore further lossless compression possibilities, potentially enabling even greater efficiency.
Late last year, Microsoft introduced its latest version of small language model (SML) Phi-2, a 2.7 billion-parameter model outperforming in understanding and reasoning capabilities.
- AI Productivity to Add $28 Billion to $84 Billion to India's GDP: Cognizant Study
- OpenAI's Codex Helps in Aerodynamic Engineering for Mazda
- Bengaluru Accounts for 34% of India's FDE Talent: Report
- 84% See AI Productivity Gains, but Only 10% Allow Agent Autonomy: TCS Study
- Snowflake Introduces Business Ontology, Cortex AI Gateway to Bring AI Agents Into Enterprise Workflows
- Three Members Behind Claude Code Leave Anthropic Within 10 Days