
Snowflake today announced the launch of the Snowflake Arctic embed family of models under an Apache 2.0 licence. These models, ranging in size and context window, are designed for text embedding tasks and offer SOTA performance for retrieval applications.
The largest model in the family, with 330 million parameters, leads the Massive Text Embedding Benchmark (MTEB) Retrieval Leaderboard, achieving an average retrieval performance surpassing 55.9.
Click here to check out the model on Hugging Face.
Sridhar Ramaswamy, CEO of Snowflake highlights the importance and expertise of the Neeva team and commitment to AI for making the model. Snowflake acquired Neeva in May last year.
The Snowflake Arctic embed models, available on Hugging Face and soon in Snowflake Cortex embed function, provide organisations with advanced retrieval capabilities when integrating proprietary datasets with LLMs for Retrieval Augmented Generation (RAG) or semantic search services.
The success of these models lies in the application of effective web searching techniques to training text embedding models. Improved sampling strategies and competence-aware hard-negative mining have significantly boosted the quality of the models.
Snowflake Arctic embed models come in five sizes, from x-small to large, catering to different organisational needs regarding latency, cost, and retrieval performance.
Snowflake claims that Arctic-embed-l stands out as the leading open-source model suitable for production due to its excellent performance-to-size ratio. Although there are models like SFR-Embedding-Mistral that surpass Arctic-embed-l, they come with a vector dimensionality that is four times greater (1024 vs. 4096) and require over 20 times more parameters (335 million vs. 7.1 billion).
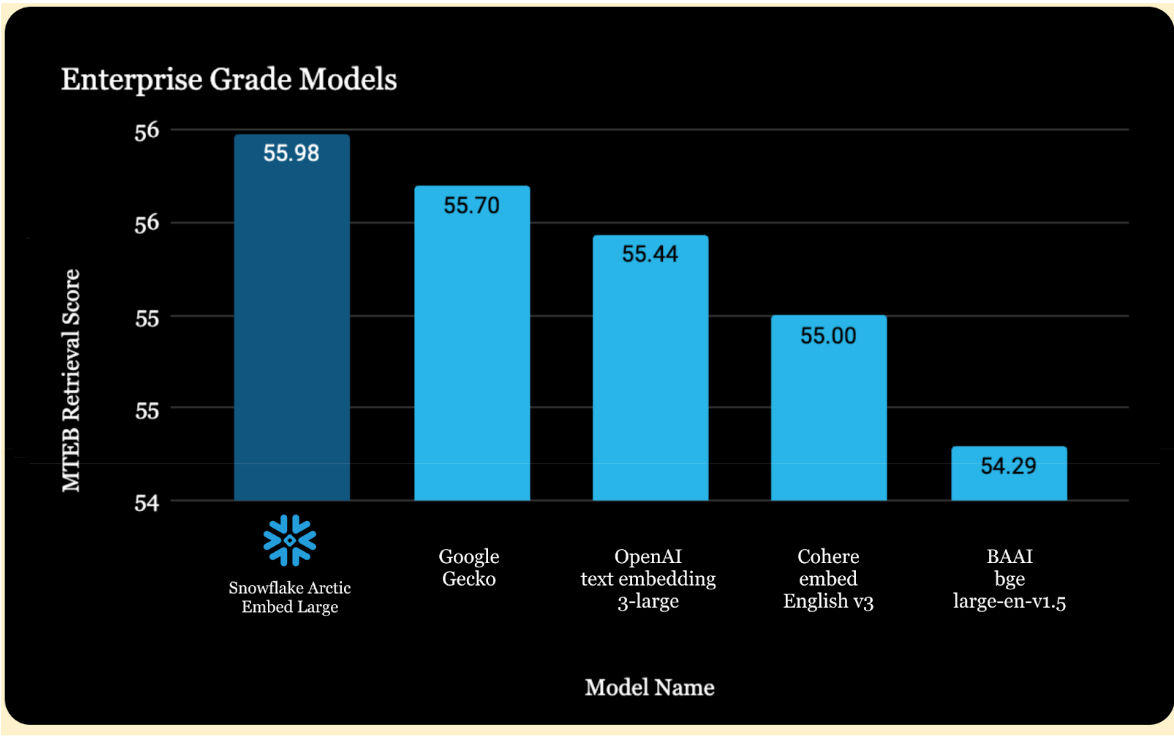
“With the Apache 2 licensed Snowflake Arctic embed family of models, organisations now have one more open alternative to black-box API providers such as Cohere, OpenAI, or Google,” reads Snowflake’s blog.
These enhancements, combined with Snowflake's data processing power, were achieved without the need for a massive expansion of computing resources, utilising just eight H100 GPUs.
Snowflake plans to continue expanding its range of models and targeted workloads to maintain its commitment to providing customers with top-quality models for enterprise use cases such as RAG and search.
- AI Productivity to Add $28 Billion to $84 Billion to India's GDP: Cognizant Study
- OpenAI's Codex Helps in Aerodynamic Engineering for Mazda
- Bengaluru Accounts for 34% of India's FDE Talent: Report
- 84% See AI Productivity Gains, but Only 10% Allow Agent Autonomy: TCS Study
- Snowflake Introduces Business Ontology, Cortex AI Gateway to Bring AI Agents Into Enterprise Workflows
- Three Members Behind Claude Code Leave Anthropic Within 10 Days